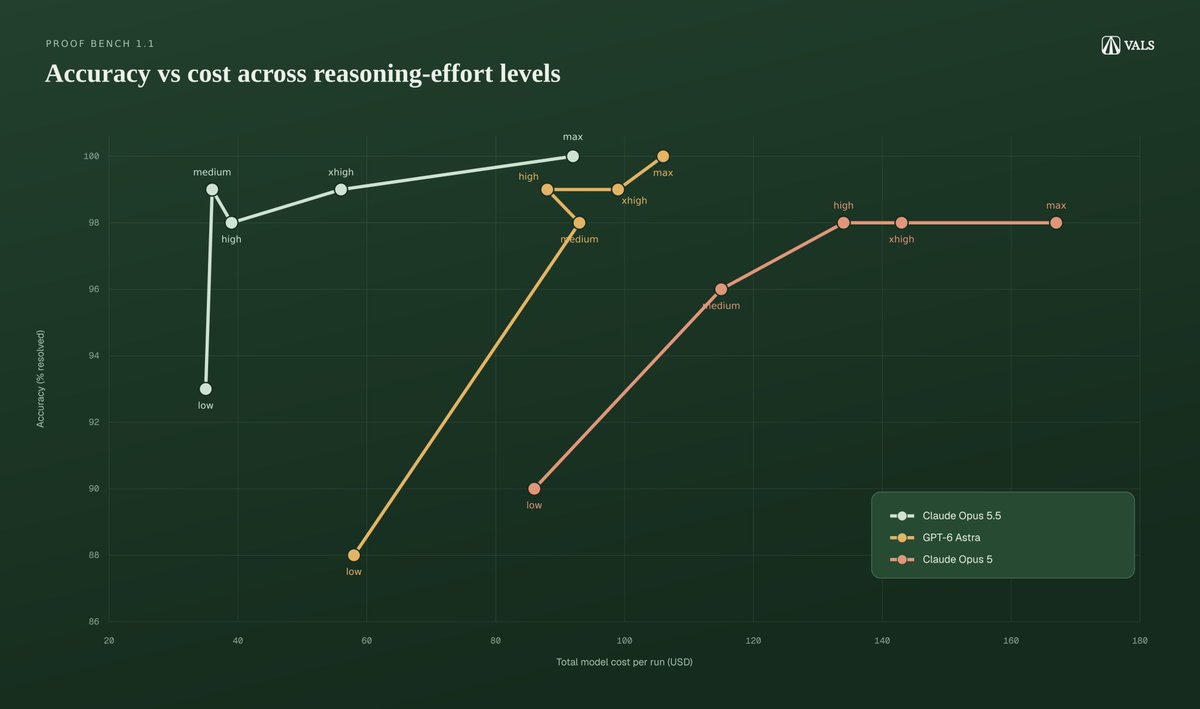
How does "thinking harder" change how models perform on math proofs?
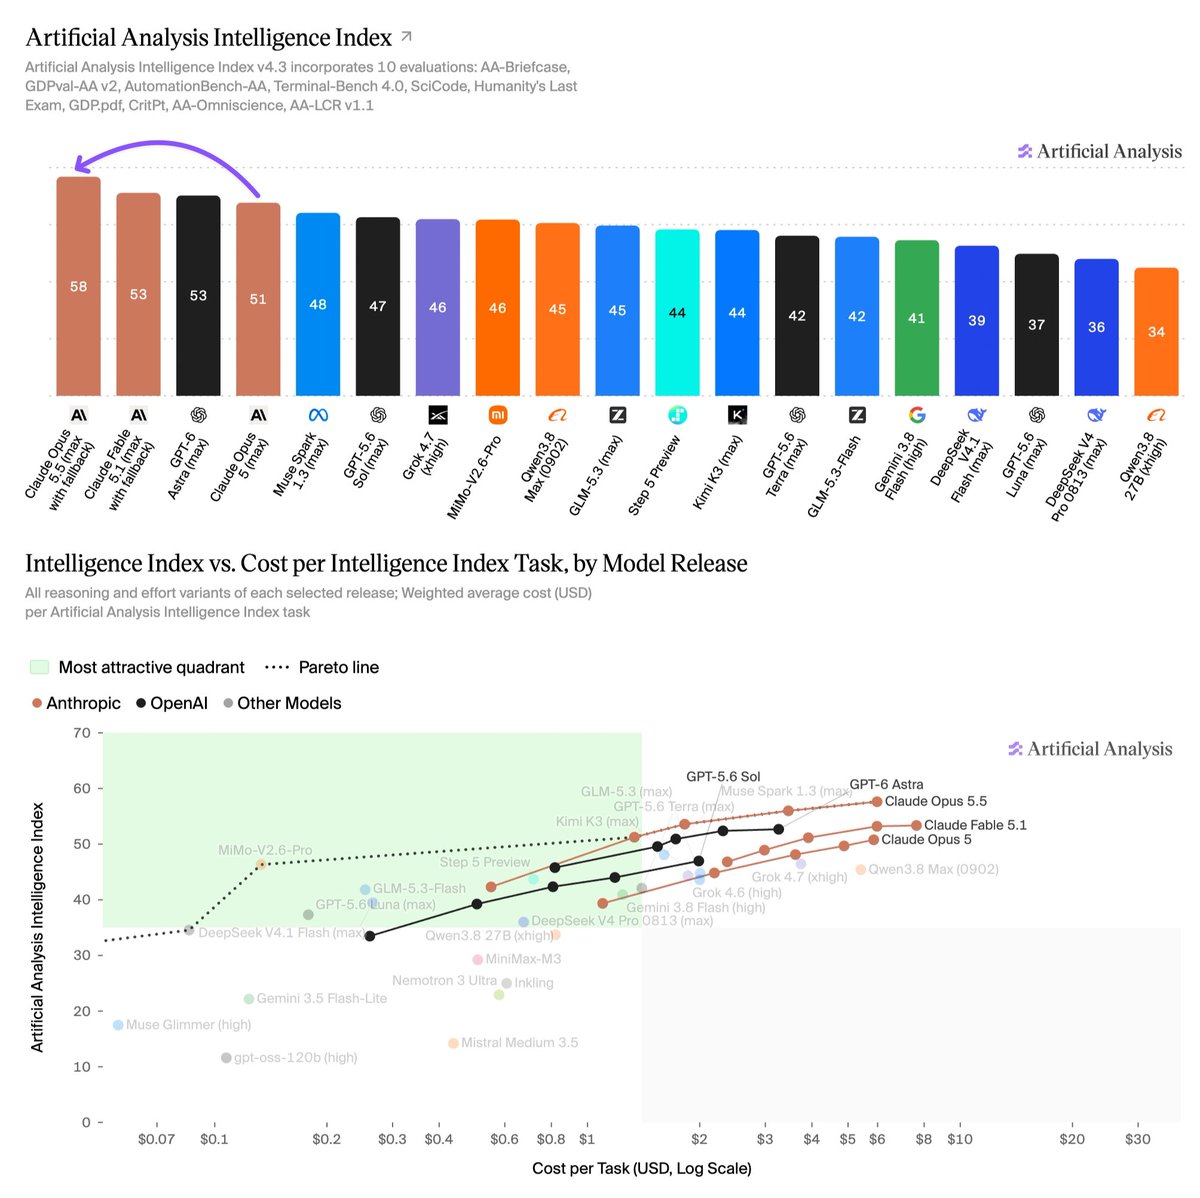
We ran GPT-6 Astra, Opus 5, and Opus 5.5 on every reasoning level: low, medium, high, xhigh, and max on our benchmark, Proof Bench v1.1.
Vals AI's Proof Bench shows Opus 5.5 at medium effort hits 99% accuracy for a fraction of the cost of pushing to max, while some models plateau regardless of added reasoning effort.