FLUX 3: one backbone for image, video, audio and robot action prediction
- Source
- x.com
- Date

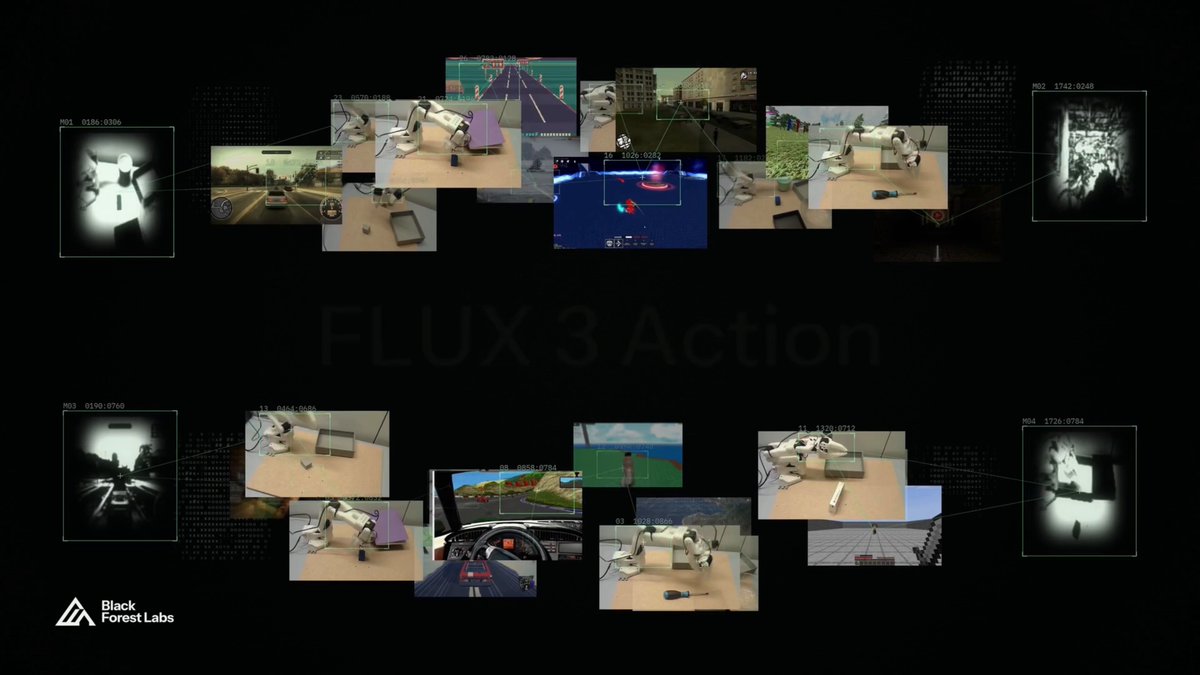
Introducing FLUX 3. One multi-modal model for Image, Video, Audio and Action-Prediction. Creations are truer to life in every kind of style. FLUX 3 Video is now available in early access (link below). Jointly trained in one unified architecture, our model can be extended to predict actions for robotics. See our work with mimic and Audi in the thread.

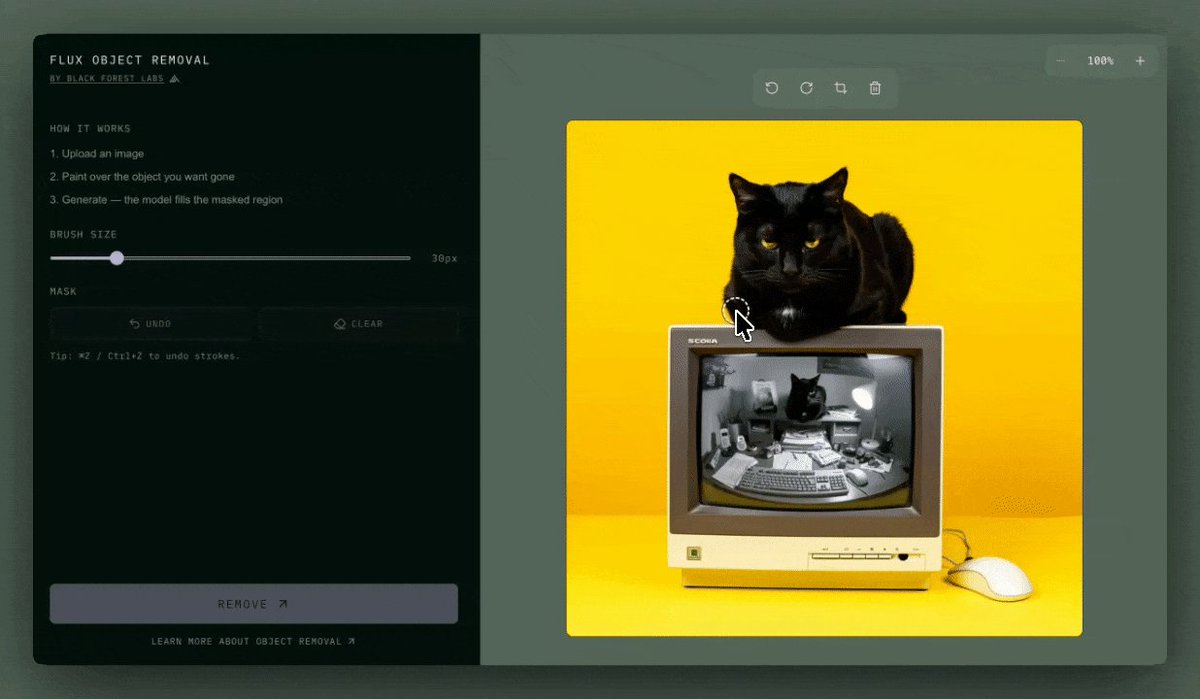
Over the next few weeks and months, we’ll make the following capabilities available, each after an early access phase for ensuring smooth rollout: • Video with native audio generation (now in early access). • Action prediction through selected research and commercial partners. Beginning with mimic robotics. • Image generation and editing (sneak peek below 🎄). • Fast variants and features for iterating cost efficiently. • Open-weight access to a multimodal backbone, for content creation (video, audio and image) and action prediction. FLUX 3 is a checkpoint on our mission to develop real-world visual intelligence: models that perceive, predict, and act across digital and physical environments. Learn more about FLUX 3: https://t.co/aq1oYeiivX
Action: An early version of FLUX 3 is now running on robots. @mimicrobotics was one of the first partners to gain early access to FLUX 3. Together we developed FLUX-mimic, a video-action model combining the FLUX 3 backbone with mimic's expertise in robot learning for dexterous manipulation and production deployment. It’s now running robots that have been tested and deployed at Audi. Read our thesis on why physical AI and content creation run on the same foundation: https://t.co/eg3BrKtXSW
Context
FLUX 3 extends Black Forest Labs' model family toward a shared foundation for images, video, sound and robot actions. The company says it jointly trained the visual and audio capabilities, building on its Self-Flow research. Its launch article describes generating video and audio together and adapting the learned video foundation for action prediction.
The July 23, 2026 announcement began with video early access. Image generation, partner access to action prediction and downloadable weights belonged to a staged rollout. This separates the broader research direction from what users could access at launch: a common underlying model was intended to support several products, with availability expanding in phases. The launch plan spells out that distinction.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Checking sign-in…
Loading comments…