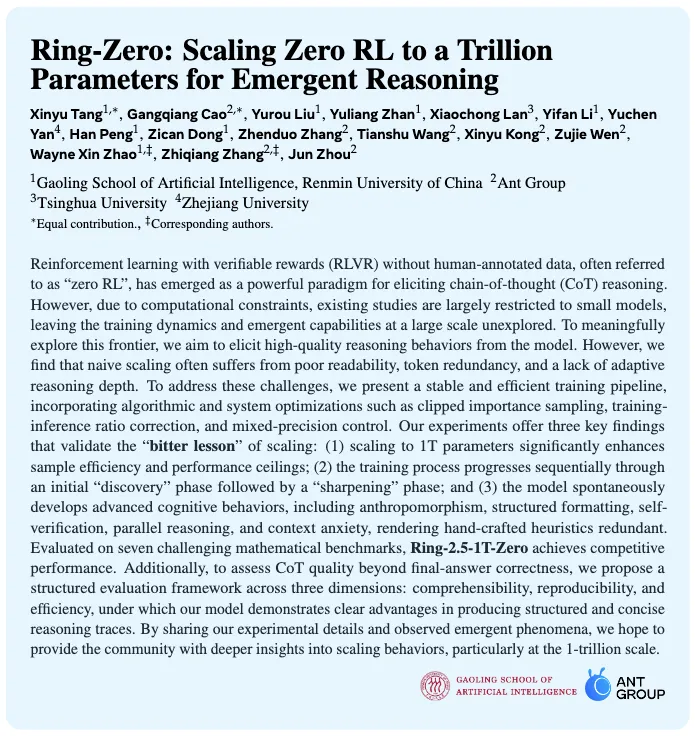
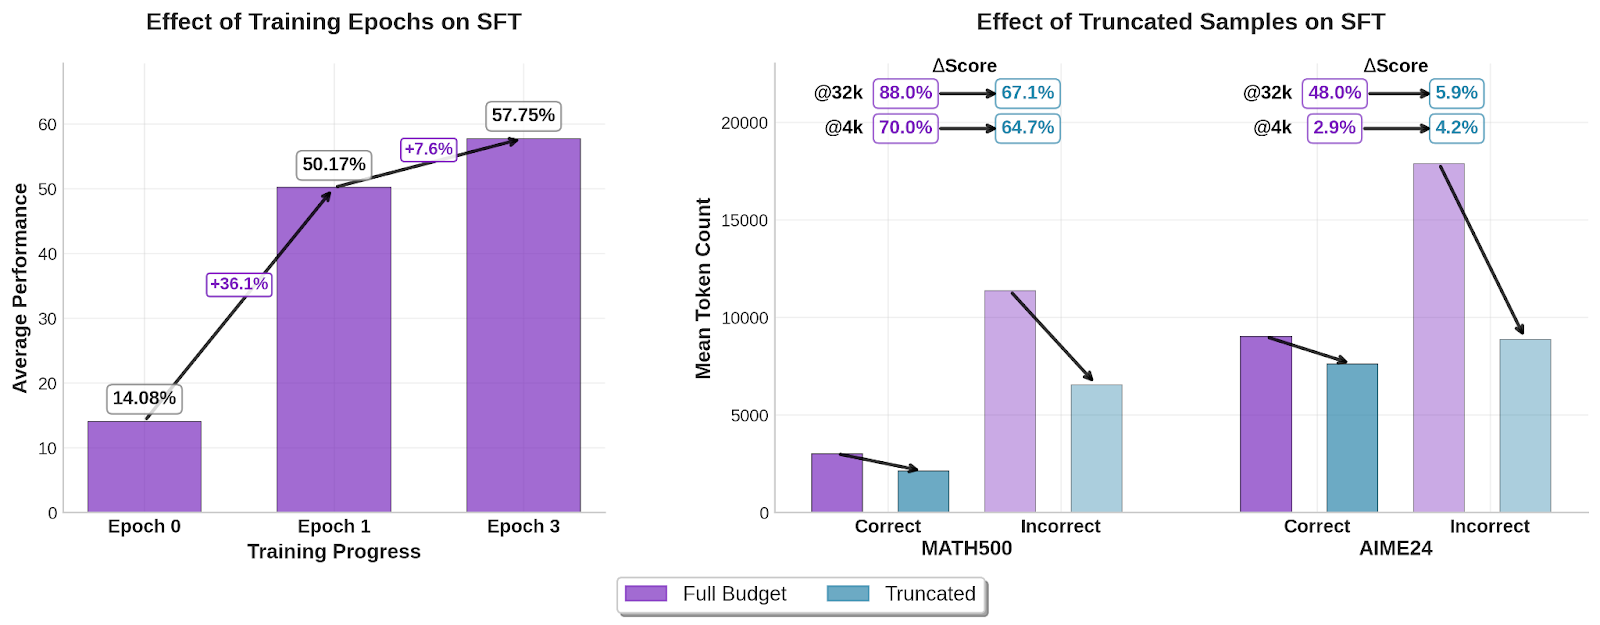
Liquid AI reports that targeted reinforcement learning helped its small math model answer more accurately within a tight response limit. It first trained a 1.3-billion-parameter model on worked solutions, then rewarded concise, correct reasoning with allowances for problem difficulty. Training account.
At a 4,000-token output limit, Table 4 reports an average score increase from 30.09% for the distillationTraining a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.Full definition → checkpoint to 46.98% after reinforcement learning across five math and science benchmarks. Performance declined slightly under the much larger 32,000-token limit. The result supports training specifically for constrained responses, with a tradeoff when longer answers are allowed. Evaluation tables.
Terms in this piece · Glossary
distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
chain-of-thought — Having a model write out intermediate reasoning steps before its answer, which markedly improves performance on hard problems.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
token budget — A cap on how many tokens a task, session, or agent run may consume — the practical control on both cost and how long an agent will grind.
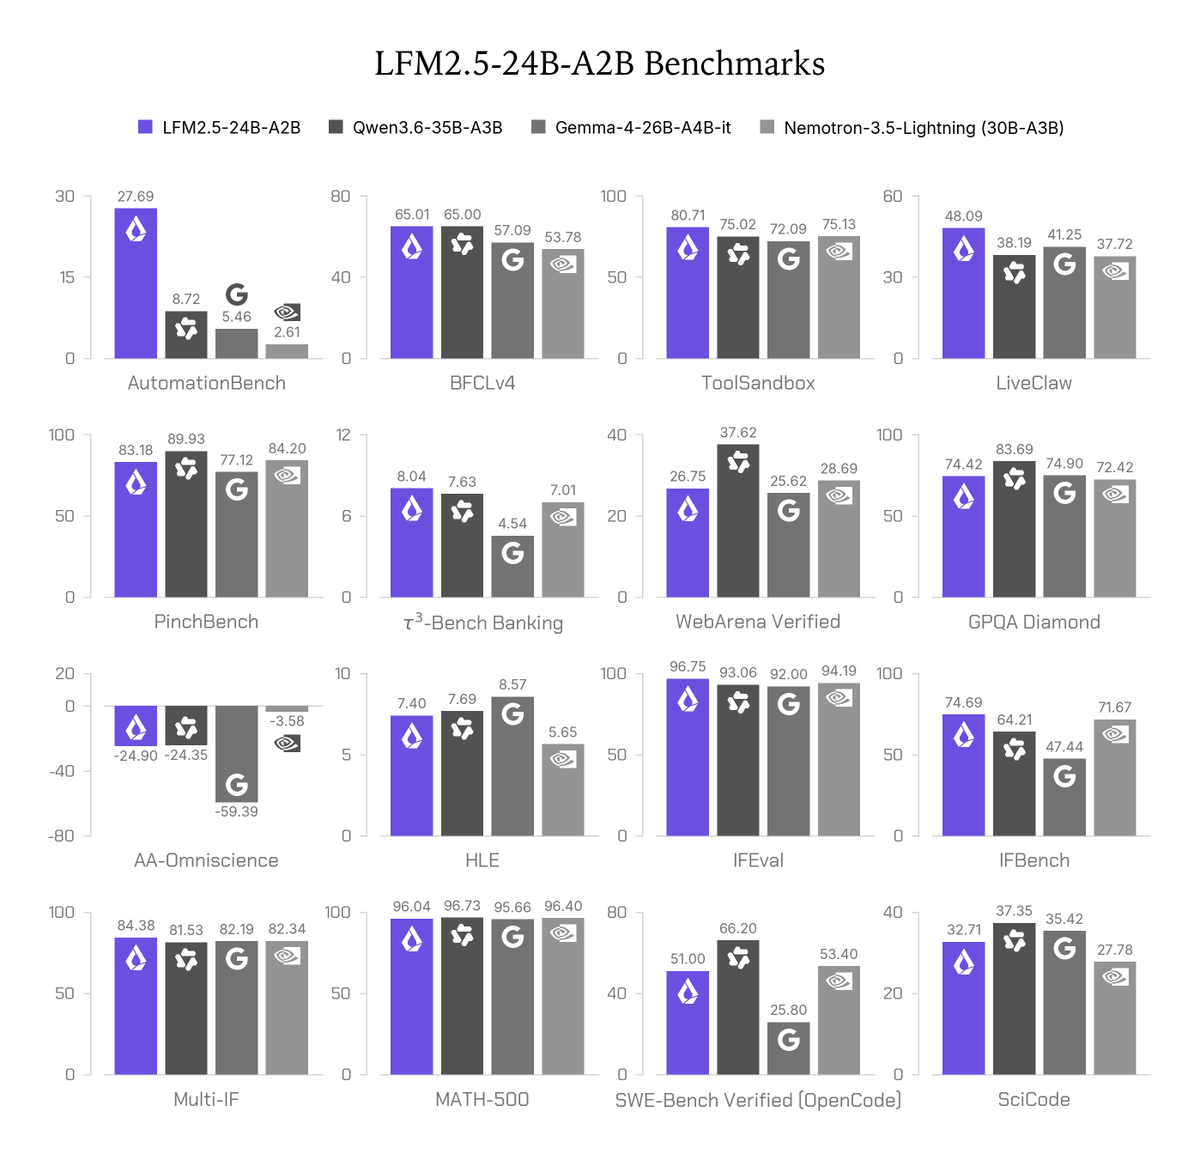 postLiquid AI ships LFM2.5-24B-A2B open weights for local agents
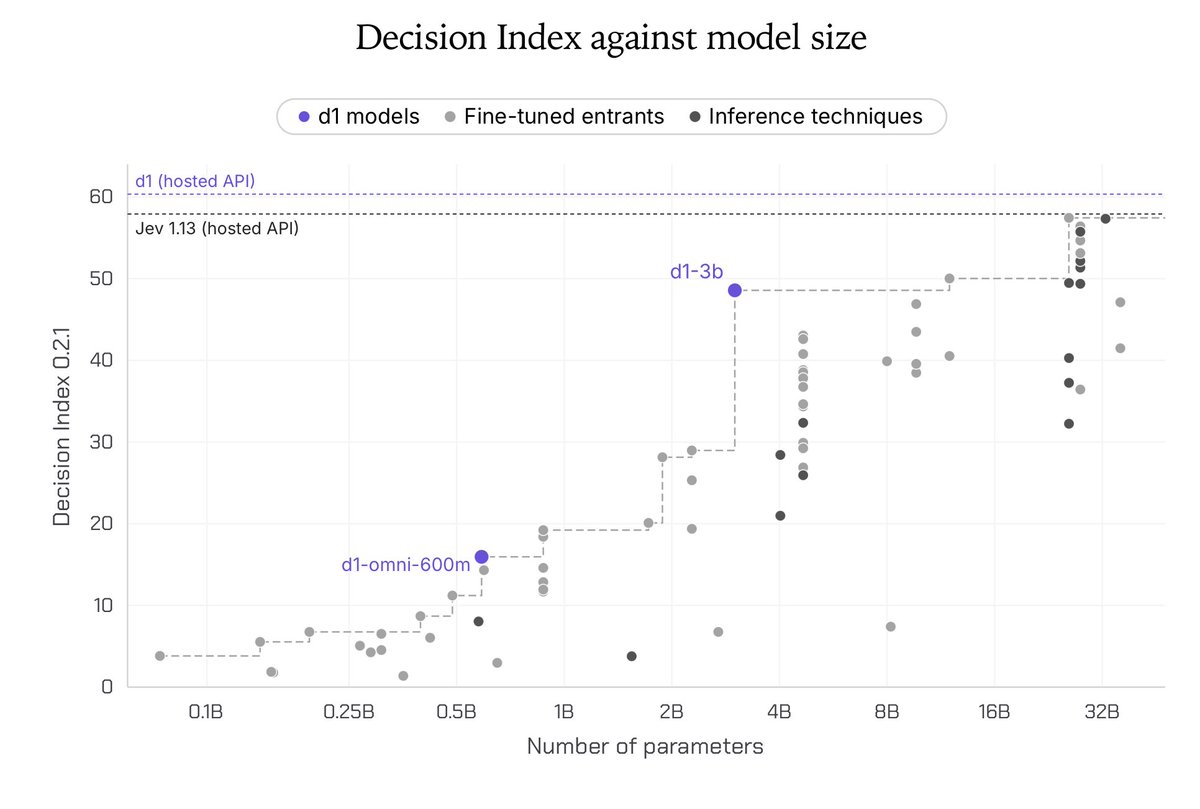 postToday we release Open d1: two open-weight multimodal models in our d1 decision…
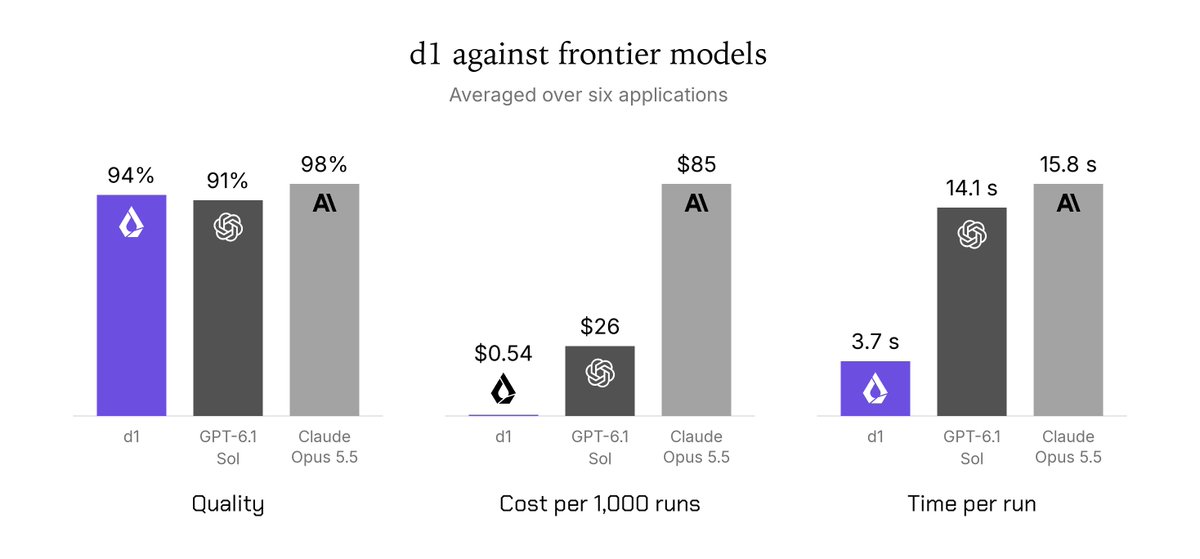 postLiquid AI's d1 decision model adds vision at a fraction of frontier cost
 articled1 is now available on @vercel AI gateway!We worked with the amazing vercel…