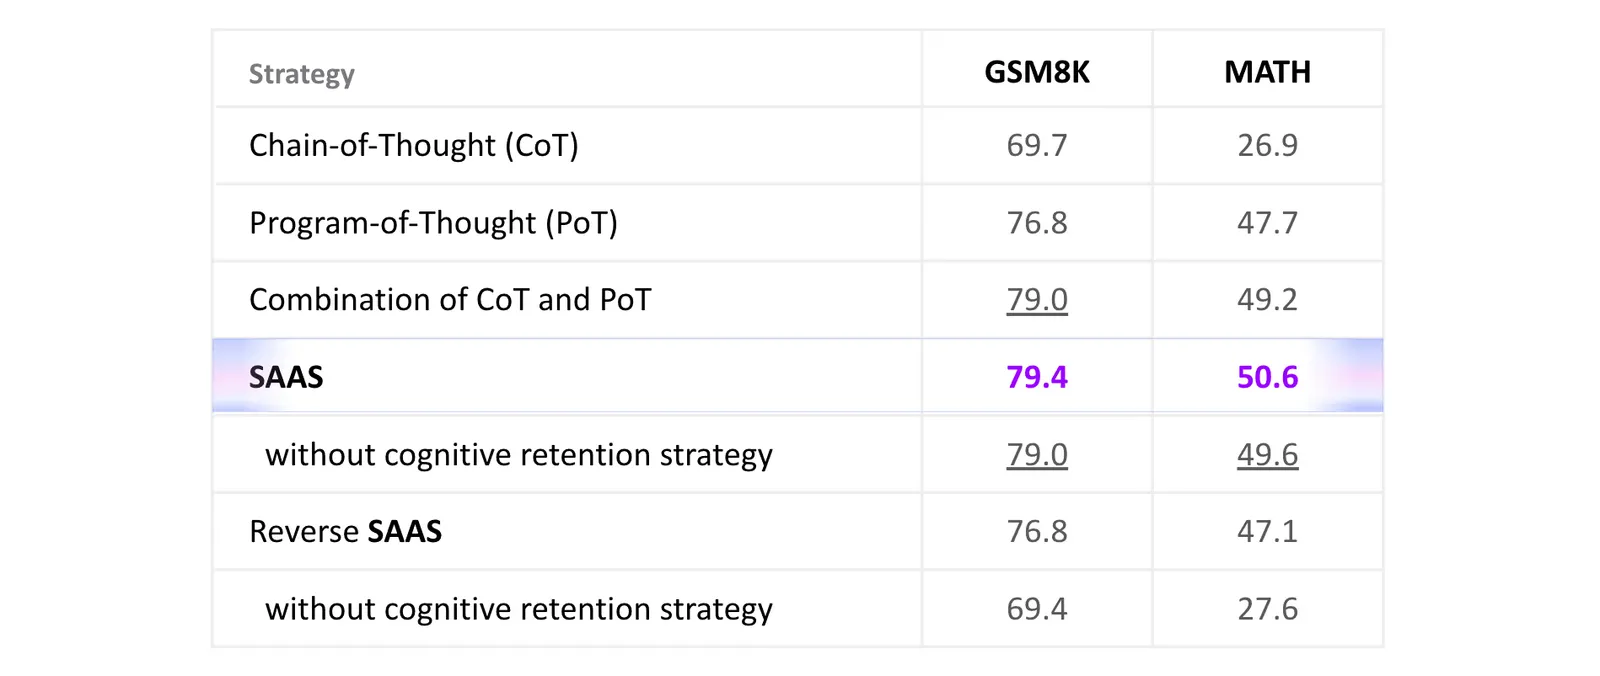
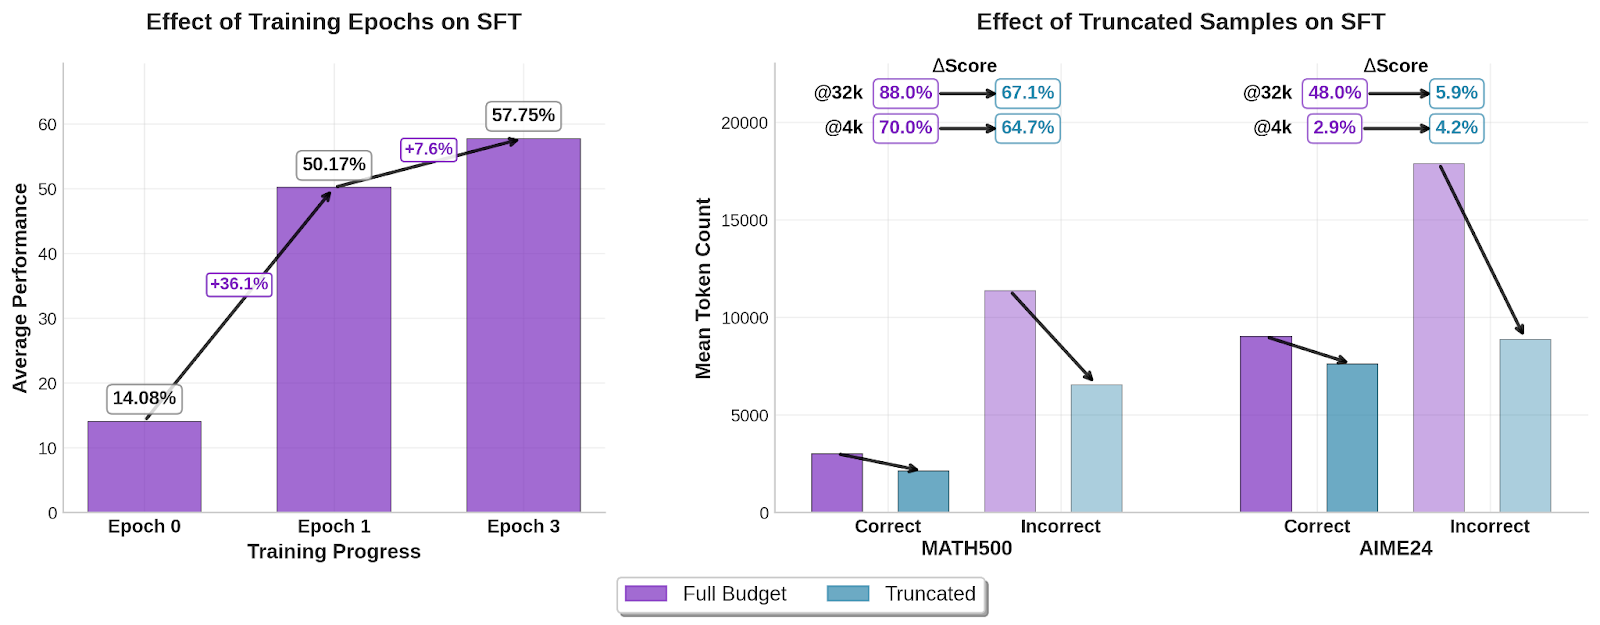
Upstage's SAAS research summary describes teaching a LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → mathematical reasoning in two stages. First, it trains on written, step-by-step solutions. It then trains on solutions expressed as programs, allowing a code interpreter to perform the calculations.
The second stage continues to include written reasoning examples, with the aim of retaining skills learned in the first stage. This separates two sources of difficulty: deciding which steps solve a problem and carrying out their arithmetic correctly. The proposed training sequence tries to preserve the former while using executable code for the latter.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
chain-of-thought — Having a model write out intermediate reasoning steps before its answer, which markedly improves performance on hard problems.