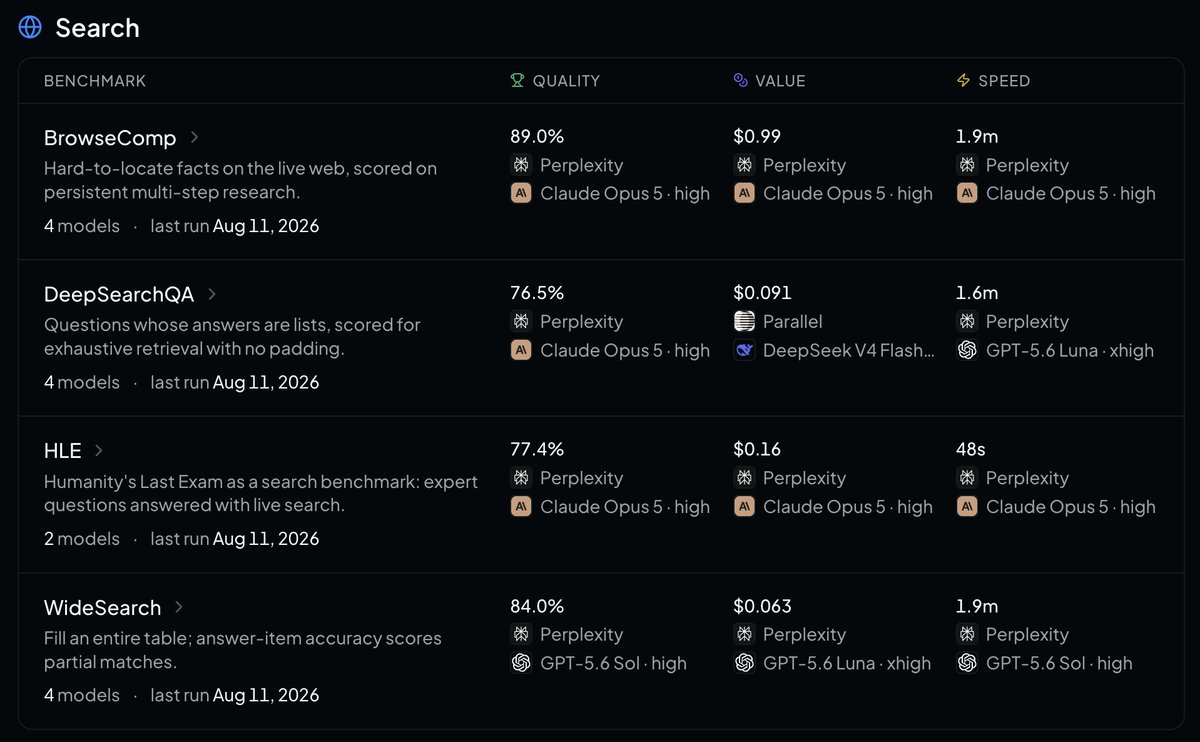
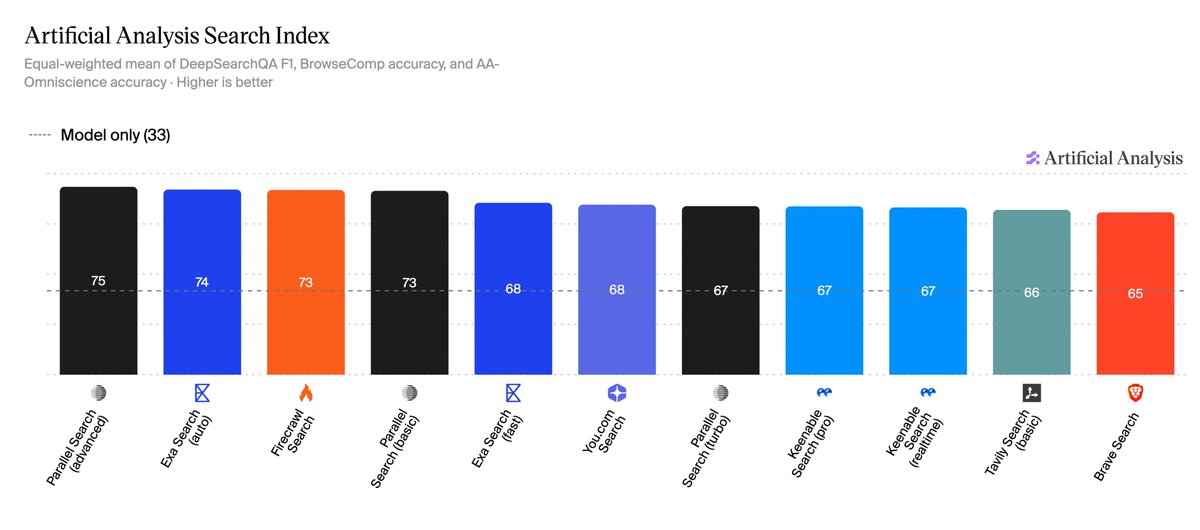
Giving a search assistant more attempts can improve difficult answers while making unsuccessful searches expensive. In OpenRouter's BrowseComp runs with a 25-round allowance, incorrect answers used an average of 19.7 searches, compared with 10.3 for correct answers. The assistant could keep spending its allowance without finding enough evidence to succeed. These tests used search-result excerpts, with full-page fetching and code execution disabled. The benchmark methodology helps compare configurations within that setup, including how much search budget failed questions consume.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.