voyage-large-2-instruct takes the MTEB top spot at 1024 dimensions
- Source
- x.com
- Date

🆕 📢 voyage-large-2-instruct embedding model tops the MTEB leaderboard 🥇! https://t.co/KNtaeylq2o — embedding dimension = 1024 (4x smaller than any other non-Voyage model in top-5) — 16K context length (2x of OpenAI v3 large) blog: https://t.co/AzddxYl8Sb #RAG #LLM
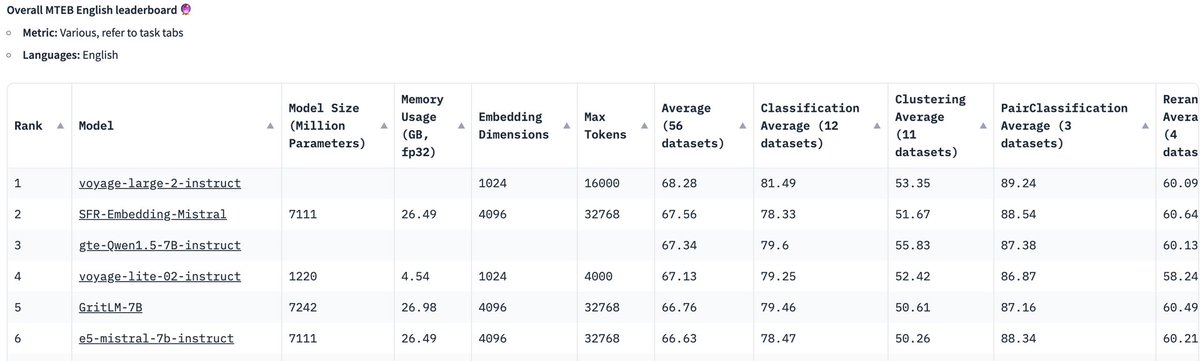
Please also checkout other recent products: rerank-lite-1: https://t.co/FBmEvLDlAg voyage-large-2-instruct: https://t.co/pBfeQfPpVL all offerings: https://t.co/LbYgmWh9w7
Context
Voyage AI's May 2024 release of voyage-large-2-instruct combined a reported first-place overall MTEB score with 1,024-number . Those numbers represent a text input for tasks such as search and grouping related documents; they are separate from the model's 16,000- input limit. The release report presents the result as a strong showing from a relatively compact output representation.
The model also responds to instructions prepended to its input. For retrieval, the API distinguishes a search query from a document being indexed. The leaderboard result is a historical snapshot across several text tasks, rather than a current ranking or a prediction for every search collection.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…