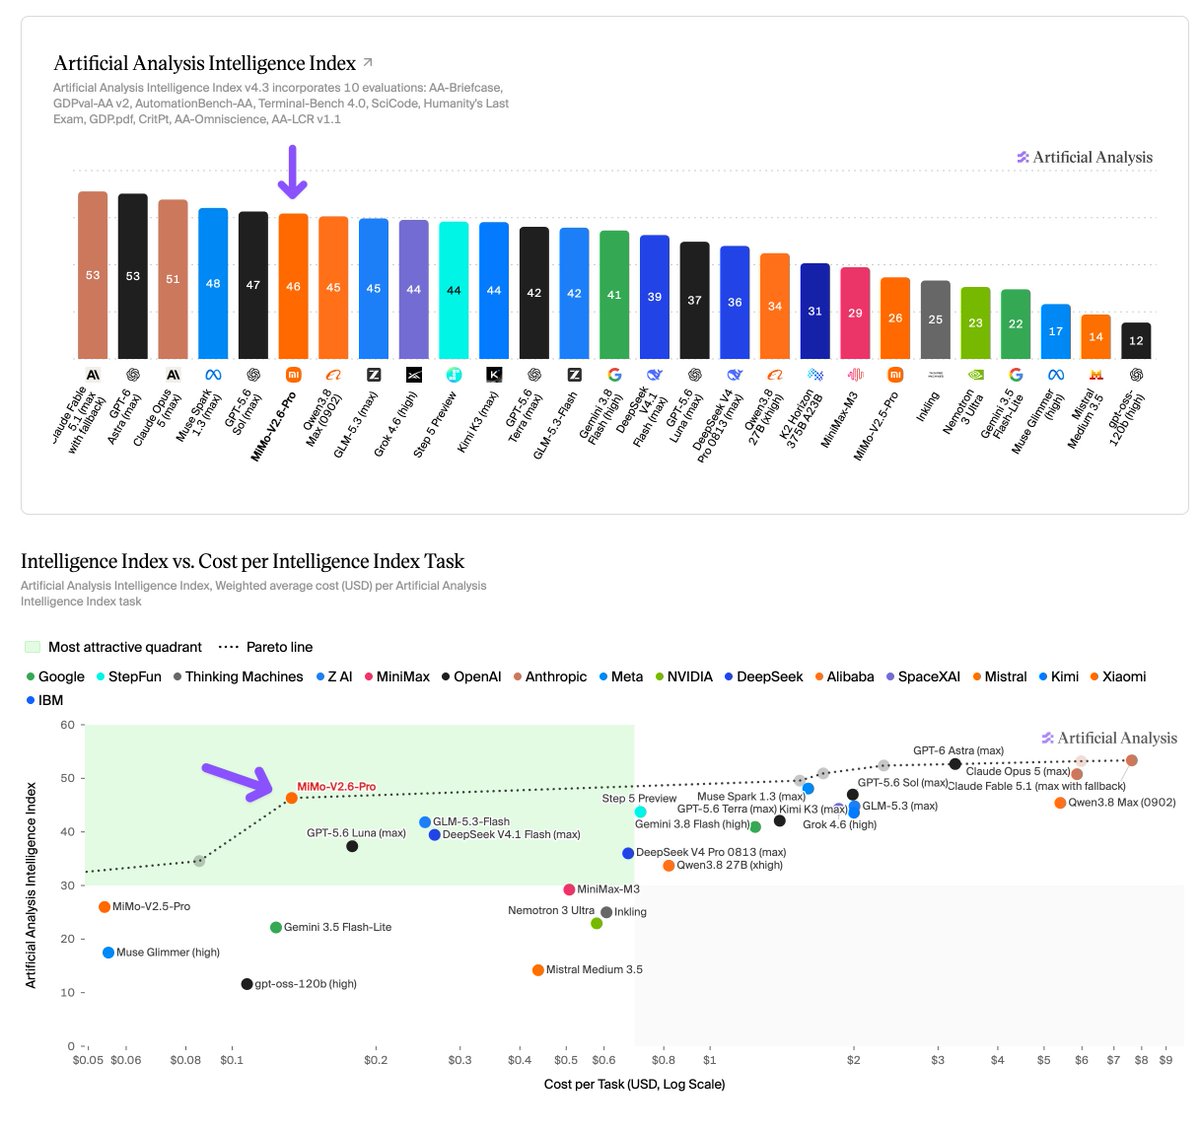
MiMo-V2-Pro offers a 1M context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → at $1/$3 per million tokens and scores 49, near GLM-5, but is only available via Xiaomi's API for now.
Key takeaways · AI-distilled
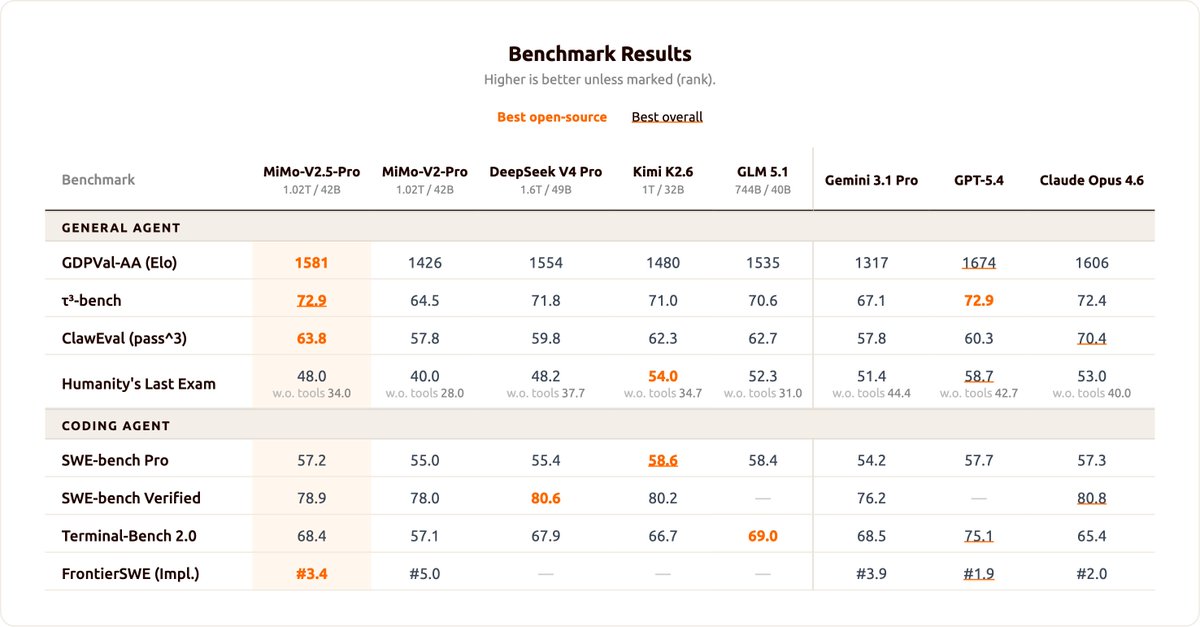
MiMo-V2-Pro's GDPval-AA Elo of 1426 leads GLM-5 (1406), Kimi K2.5 (1283) and Qwen3.5 397B (1209), but trails GPT-5.4 (xhigh) at 1667 and Claude Sonnet 4.6 at 1633.
Its AA-Omniscience Index of +5 comes mainly from a 30% hallucinationWhen a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.Full definition → rate, down from 48% for Xiaomi's earlier open-weights MiMo-V2-Flash; Claude Opus 4.6 (+14) and Gemini 3.1 Pro Preview (+33) remain ahead.
MiMo-V2-Pro used 77M output tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → to run the Intelligence Index, against 109M for GLM-5 and 89M for Kimi K2.5, and cost $348 to run, compared with $2,304 for GPT-5.2 (xhigh).
Pricing doubles to $2/$6 per million tokens for inputs beyond 256K, up to the 1M window, and the model is text-only with no image input.
Terms in this piece · Glossary
hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.