MiniMax M3.1 Flash goes live on Fireworks at half M3's price
Source
fireworks.ai
Author
Fireworks
Date
Why it matters
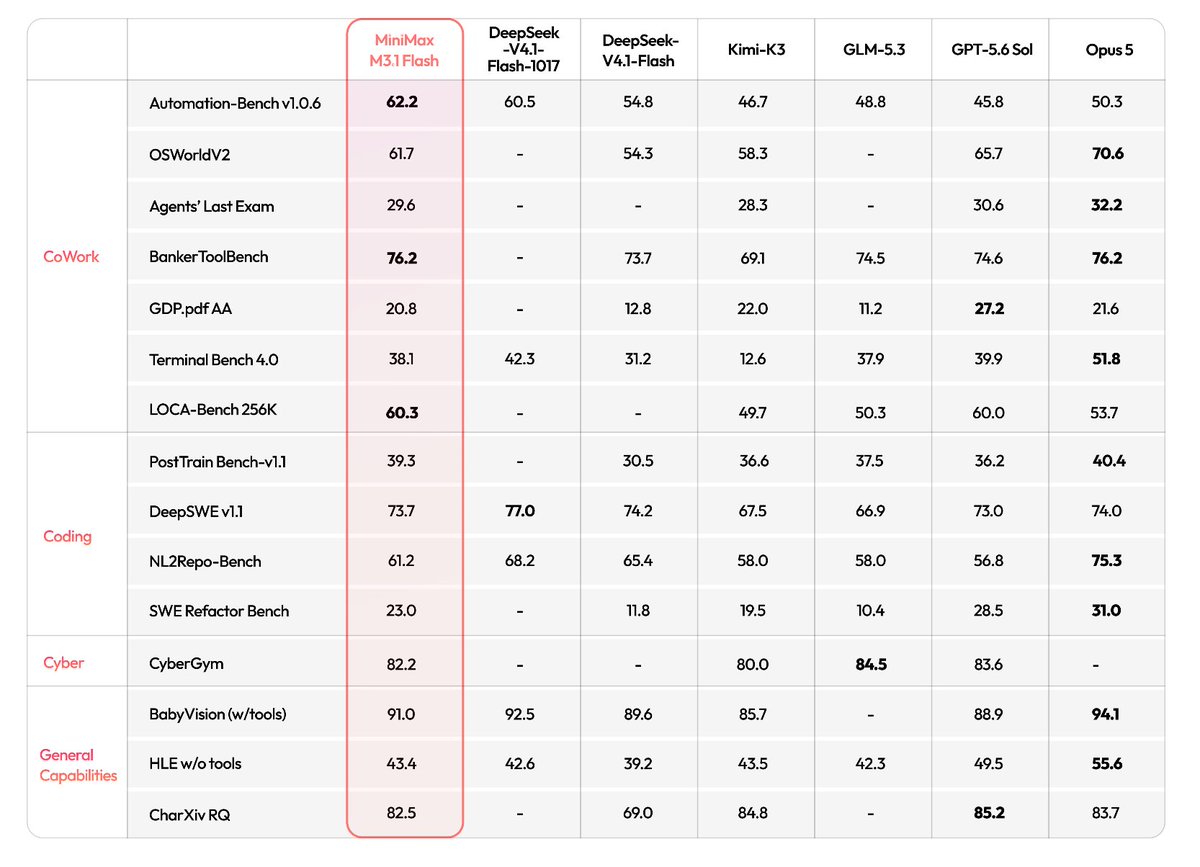
A 1M-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → multimodal mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → with tool useA model's ability to call external functions — run code, search the web, edit files — instead of only generating text.Full definition → is available serverless at $0.15 input and $0.60 output per million tokens, half the price of M3. The preview runs only two weeks, so AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → builders should test it now.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.