← All IntelIntel / article
MiniMax M3.1 Flash lands on Together AI with 1M context and low pricing
- Source
- together.ai
- Author
- Together AI
- Date
Why it matters
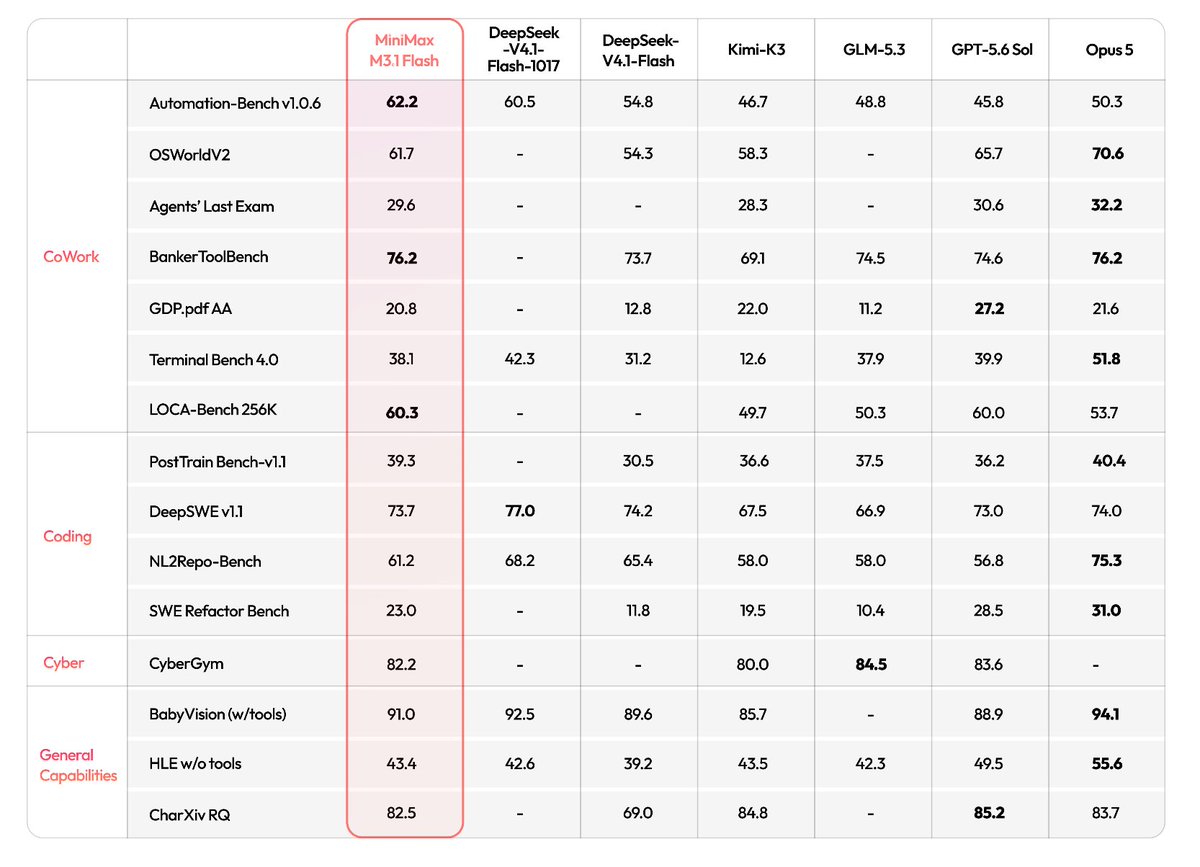
MiniMax M3.1 Flash is available through the Together AI API at $0.15 input and $0.60 output per million tokens, with 1M and adjustable reasoning effort. Engineers can test a low-cost agentic coding and computer-use model today.
Terms in this piece · Glossary
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
Read the source together.ai
More from Together AI

Recommended reads
Comments
Checking sign-in…
Loading comments…