ZGCM-1 explores how a model in the seven-billion-parameter class can solve research tasks by combining reasoning with external tools. Its training report describes teaching sequences of actions and observations, including searches and page reading. Training examples preserve the tool formats and interaction structure the model will encounter when deployed.
The authors report that mismatches between training and deployment formats substantially hurt agent performance. They also provide training workflows and links to model weights and data. That gives researchers material for studying how a compact model learns to gather evidence, rather than evaluating only a finished model's answers.
Key takeaways · AI-distilled
ZGCM-1 is a fully open 7B dense model built on the premise that small models can't passively memorize the open web, so it pairs internal step-by-step 'thinking' with active external tool useA model's ability to call external functions — run code, search the web, edit files — instead of only generating text.Full definition → to make up for limited parametric capacity.
Its training recipe interleaves gated sliding-window and full attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → with a stable FP8 Muon optimizer, and turns agent interaction traces into Markov Decision Processes during a mid-training phase that scales context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → from 16K up through 256K tokens.
Despite its size, ZGCM-1-7B stays competitive on math reasoning and agentic search benchmarks against frontier models 'orders of magnitude larger,' including Qwen3-235B-A22B and GLM-5.1.
The team reports the pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → design gives roughly a 4.2x efficiency improvement in time-to-loss at 16K context, and open-sourced weights, intermediate checkpoints, training code, and per-stage data recipes from every training stage.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
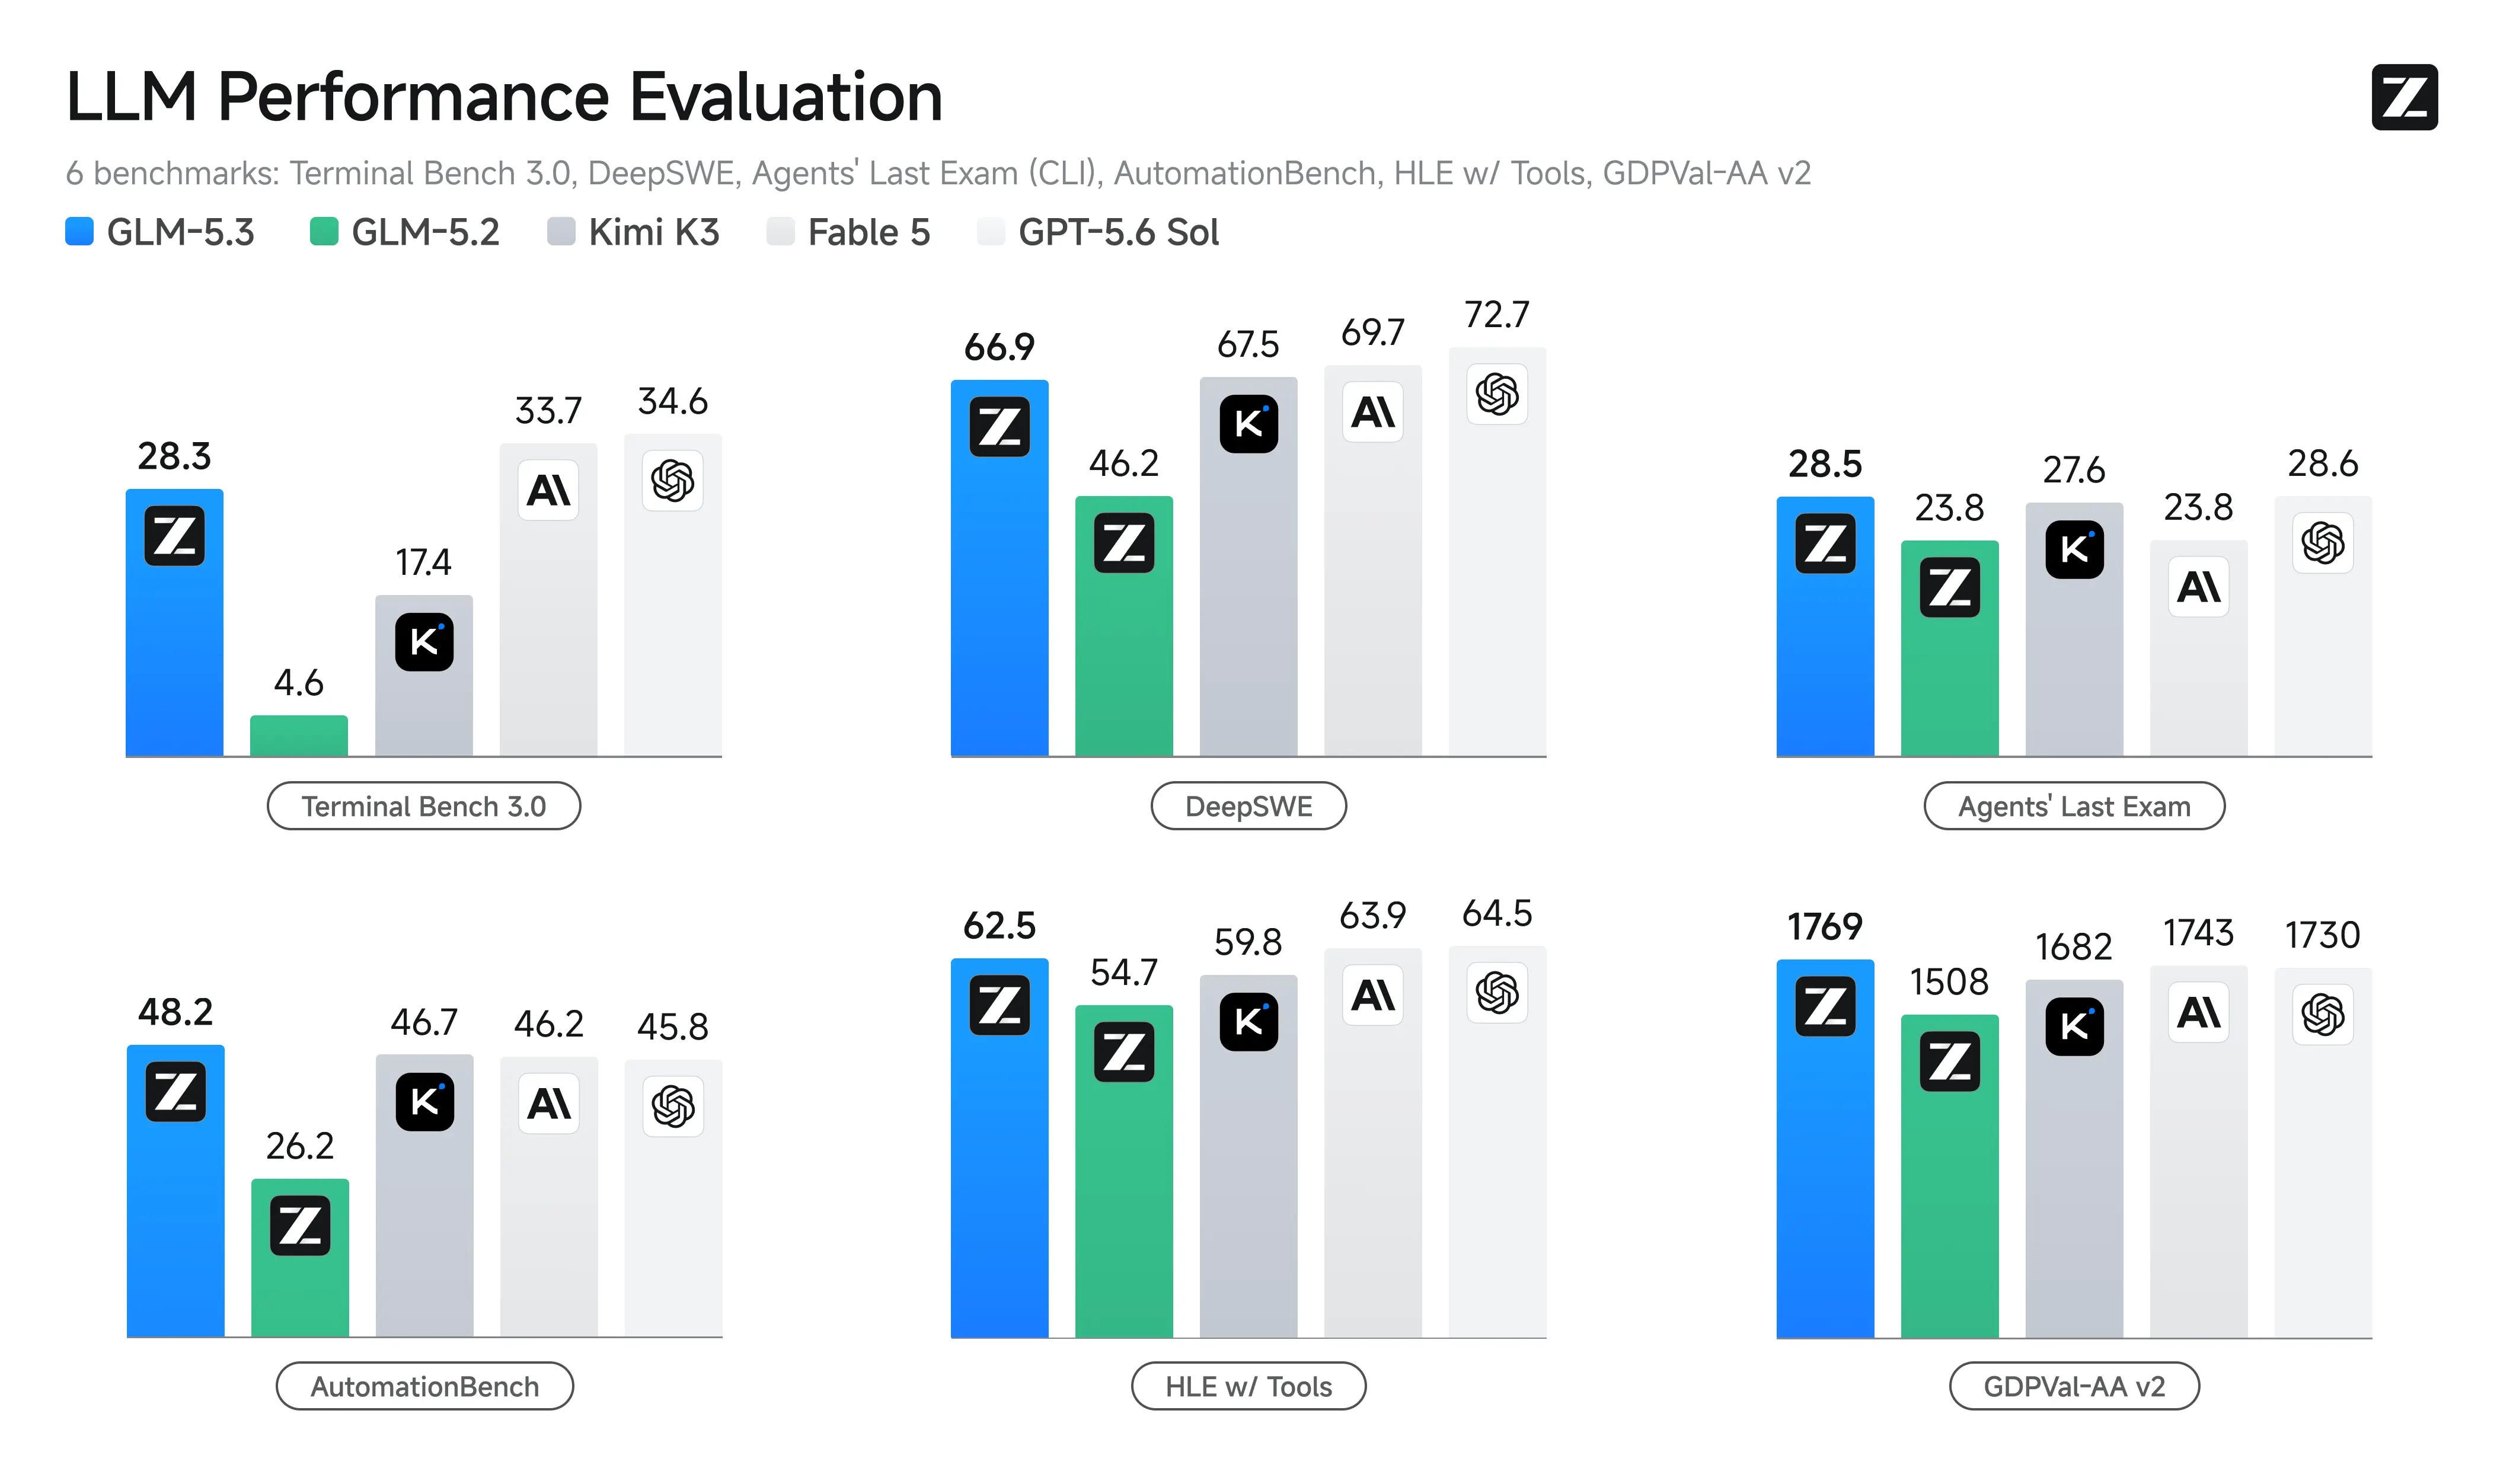 articleGLM-5.3: How Chinese labs keep stride with the frontierNathan Lambert
 articleOccamy-1.0: Open Pareto-frontier 35B Intelligence for Co-workWenhui Chen, Shiwen Cheng, Hao Dong, Chenda Duan, Ruixiang Feng, Zhong Guan, Boqiang Guo, Xueyuan Han, Haojie Hao, Liangmeng Huang, Zhelong Huang, Xinke Kong, Hongyu Li, Jiazheng Li, Junbo Li, Qingchuan Li, Yukun Lian, Chang Liu, Tianyu Liu, Zicheng Liu, Shuyi Ouyang, Yijun Pan, Kunyu Shi, Xiaojun Tang, Bingquan Wang, Kesu Wang, Yuchen Wang, Sibo Wei, Sicong Xie, Xiaoying Xing, Yi Xu, Zhijun Xu, Hongwei Xue, Qingcheng Zeng, Di Zhang, Guannan Zhang, Haochen Zhang, Tianlong Zhang, Tianyu Zhao, Tianyu Zhao, Yanjun Zheng, Jialong Zhu, Zijian Zou