GLM-5.3: How Chinese labs keep stride with the frontier
- Source
- Nathan Lambert
- Author
- Nathan Lambert
- Date
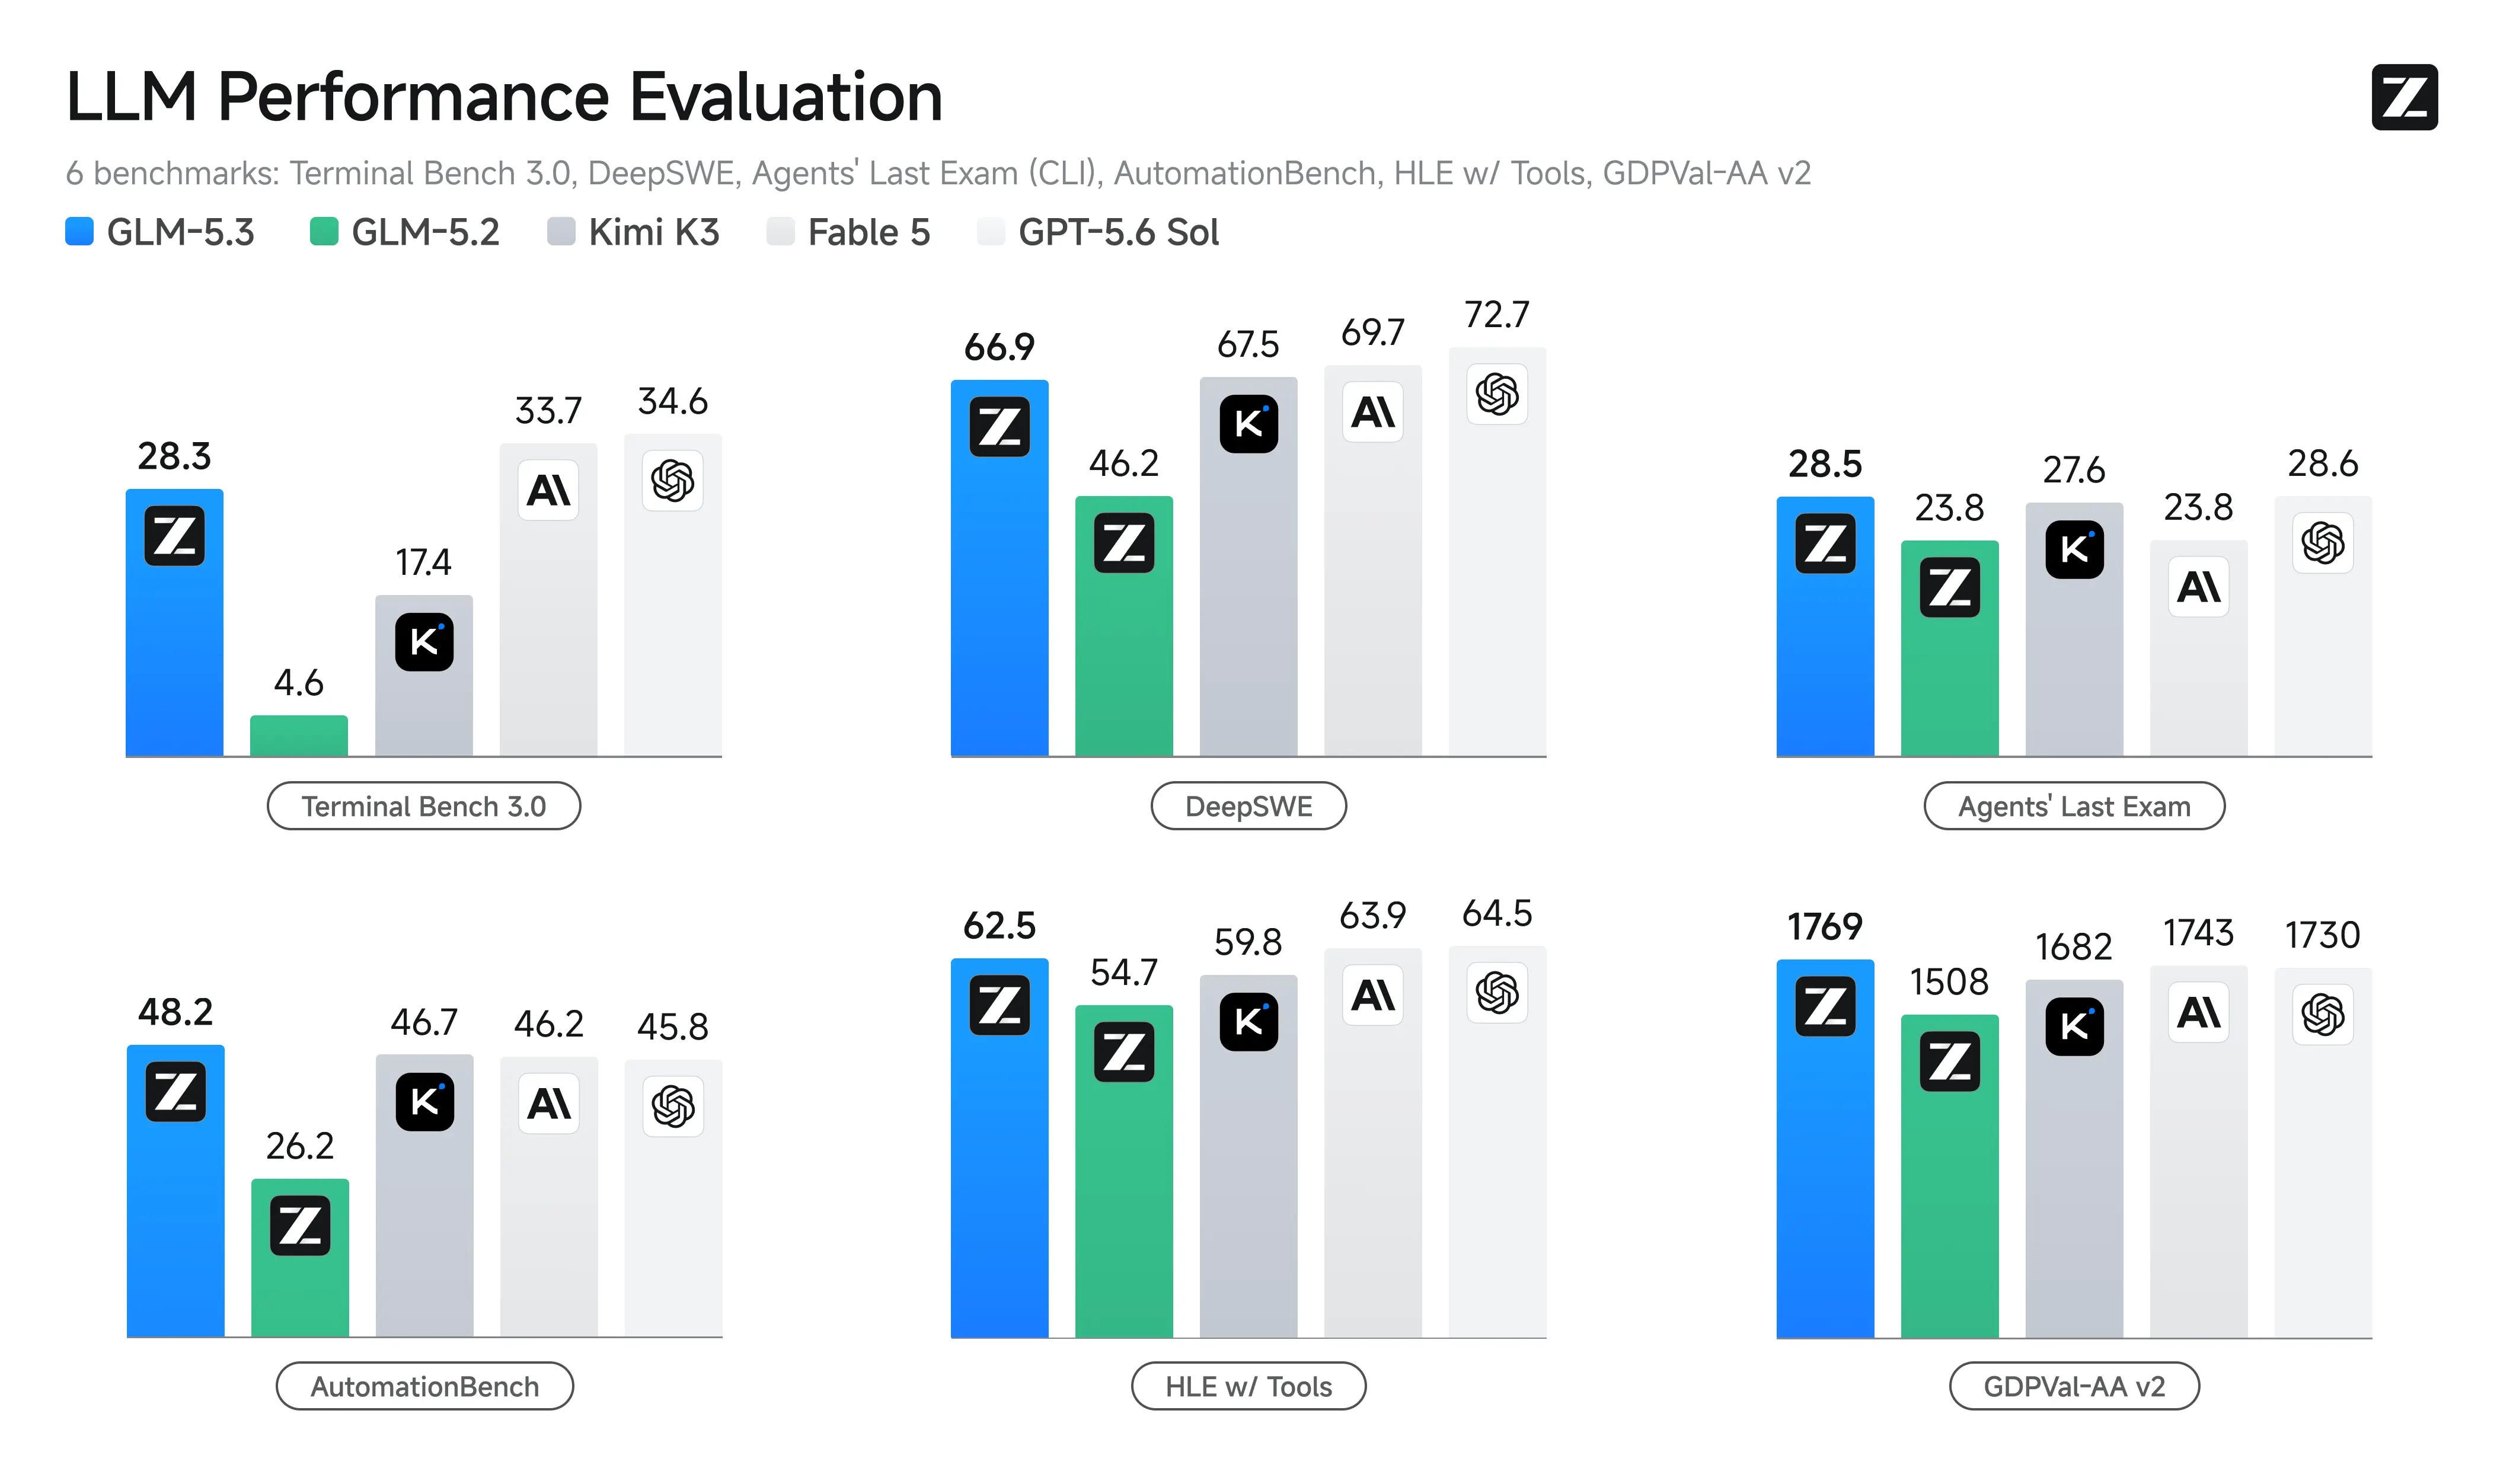
A frontier-level agentic coding score reached purely through post-training on an existing base, at a third of a competitor's parameter count, resets what teams should assume about the cost of catching up.
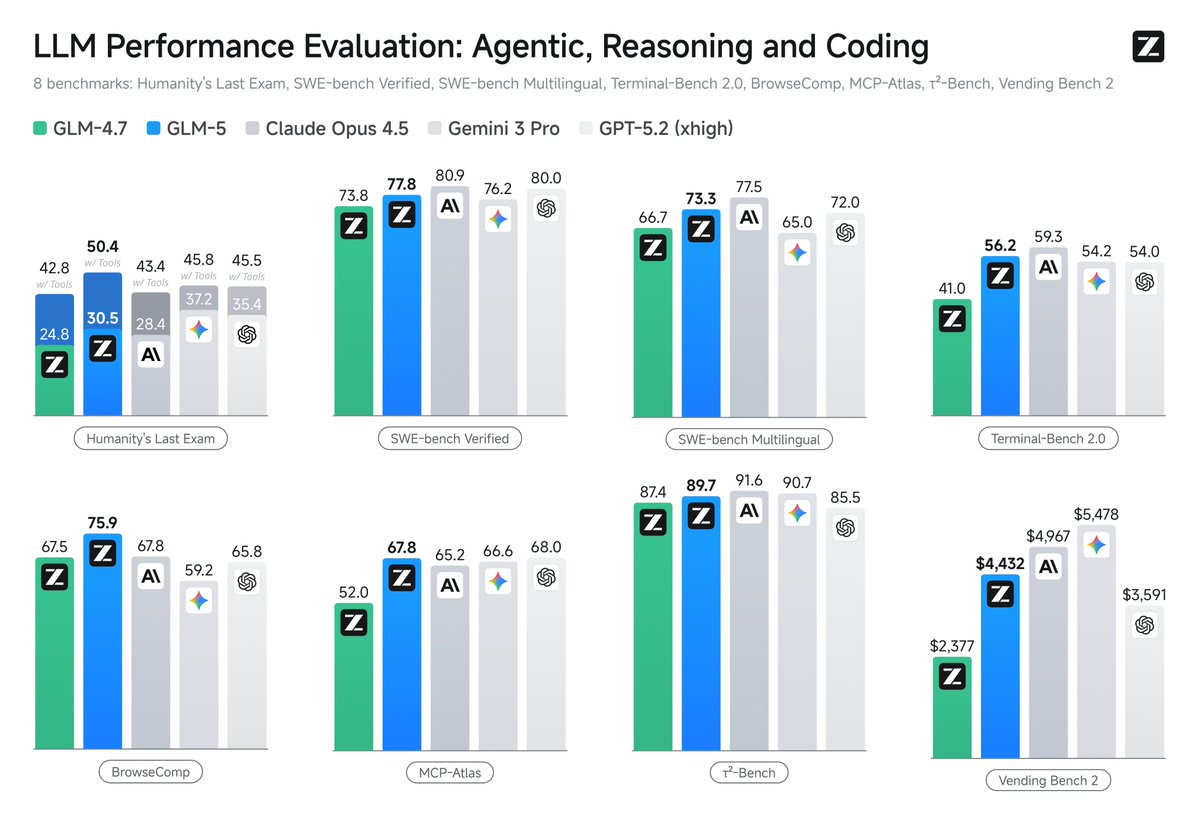
“This puts the model more or less at the frontier of agentic coding benchmarks, with only ~750B parameters – a third of Kimi K3!”
Nathan Lambert
“The time to release for Z.ai is likely days, not months as with OpenAI or Anthropic.”
Nathan Lambert
“It is very, very likely that OpenAI and Anthropic have far better internal models than Z.ai and Moonshot AI.”
Nathan Lambert
“One does not simply “distill” RL environments, infrastructure to run them at scale, or algorithms to mix them together effectively.”
Nathan Lambert
“Many companies’ data acquisition strategy is to buy data on the benchmarks they’re behind on.”
Nathan Lambert

Checking sign-in…
Loading comments…