ALERT🚨 TILERT from @TileRT_AI TO BOOST DECODE INTERACTIVITY BY 1.9X AT THE…
- Source
- x.com
- Date

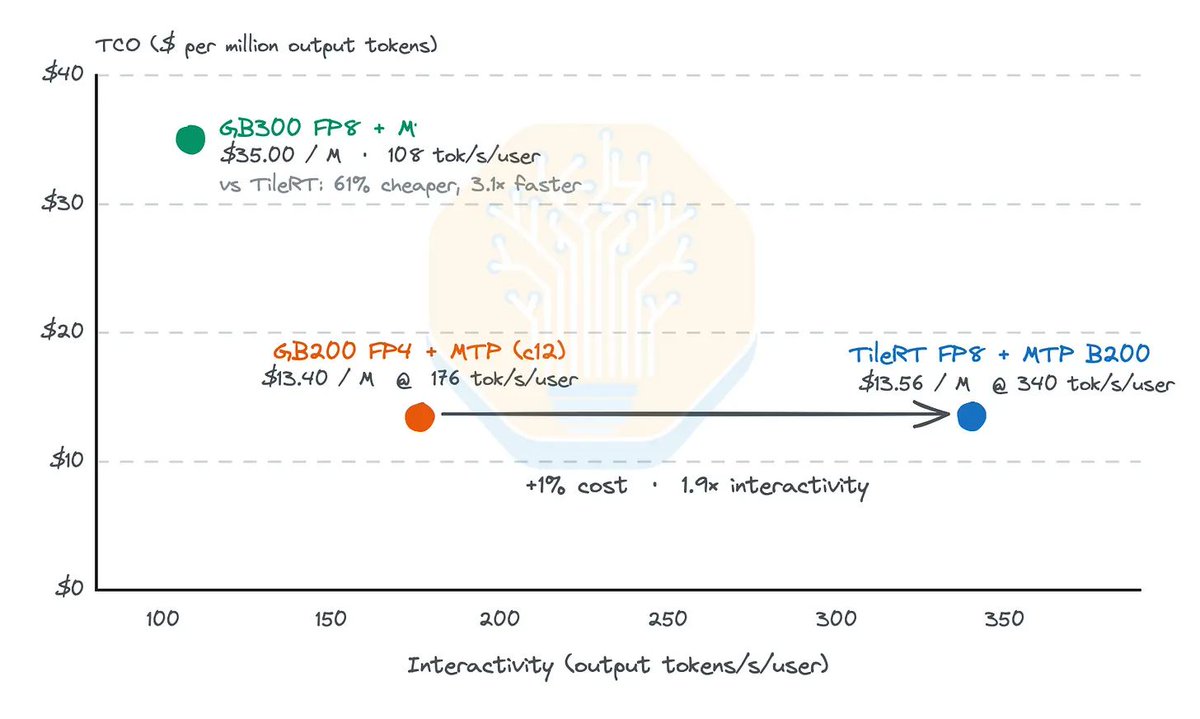
ALERT🚨 TILERT from @TileRT_AI TO BOOST DECODE INTERACTIVITY BY 1.9X AT THE SAME PER-TOKEN COST ON THE SAME NVIDIA BLACKWELL GPUs. What does this mean for Groq/Cerebras/SambaNova? 👇️ 1/5🧵
Context
TileRT is an engine for running language models on NVIDIA GPUs, aimed at faster text delivery to an individual user. It keeps generation running in one persistent GPU program instead of repeatedly launching separate operations. SemiAnalysis explains this mechanism in its benchmark article.
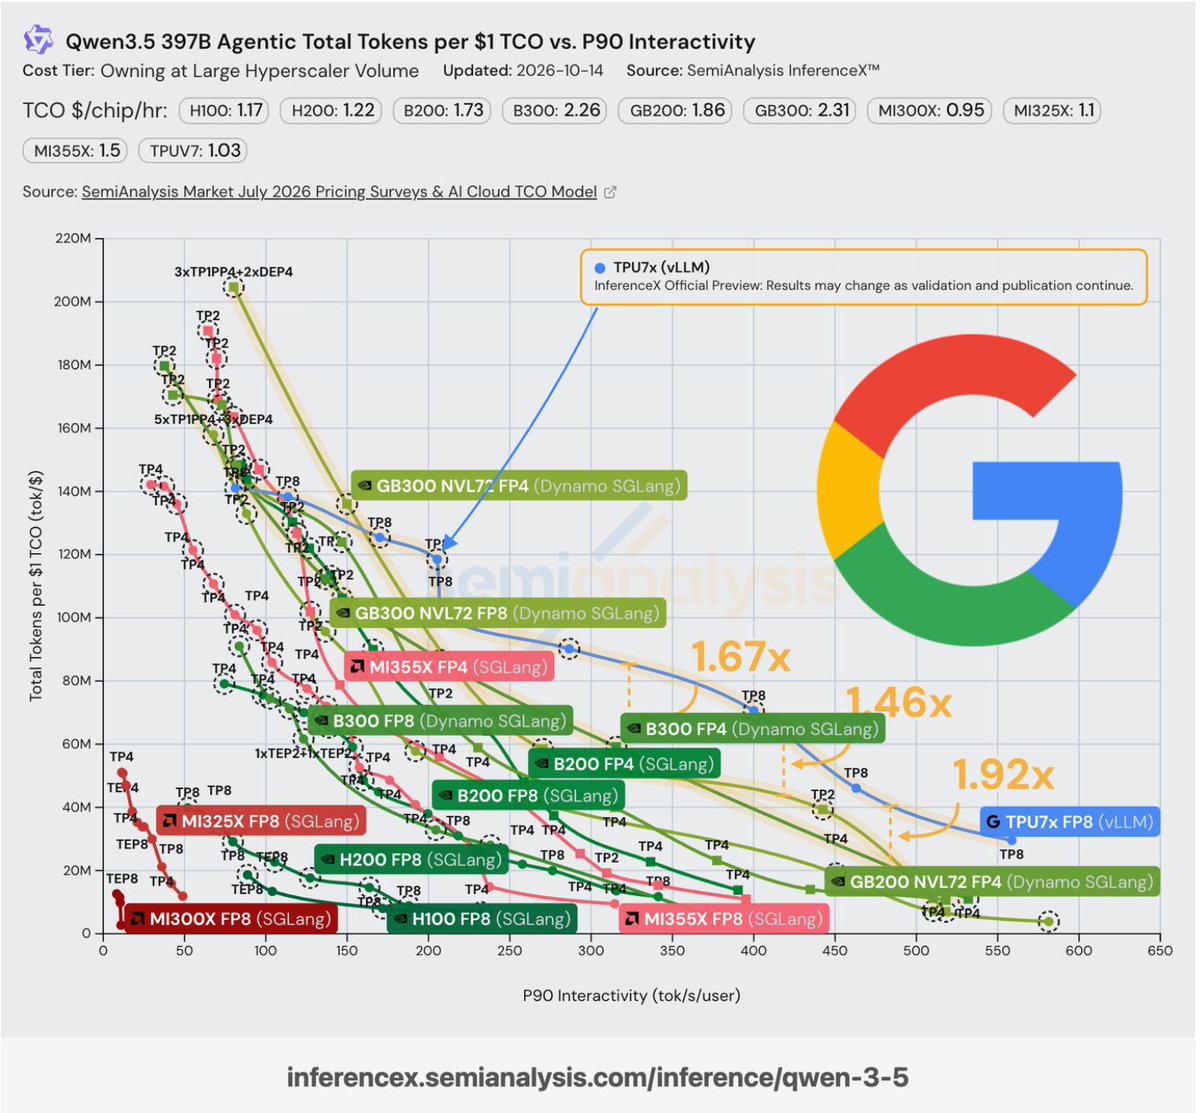
The announcement's chart compares 340 output per second per user for TileRT on NVIDIA B200 with 176 on a GB200 configuration, at estimated costs of $13.56 and $13.40 per million output tokens. That supports roughly 1.9 times the per-user speed at nearly equal estimated cost, across those two configurations rather than identical hardware. Related Intel coverage of the article notes the gain is per-user speed: a conventional GB300 setup completes more total work per GPU.
Checking sign-in…
Loading comments…