Deepseek V3 2 And V3 2 Speciale Are Now Available In Cline
Source
cline.bot
Author
Cline evaluation and engineering blog
Date
Why it matters
A model that retains reasoning across read, edit, run and check cycles avoids re-deriving context each step. This helps you choose between V3.2 and Speciale and their token costs for agent work.
Key takeaways · AI-distilled
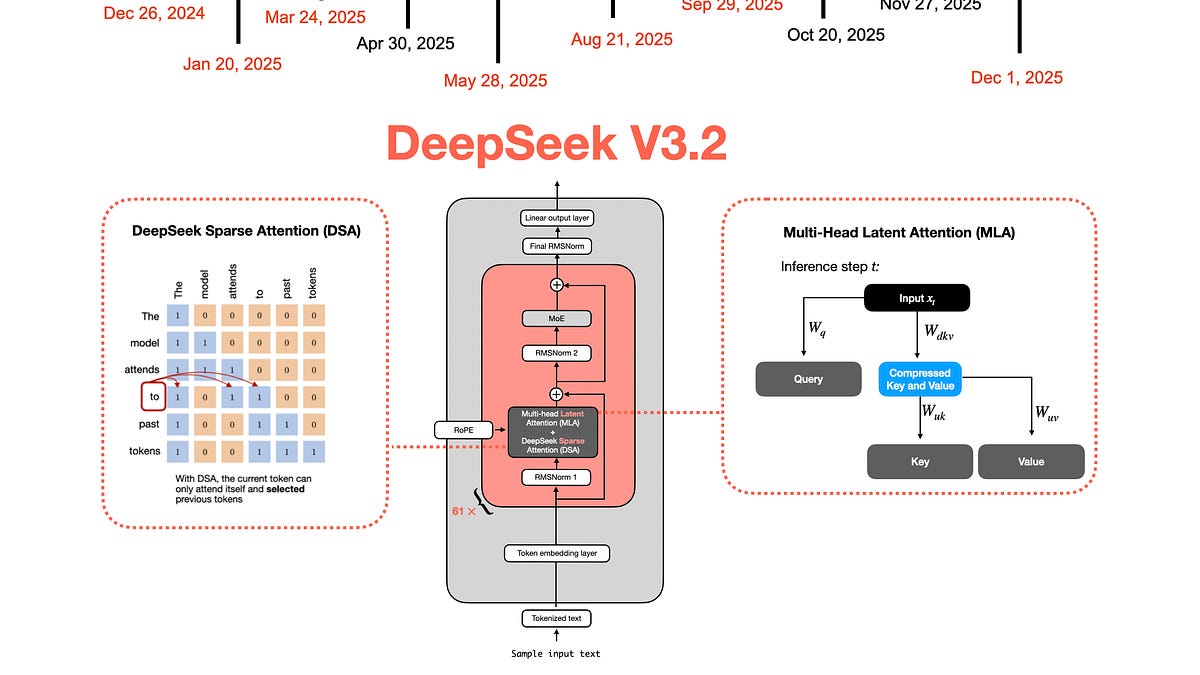
DeepSeek V3.2 keeps its reasoning trace across tool calls until a new user message arrives, so tool outputs alone do not reset it. Cline says this keeps the reasoning thread intact through read, edit, run and check cycles.
DeepSeek trained V3.2 on 1,800+ synthesized environments and 85,000+ agent instructions, including 24,667 code agent and 50,275 search agent tasks, and spent over 10% of pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → compute on reinforcement learning, which Cline calls unusually high.
Per Cline, both V3.2 and V3.2-Speciale cost $0.28 per million input and $0.42 per million output tokens with a 131K context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, and neither supports images, browser use or prompt cachingReusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.Full definition →.
Speciale relaxes length constraints and uses significantly more output tokens. DeepSeek reports gold-medal performance on the 2025 IMO, IOI, ICPC World Finals and CMO with it, while Cline positions V3.2 as the everyday option.
Terms in this piece · Glossary
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.