Compact
- Source
- relace.ai
- Author
- Relace
- Date
Context
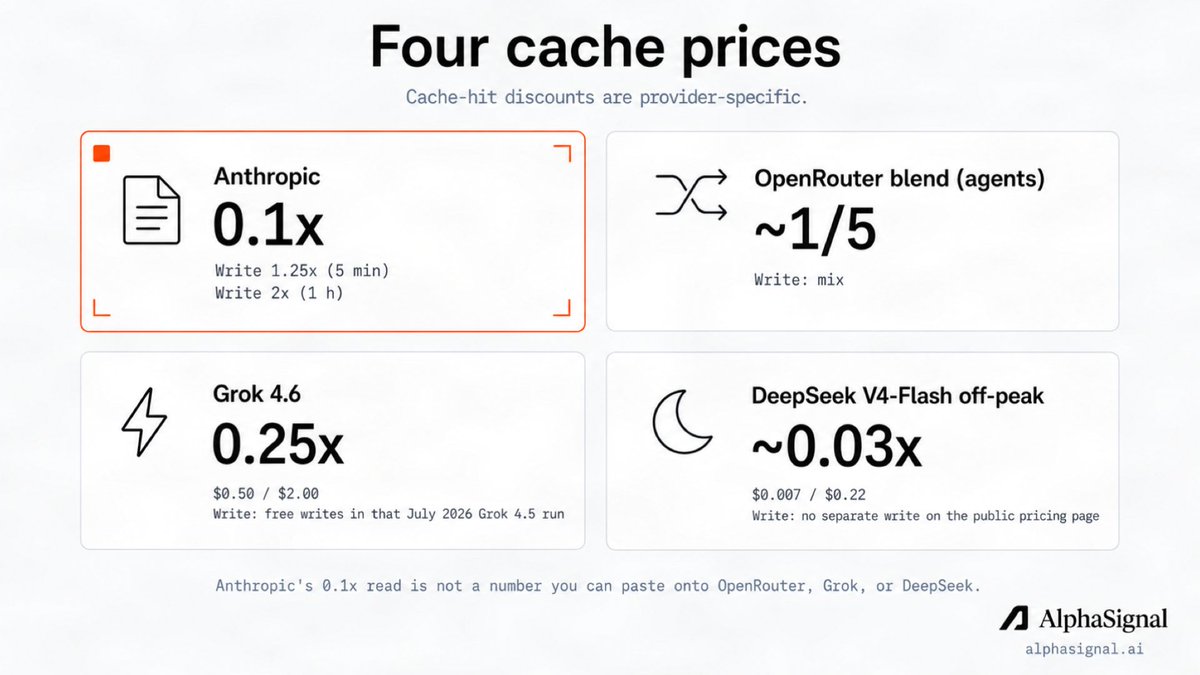
Relace's Compact targets a costly moment in a long coding conversation: returning after the provider's short-lived cache of the conversation has expired. The next request must process the entire history again. In its July 2026 engineering post, Relace proposes removing stale material at that point, since the history has to be rewritten anyway. A shorter history reduces both the rewrite and the amount reread on later turns.
Relace replayed 15 days of real traces from Jacq, its own coding product, and estimated aggregate savings of 56% when compacting expired-cache conversations to 128K . That is a simulated saving on those traces, using the provider prices Relace cites, not a measured bill. The company also says the approach is imperceptible in latency and quality in its own testing, which this explanation does not independently assess.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context compaction — Summarizing an agent's earlier conversation to free room in the context window so a long session can keep going.
Checking sign-in…
Loading comments…