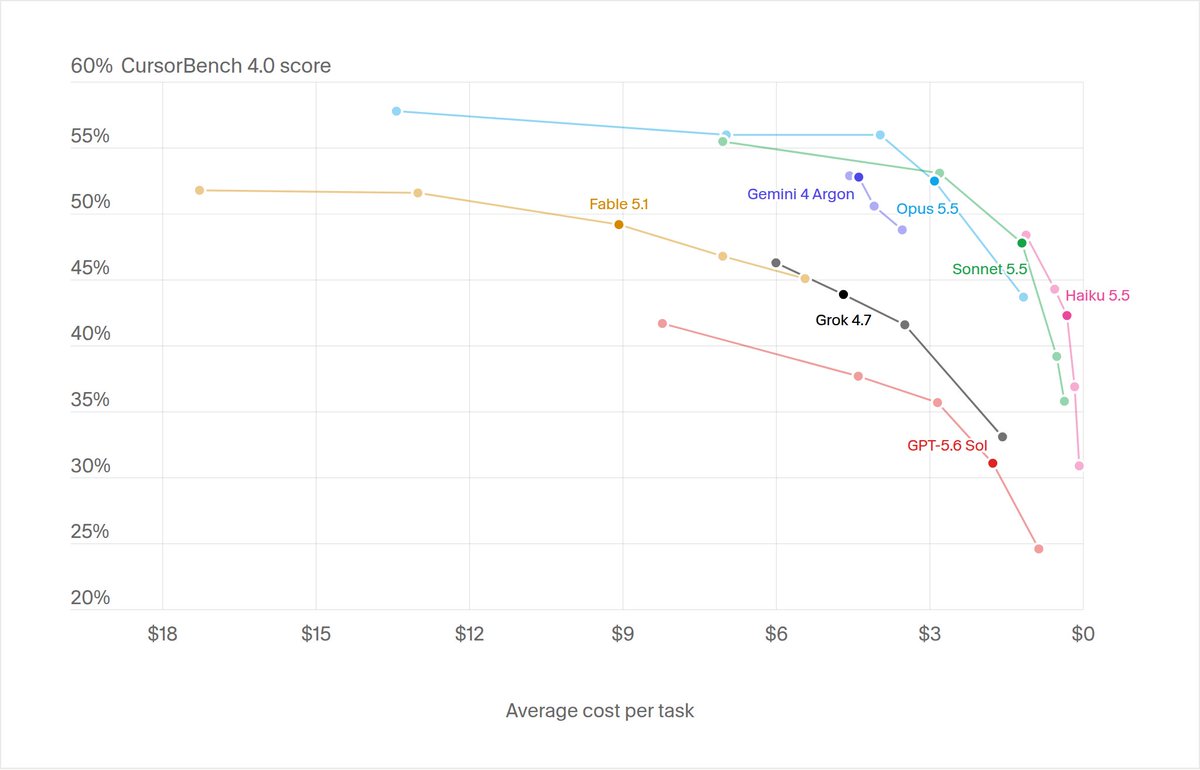
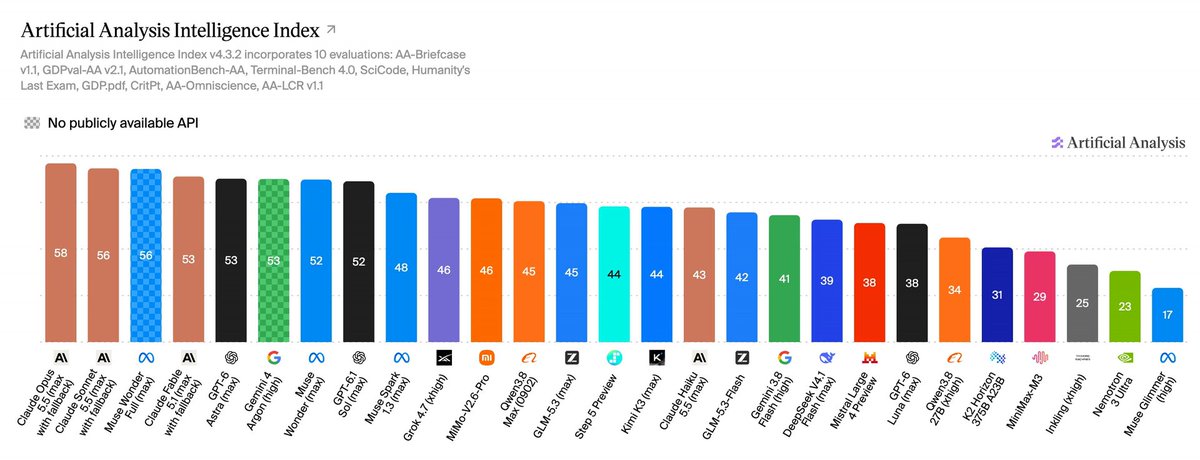
ran gemini 4 argon on the same internal https://t.co/QhA9tU0Lhp evals - comparable to opus 5.5 in terms of cost efficiency (assuming introductory pricing), but 2X slower
gpt-6.1-sol still 3x more cost efficient than either (though slower than opus 5.5 in this run) https://t.co/L7Nujsclt5
An outside evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → suggests Gemini 4 Argon matches Opus 5.5 on cost efficiency at introductory pricing but runs about twice as slow, informing model choice beyond vendor benchmarks.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.