Gemini 4 models land on Cognition's FrontierCode 2.0
Source
cognition.com
Author
Cognition
Date
Why it matters
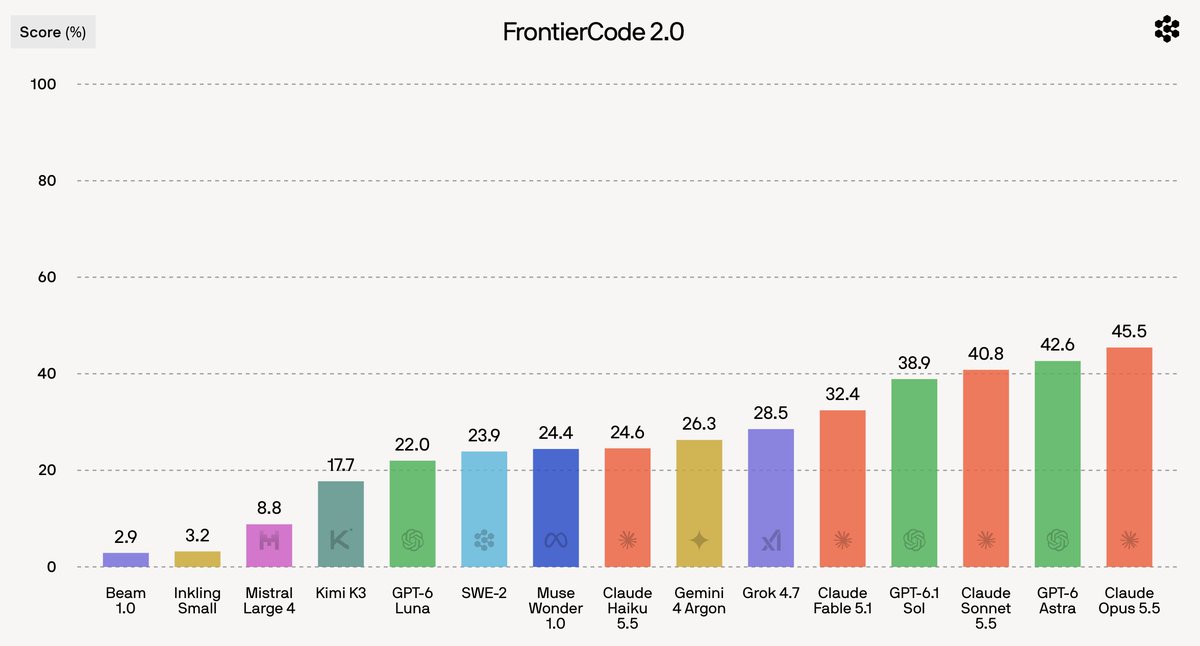
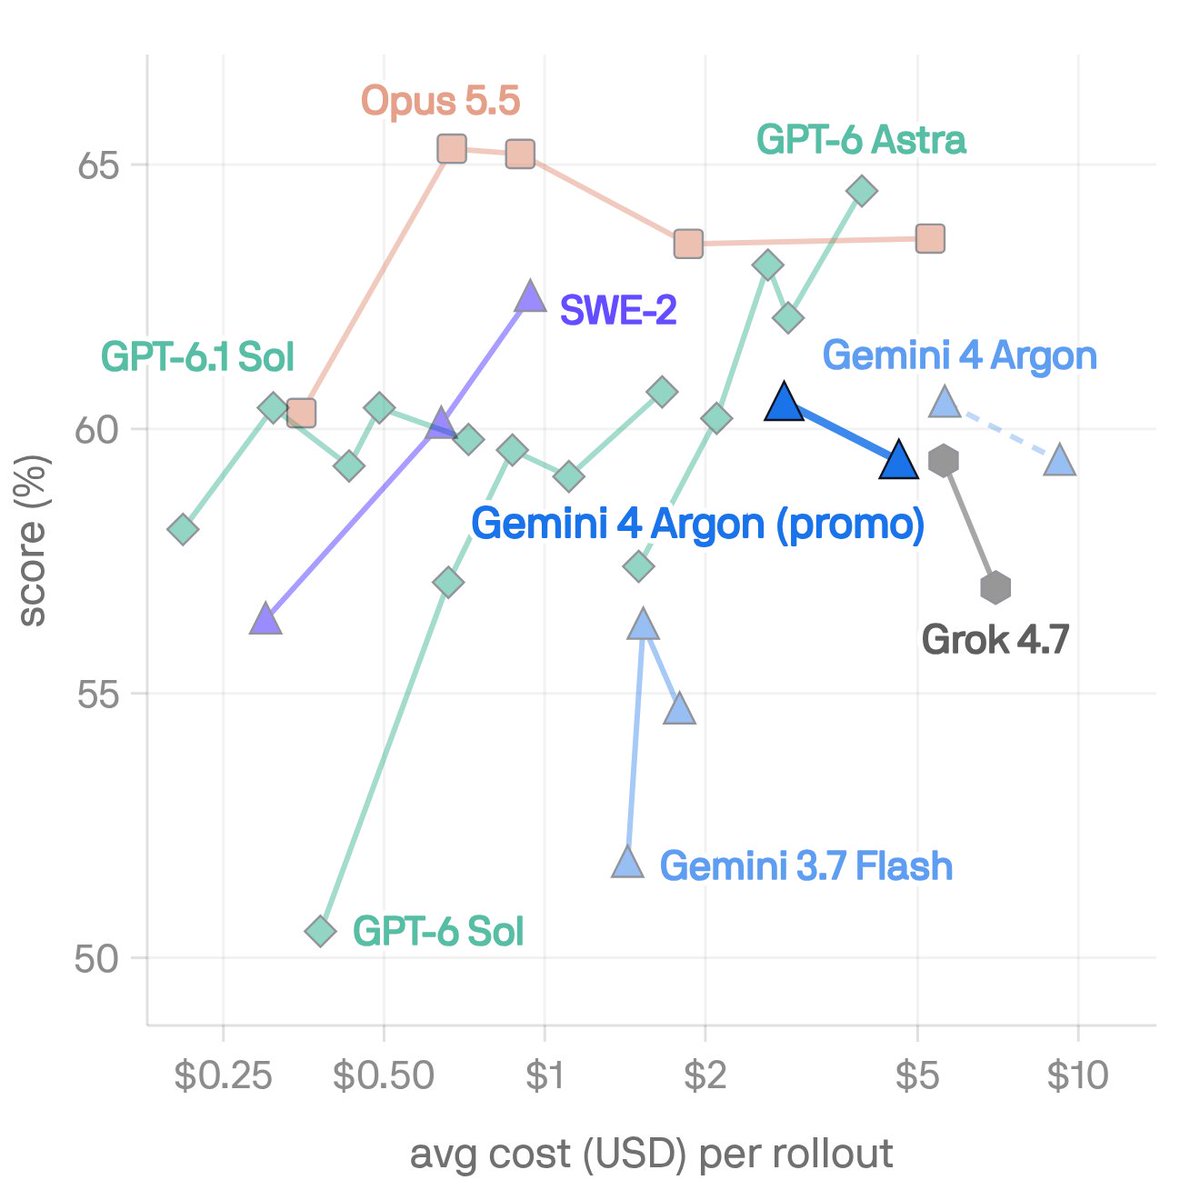
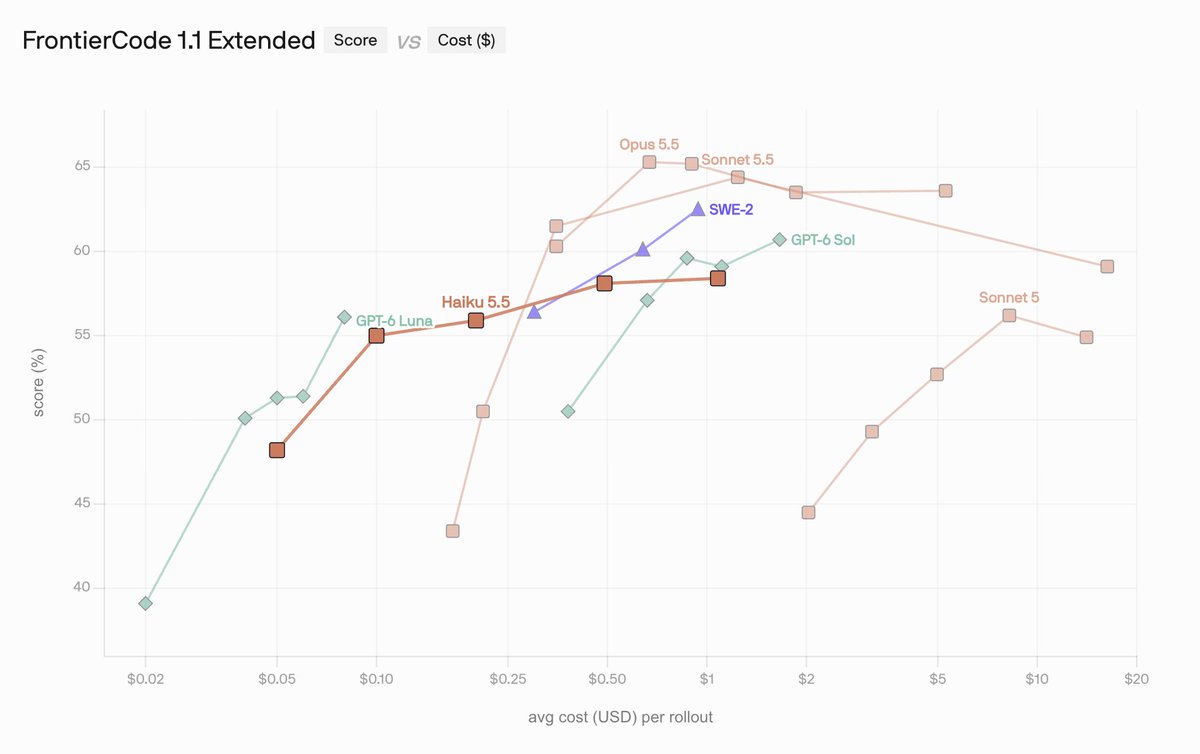
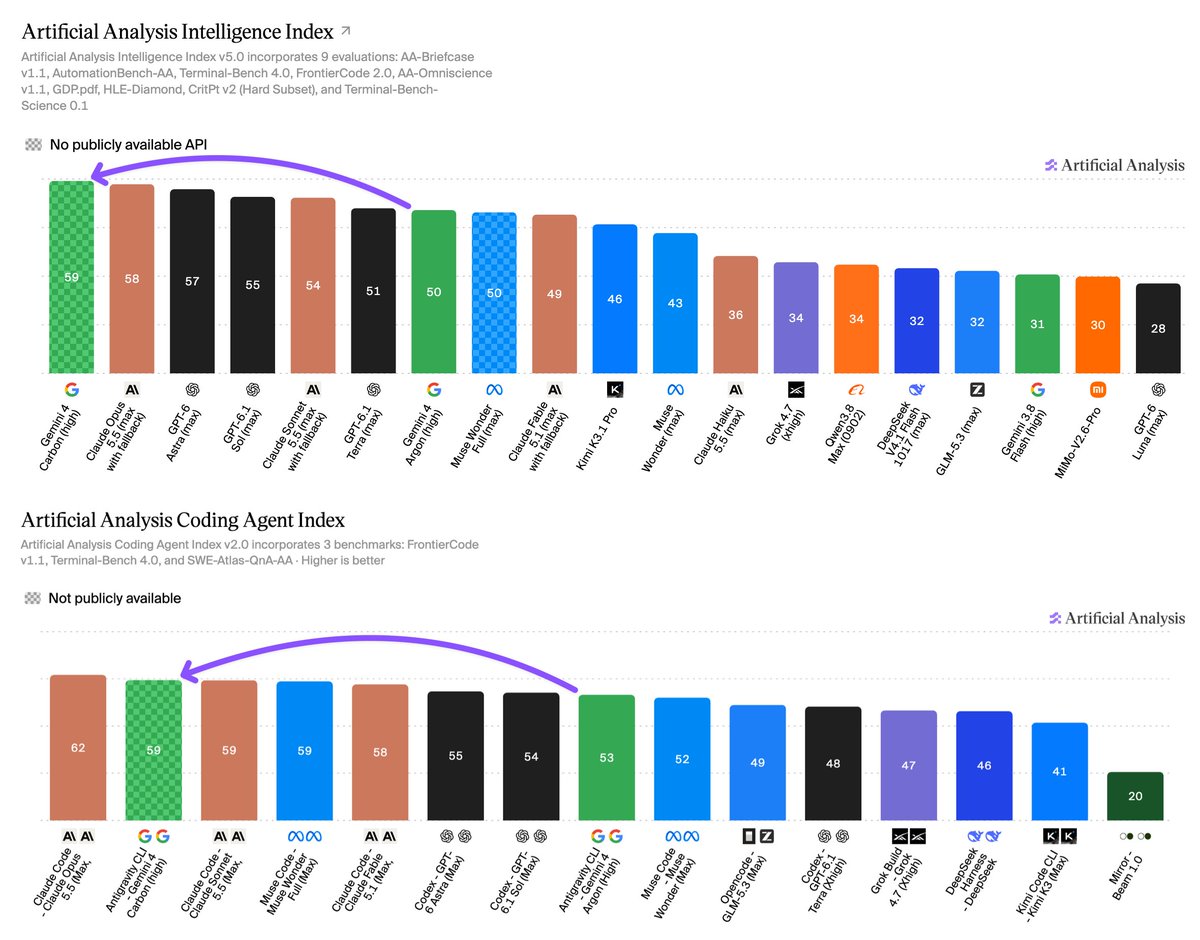
FrontierCode 2.0 grades whether a maintainer would merge the PR, not just whether tests pass. Gemini 4 Carbon scores 40% at $4.04 per task, trailing Claude Opus 5.5, GPT-6 Astra, and Claude Sonnet 5.5, which helps with coding-AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → model selection.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.