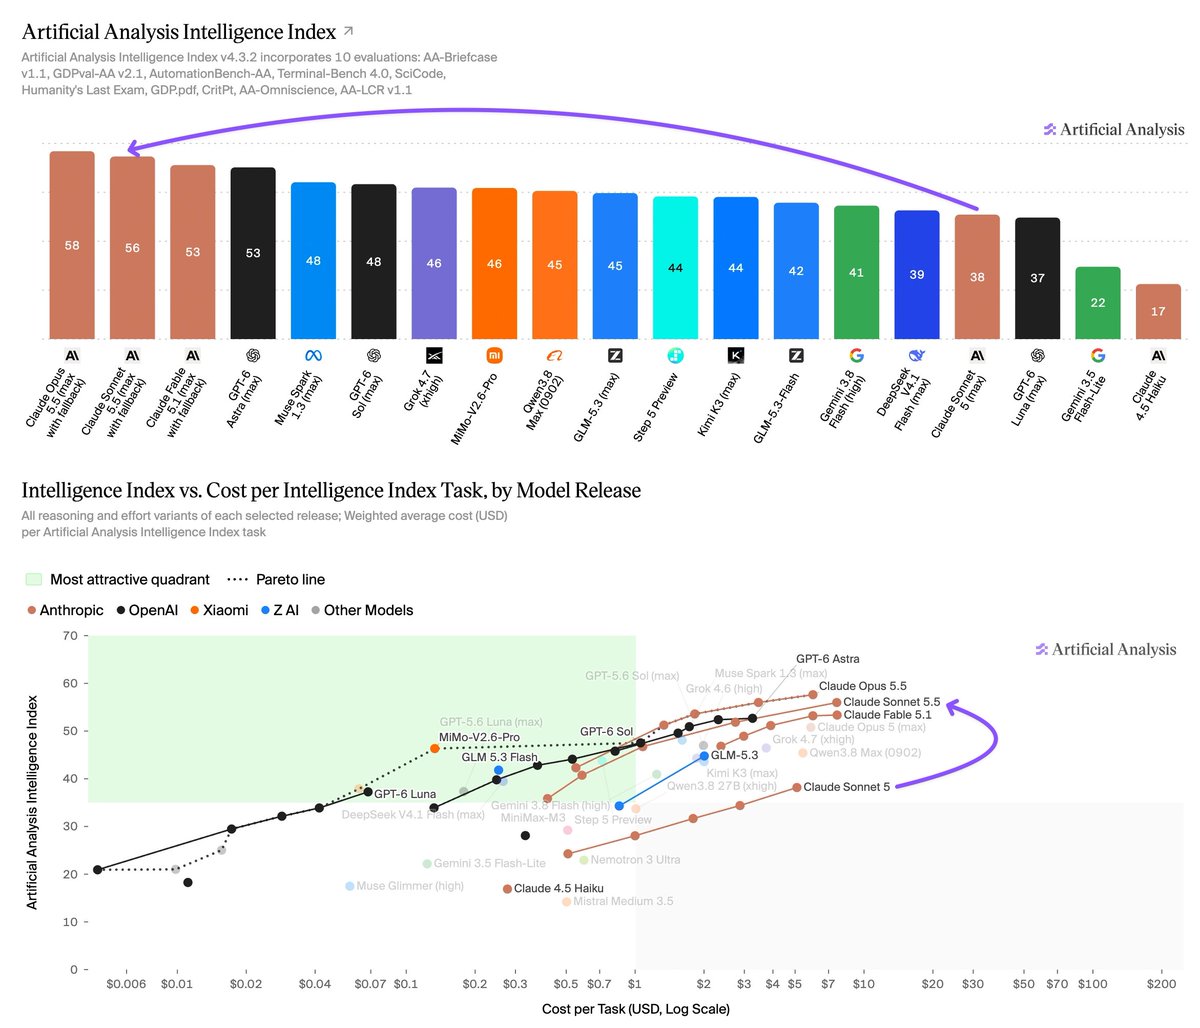
List price does not predict cost per task. Sonnet 5 at max effort costs about 15% more per task than Opus 4.8 once its extra turns and tokens are counted, so measure before switching.
Key takeaways · AI-distilled
Claude Sonnet 5 at max effort scores 53 on the Artificial Analysis Intelligence Index, 6 points above Sonnet 4.6 and level with GPT-5.5 (high), but still behind Opus 4.7 and 4.8.
At standard $3/$15 pricing it costs $2.29 per index task, about 2x Sonnet 4.6 and about 15% more than Opus 4.8, driven entirely by tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → use: about 40% more output tokens and about 3x the agentic turns on knowledge-work evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →.
On AA-Briefcase and GDPval-AA it sits just ahead of Opus 4.8, trailing only Fable 5, while Opus 4.8 stays ahead on heavy reasoning and knowledge benchmarks such as CritPt, where Sonnet 5 scores 17%.
Anthropic cut Sonnet 5 to $2/$10 until September 1, which AA's results do not use. The model adds an xhigh effort setting, matching Opus 4.8's five levels, and max effort uses about 6x the turns of low effort on GDPval-AA.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.