Planning benchmarks that use meaningful symbol names overstate LLM planning ability. AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → builders should test with renamed or opaque vocabularies before trusting planning results.
Key takeaways · AI-distilled
Renaming planning predicates while keeping states, transitions and optimal plans identical cut valid LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → planning success from 67.5% to 40.0%, with no refusals, so part of measured planning agent skillA reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.Full definition → comes from meaningful symbol names.
For predicting how structurally hard a STRIPS instance is without solving it, the zero-training h_add heuristic beat learned predictors on held-out domains (mean Spearman |rho| 0.931 vs 0.707 for ridge regression and 0.400 for ARC).
The authors find that routing between an LLM and a symbolic planner depends more on calibrationHow well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.Full definition → to the target LLM's outcomes than on which structural score is used, and argue progress needs models of LLM sensitivity to predicate semantics.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
 articleWhen Learned Context Planning Fails to Beat Strong Retrieval: A Controlled Study of Planning, Routing, and Reranking for Long-Context QAYingrui Li, Han Chen
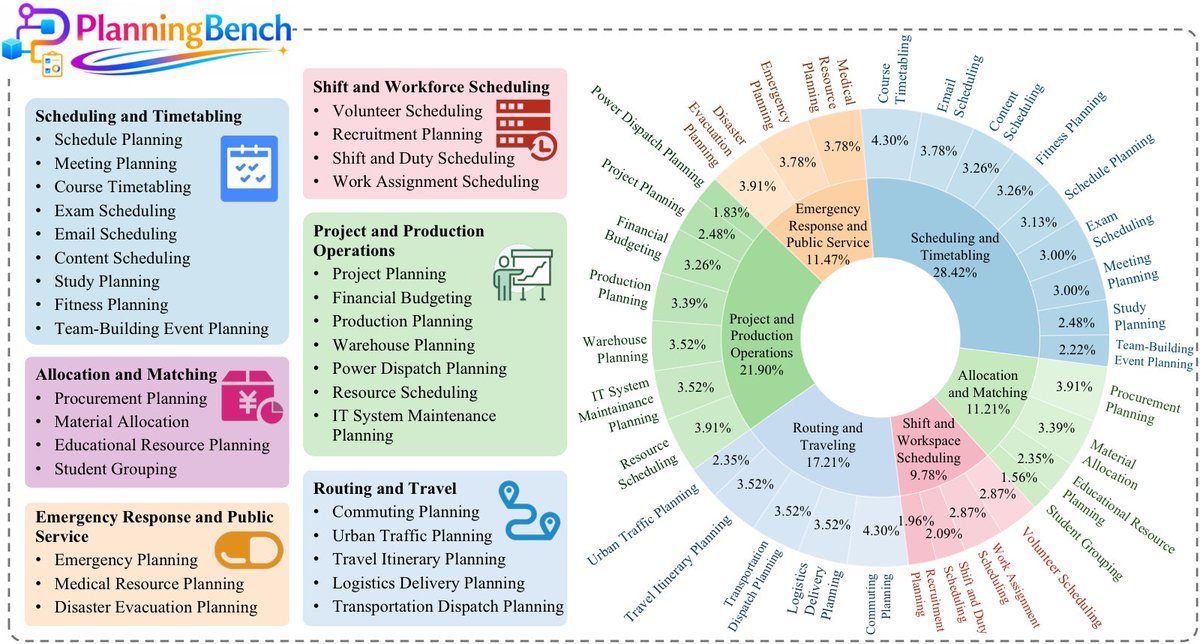 postPlanningBench puts LLM planning under automated verificationTencent Hy
 articleHarness Engineering for Predictable Agentic Systems: An Empirical Study of Deterministic Execution ConstraintsSaransh Dhage