Terminal-Bench-Science leaderboard: only two models clear 50%
- Source
- x.com
- Date

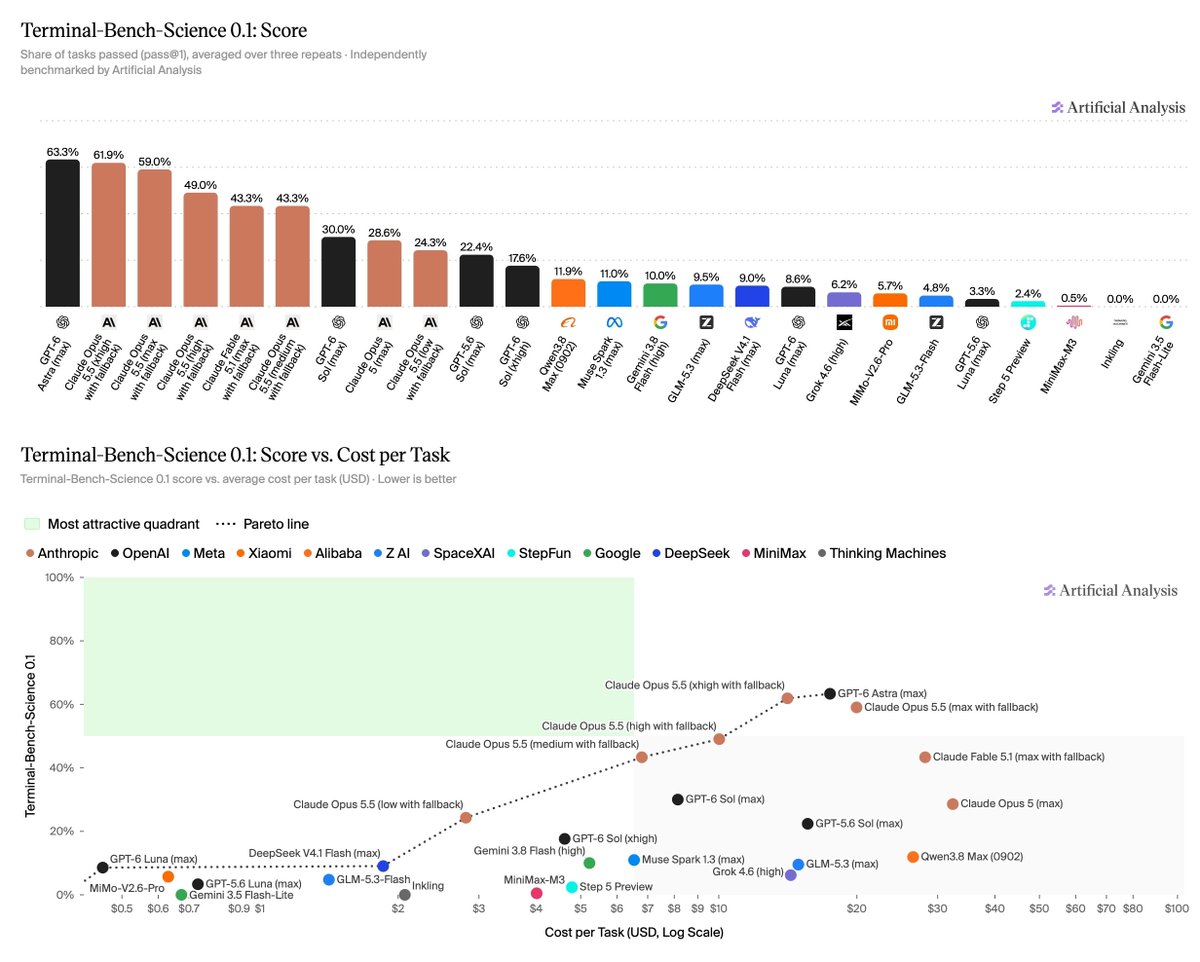
Today we’re launching our leaderboard for Terminal-Bench-Science 0.1, an agentic benchmark for scientific research work. GPT-6 Astra (max) and Claude Opus 5.5 (xhigh) currently top it at 63% and 62% Terminal-Bench-Science 0.1 was announced in August 2026, built by @StevenDillmann and researchers at Stanford with the @terminalbench team and a global community of open source scientific contributors. It has 70 expert-curated tasks based on real research in five domains: life sciences (19), physical sciences (17), mathematical sciences (17), engineering sciences (9), and earth sciences (8). As with Terminal-Bench, each task drops an agent into a sandbox environment with the data, tools and instructions for a task, and the agent runs from start to finish. Automated tests grade every task pass/fail, and we report the average pass@1 over 3 attempts. Key takeaways: ➤ Only two models score above 50%: GPT-6 Astra (max) at 63%, and Claude Opus 5.5 at 62% (xhigh) and 59% (max). Recent releases have made large advancements, but even the top model, GPT-6 Astra, has significant headroom ➤ Life sciences is the lowest-scoring domain for most leading models, though domain scores are noisy with…
Context
Terminal-Bench-Science 0.1 tests whether an can carry out a piece of scientific research work from start to finish, and the best models currently pass a little under two-thirds of its tasks. Artificial Analysis launched a leaderboard for the , which was built by Steven Dillmann and researchers at Stanford with the Terminal-Bench team and open source scientific contributors. It has 70 expert-curated tasks based on real research in five domains: life sciences, physical sciences, mathematical sciences, engineering sciences and earth sciences. Each task drops the agent into a with the data, tools and instructions it needs, and automated tests grade the result pass or fail. The reported score is the share of tasks passed on a single attempt, averaged over three runs.
Only two models score above 50%: GPT-6 Astra at 63% on its max setting, and Claude Opus 5.5 at 62% on xhigh and 59% on max. The best open-weights models score far lower, with GLM-5.3 at 10% and DeepSeek V4.1 Flash at 9%, more than 50 points behind the leaders. Artificial Analysis says recent releases have made large advances but that even GPT-6 Astra has significant headroom.
The breakdown by field is suggestive but rough. Life sciences is the lowest-scoring domain for most leading models, and Claude Opus 5.5 on xhigh passes 71% of mathematical sciences tasks but 46% of life sciences tasks. Each domain has only 8 to 19 tasks, so a task or two can move a domain score noticeably, and Artificial Analysis itself calls these scores noisy. Stanford AI Lab's release post for the benchmark is the companion item on the benchmark itself.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.
Checking sign-in…
Loading comments…