Models pass most individual rubric criteria yet rarely deliver a fully acceptable legal work product. All-pass grading shows how far agents are from unsupervised professional output.
Key takeaways · AI-distilled
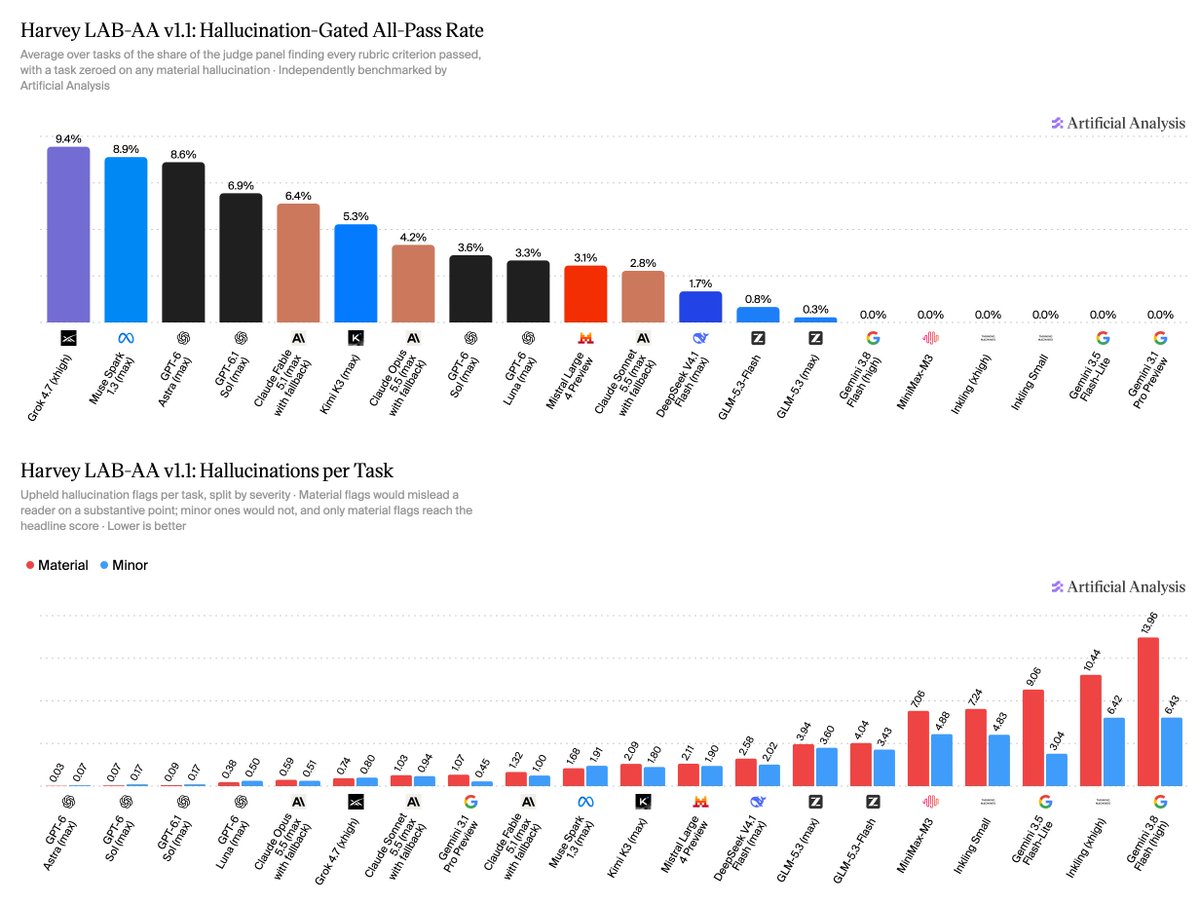
Harvey LAB-AA grades 120 private legal tasks across 24 practice areas on an All-Pass Rate: a task counts only if every binary rubric criterion passes, with no partial credit.
Claude Fable 5 led at launch with 14.2% all-pass, about double Opus 4.8 and GLM-5.2 at 7.5%, yet still left about 86% of deliverables incomplete; 13 of 28 models fully passed zero tasks despite high per-criterion pass rates.
Cost spans about 950x: Fable 5 cost about $18.9 per task, while GLM-5.2 matched Opus 4.8's all-pass rate at about $1.3 per task, around 15% of Opus's cost, and in about 5 minutes versus 18.5.
AA's live leaderboard now reports Harvey LAB-AA v1.1, whose scores are not directly comparable with the launch results in this article.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.