StepAudio 2.5 ASR: 30-minute inputs at $0.022 per hour
- Source
- x.com
- Date

StepAudio 2.5 ASR is here! 4x faster decoding. 30-minute continuous audio. $0.022/hour. We built this to push ASR further — faster inference, longer inputs, bilingual accuracy that holds up, and a price point that actually scales. ⚡ 4x decoding speed vs. previous generation ⚡ 30-min continuous audio processing ⚡ Top-tier bilingual (EN/ZH) performance ⚡ 80% lower inference cost — API at $0.022/hr For more details, check out: - Documentation: https://t.co/oiya8DpmfM - Demos: https://t.co/9ob48LOGqs - Model card: https://t.co/xo1YDteuQG
Context
StepFun released StepAudio 2.5 ASR, a speech-to-text model the company says decodes 4 times faster than its previous generation, handles 30 minutes of continuous audio without breaking it into chunks, and prices API access at $0.022 per hour, which StepFun describes as an 80% cost cut from the earlier model.
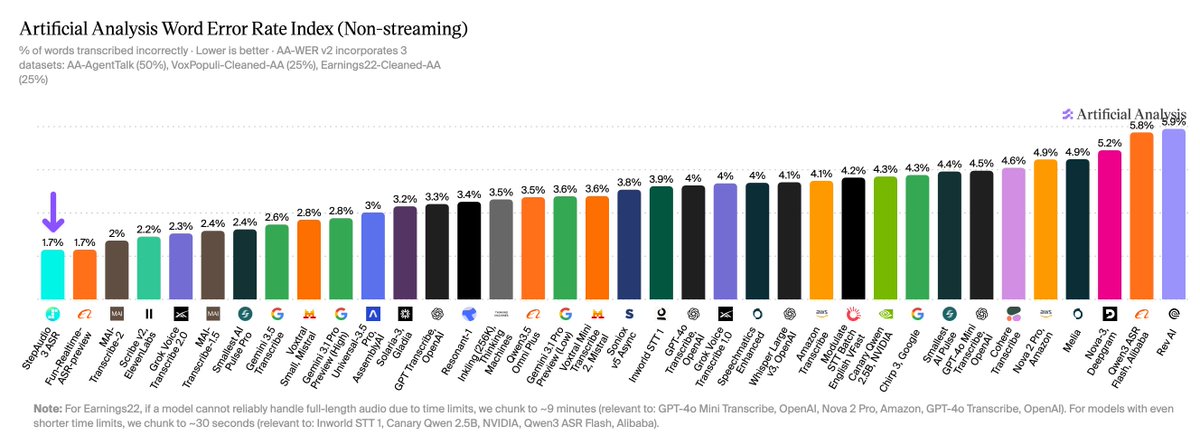
StepFun also claims strong bilingual accuracy across English and Chinese, but did not publish a word-error-rate figure or independent comparison alongside this announcement, so the accuracy claim is StepFun's characterization rather than a measured number. The pricing and processing-length figures are concrete and checkable against the linked documentation and model card.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…