Opus 4 6 Takes Lead In Agentic Real World Knowledge Tasks
Source
artificialanalysis.ai
Author
Artificial Analysis articles
Date
Why it matters
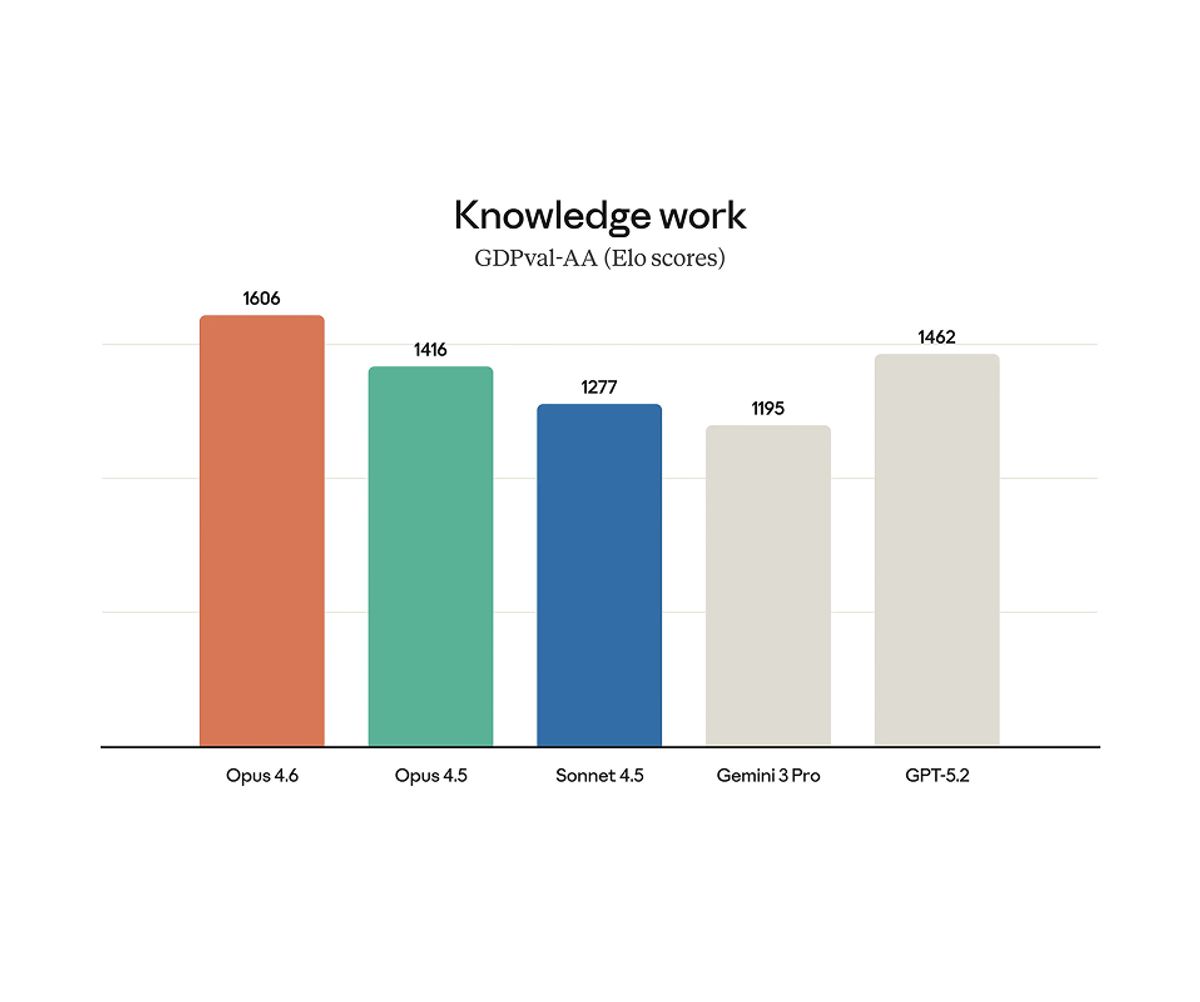
Opus 4.6 reaches 1606 Elo on GDPval-AA, about 70% head-to-head win rate over GPT-5.2 xhigh, by using more turns and viewing its own outputs. It was the costliest model tested on the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.