The inference bottleneck turned out to be the network
- Source
- x.com
- Author
- Z.ai
- Date
Context
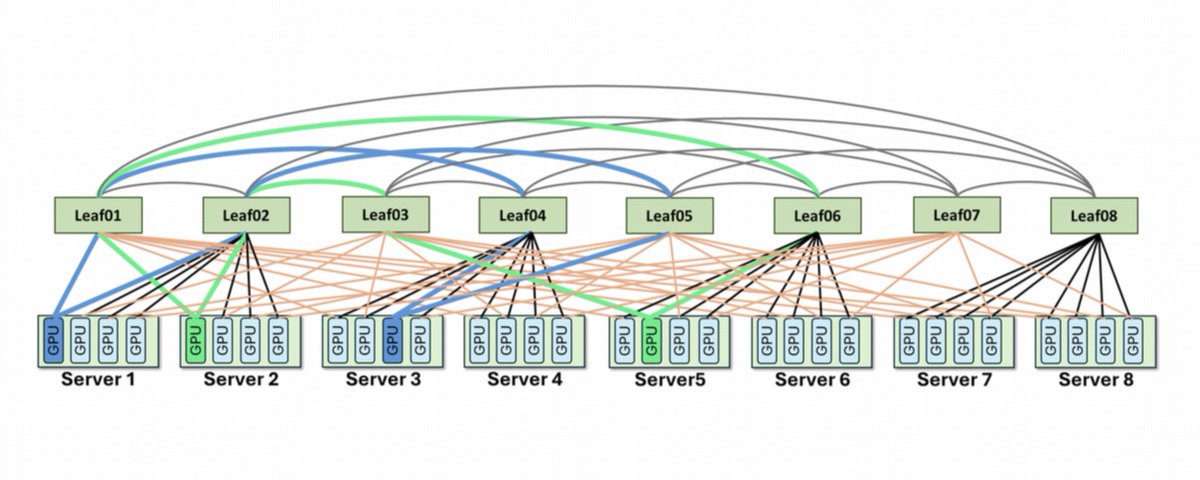
Z.ai reports that changing the network connecting its GPUs improved a GLM-5.1 serving cluster without changing the GPUs, applications or software stack. The ZCube design, which Z.ai deployed with Harnets.AI and Tsinghua University, removes an upper switch layer and uses complementary connection patterns to spread traffic that would otherwise concentrate on particular links. That traffic includes cached model state transferred between machines processing prompts and machines generating responses. The company explains the mechanism in its ZCube article.
In the reported before-and-after deployment comparison, average GPU throughput increased by about 15%, while the 99th-percentile wait for the first generated text fell by 40.6%. These workload-specific results show how network congestion can leave existing computing capacity underused.
 postWe’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
- postGLM-5 lands in Zhipu's Coding Plan Pro as pricing shifts
 articleZ.ai details GLM-5.3's leap in exploit analysis and staged release
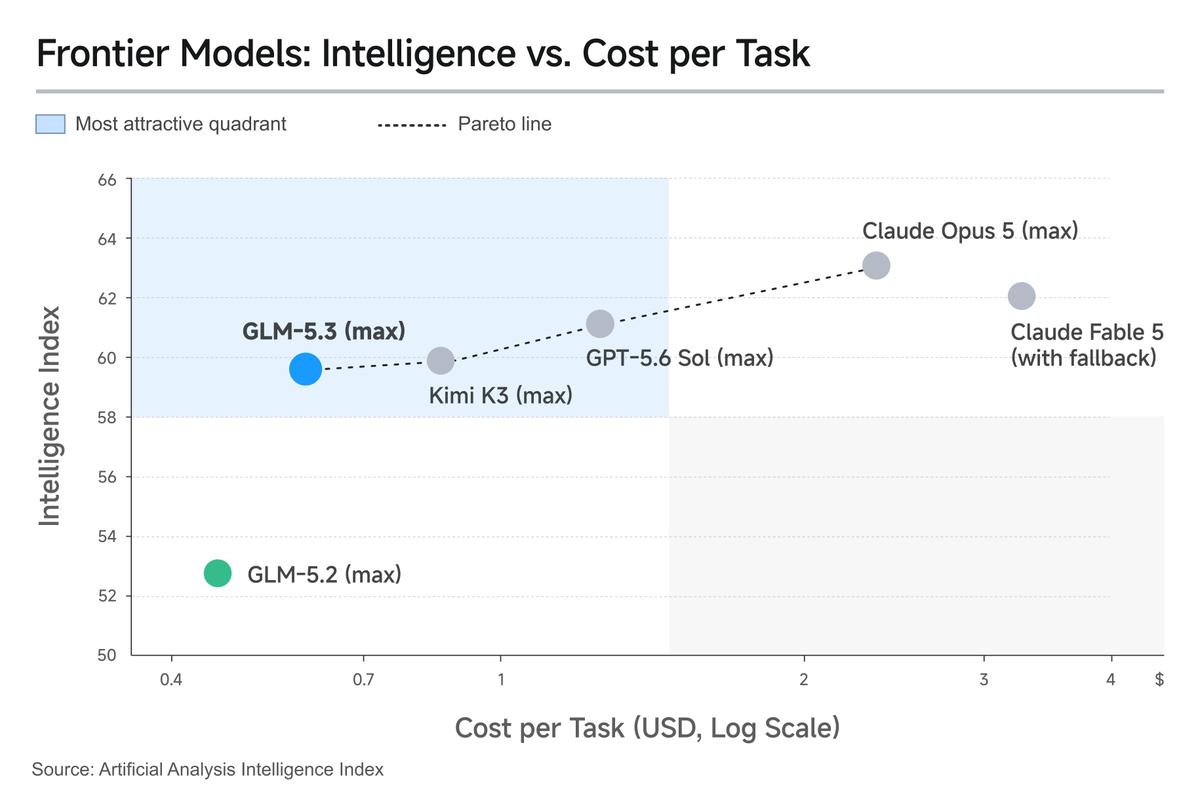 postGLM-5.3 API launches for coding and cybersecurity agentic tasks
 videoKV Cache-Aware Routing and P/D Disaggregation on Kubernetes — Yuchen Fama & Ashish Kamra, Red HatAI Engineer
 articleAnother Giant Leap: The Rubin CPX Specialized Accelerator & RackDylan Patel
 videoVertical Mobility: Inference from MVP to Trillion-Parameter Workloads — Sitanshu Gupta, CoreWeaveAI Engineer
Checking sign-in…
Loading comments…