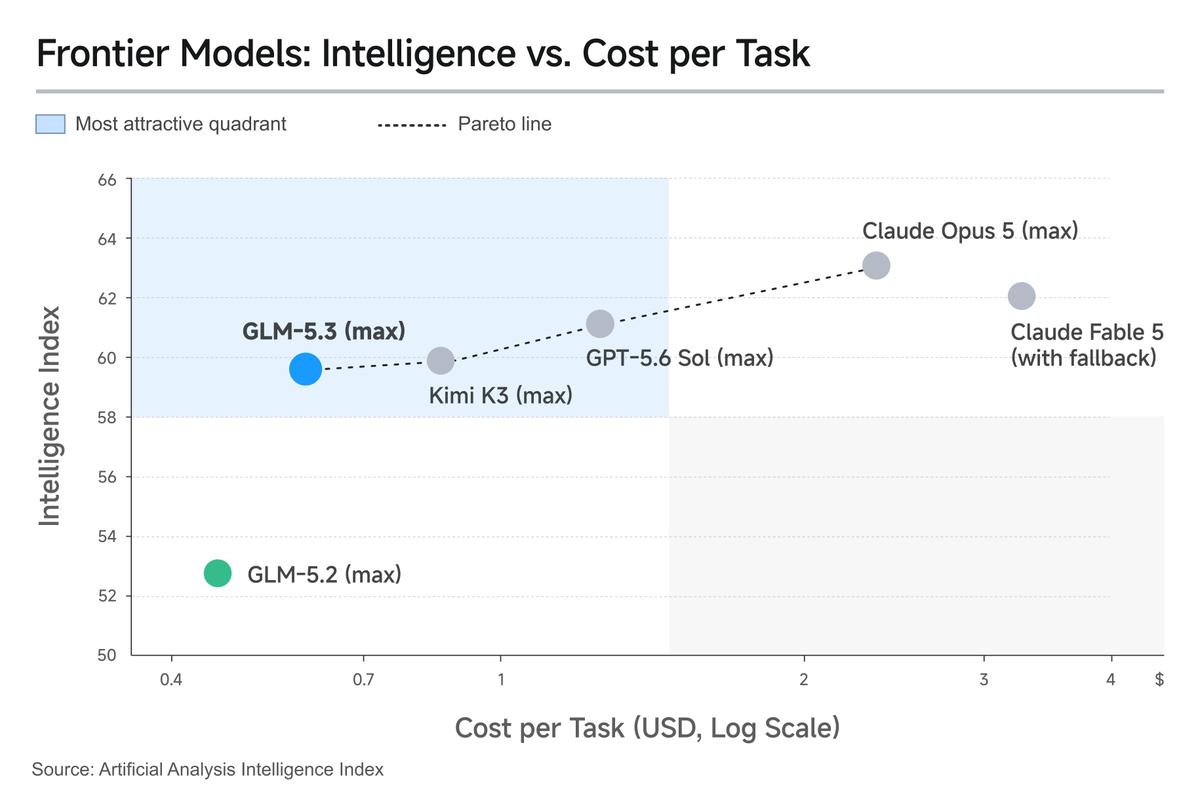
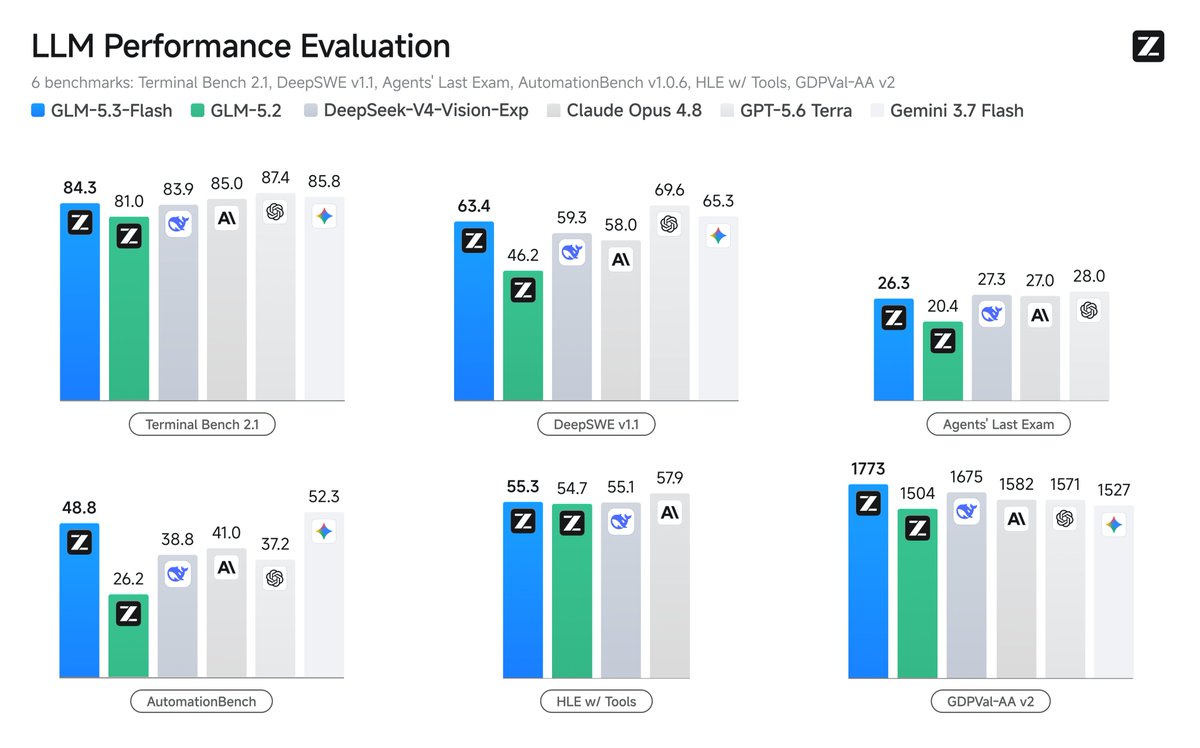
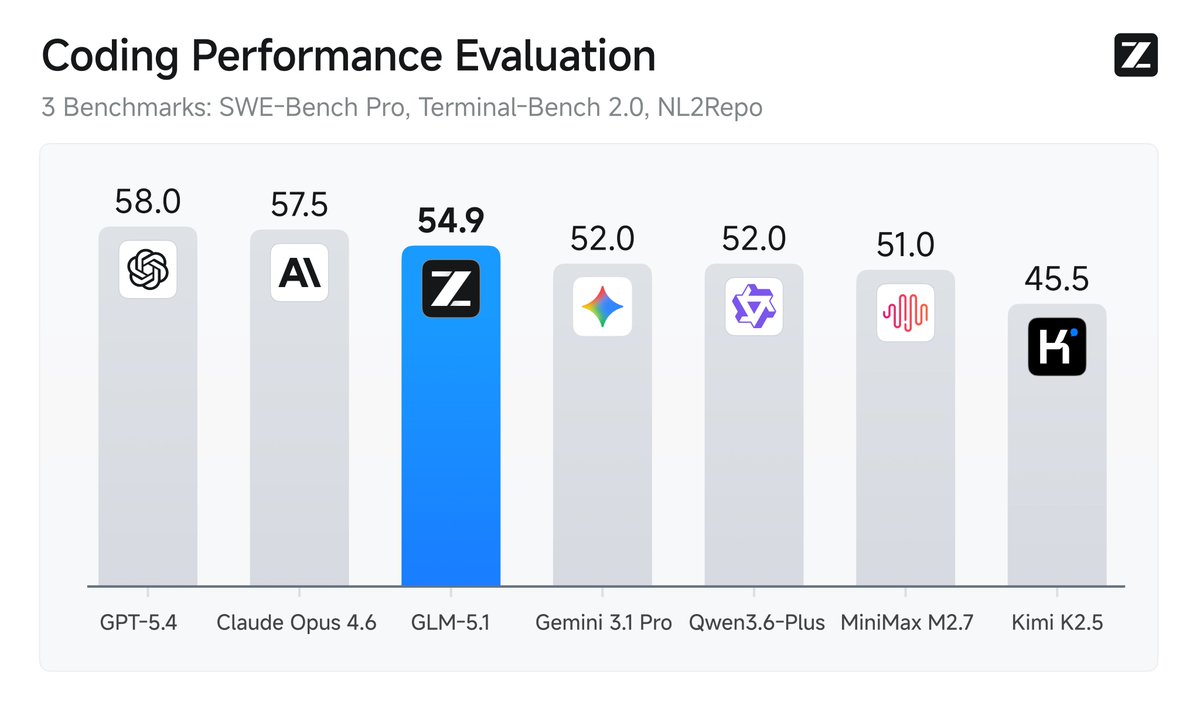
We’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
The system went from its first successful run to production readiness in less than two weeks, with end-to-end throughput tripling relative to the initial baseline.
The key was dense feedback: local correctness tests, execution traces, microbenchmarks, and end-to-end measurements that enabled targeted hypothesis testing rather than reliance on aggregate performance metrics alone.
https://t.co/yUf6OpJD7c
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Why it matters
Demonstrates a concrete agentic-engineering workflow: pairing a coding model with dense, structured feedback signals rather than coarse end-to-end metrics speeds up real infra optimization work.