GLM-5.3 API launches for coding and cybersecurity agentic tasks
- Source
- x.com
- Date
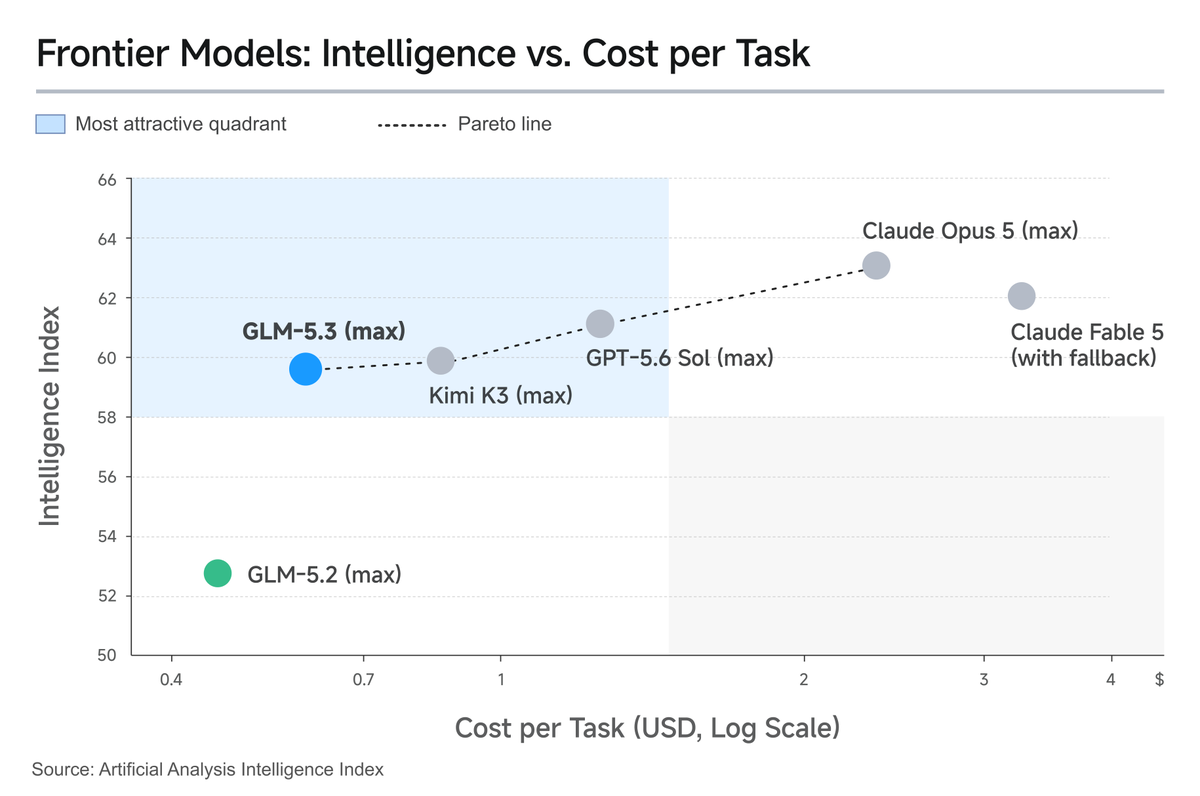
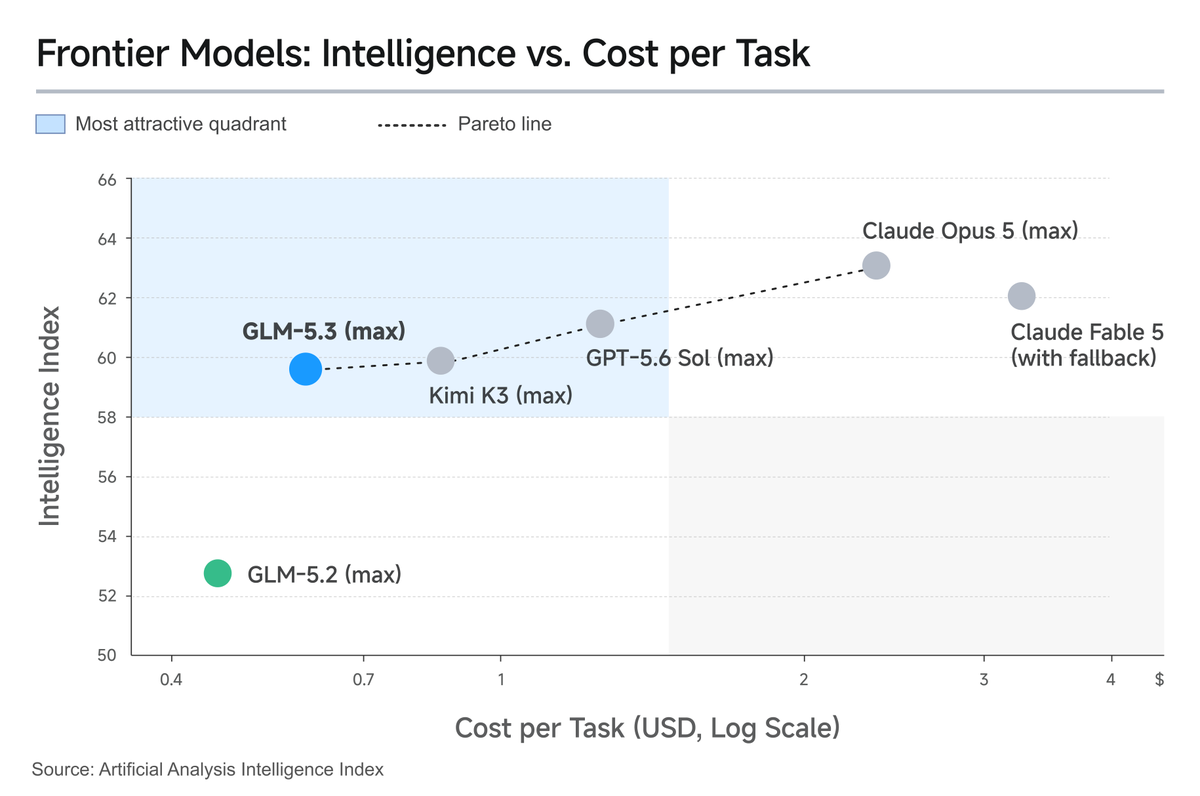
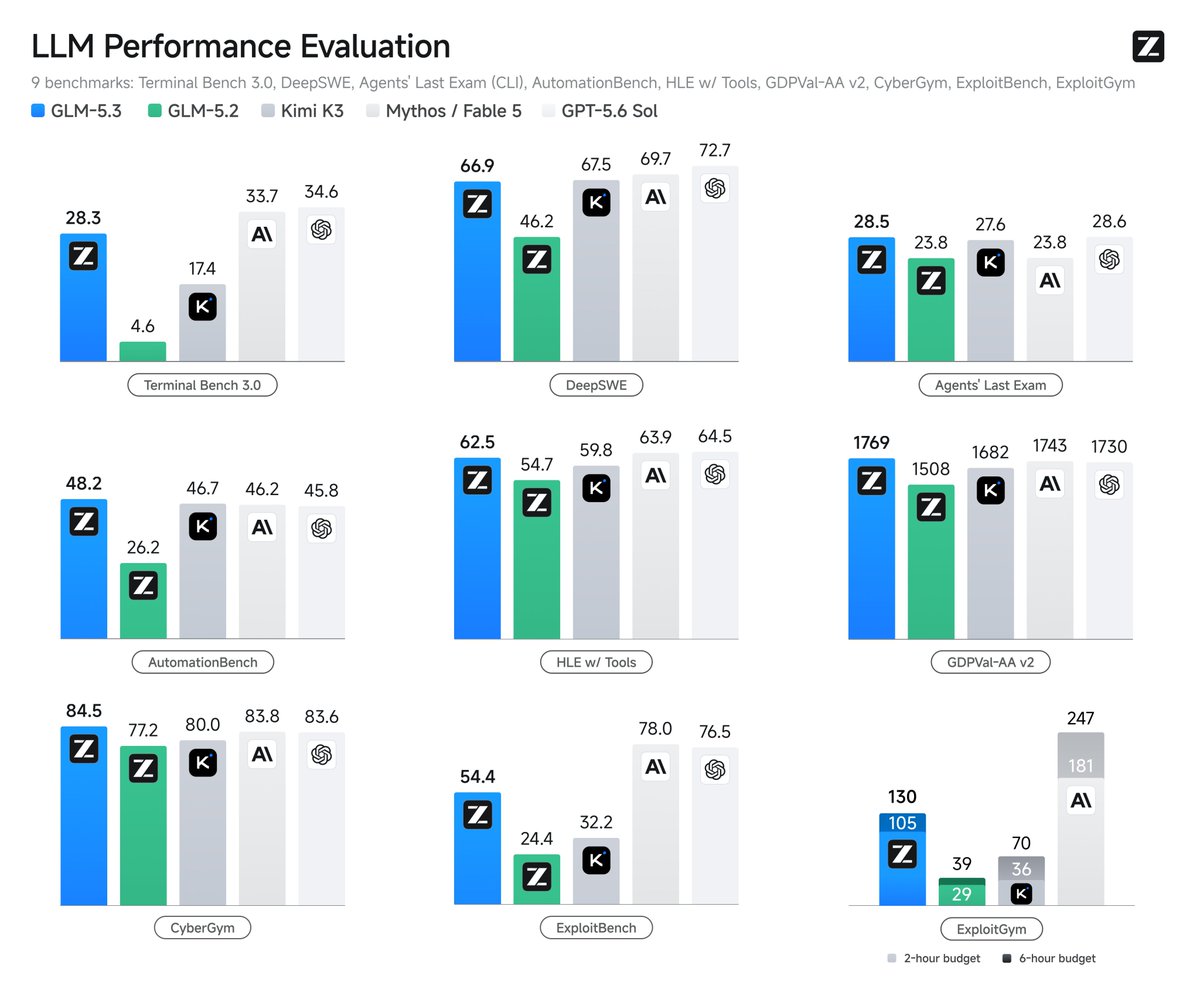
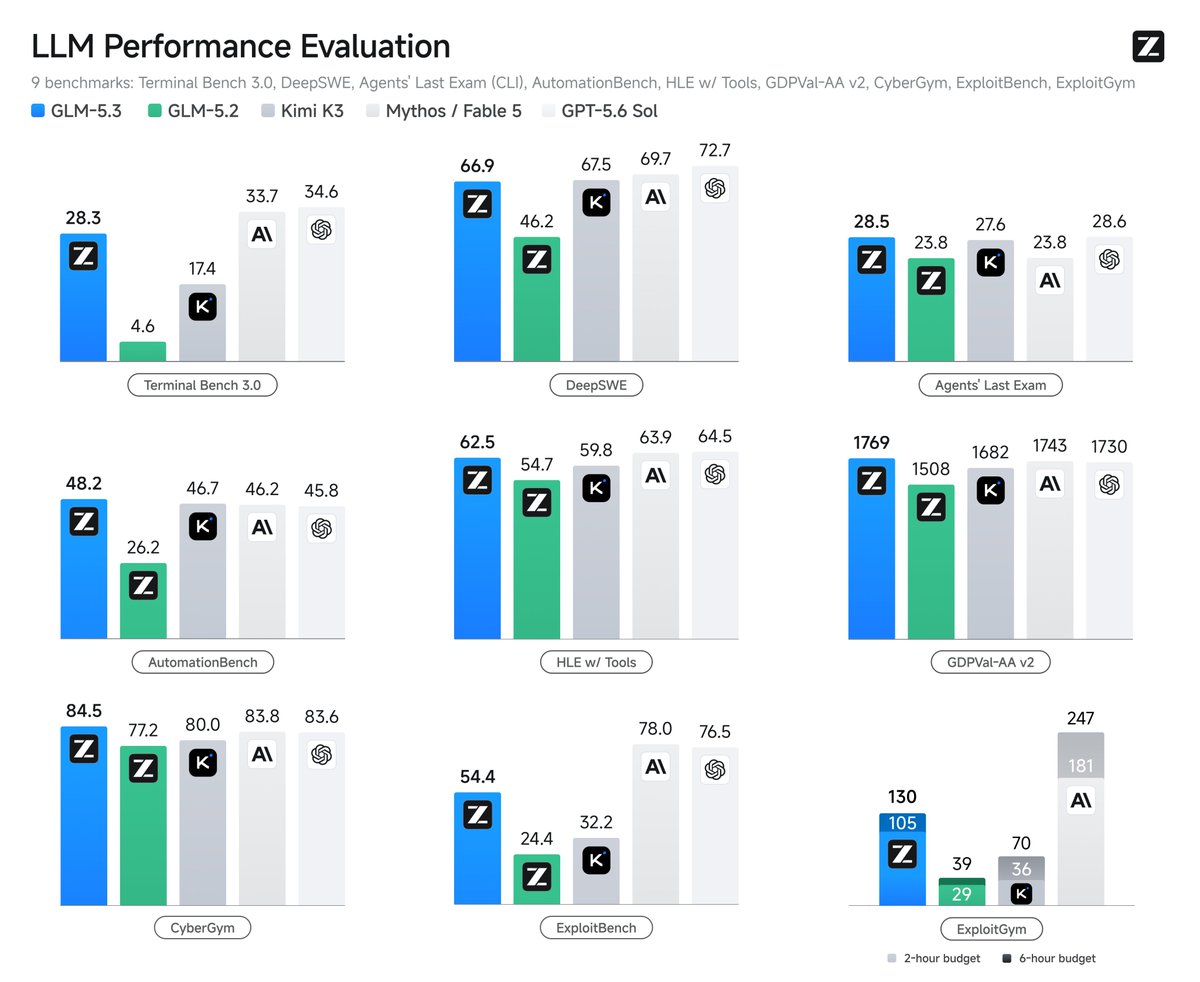
Z.ai's GLM-5.3 is now live via API and partner gateways at the same price as GLM-5.2, positioned for coding, defensive cybersecurity, and long-horizon agentic workloads. Third-party providers are already integrating it at roughly half the benchmark cost of frontier closed models, and early adopters report real accuracy gains on internal benchmarks. On the security side, Z.ai detailed large jumps in exploit-analysis testing: an 84.5% score on CyberGym and 54.4% on ExploitBench, both well ahead of GLM-5.2, plus more completed tasks on ExploitGym. Z.ai plans to ship the open weights only after staged access to vetted security partners, backed by a public vulnerability disclosure ledger, a deliberate slower rollout for a model this capable at finding exploits. For teams weighing frontier-model cost against capability, GLM-5.3 is now a concrete, cheaper agentic-coding option to benchmark against.

GLM-5.3 API is now live. - Built for coding, defensive cybersecurity, and long-horizon agentic tasks - Priced the same as GLM-5.2 - Available via the official API and partner model gateways Get started: https://t.co/3Dpy1tOdaM
Context
Z.ai's GLM-5.3 API went live, per its announcement, priced the same as the prior GLM-5.2 and available through the official API and partner model gateways. Z.ai frames it as built for coding, defensive cybersecurity work, and agentic tasks that run over many steps.
GLM-5.2, released about two months earlier, introduced a 1-million- and an MIT license with no regional restrictions (GLM-5.2 launch). A same-day post tied to the GLM effort reported GLM-5.3's score on the Artificial Analysis Index, a third-party aggregator, at 60 (corroborating post), the one externally sourced number available for comparison, since Z.ai's own launch post does not include benchmark scores.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 postWe’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
- postGLM-5 lands in Zhipu's Coding Plan Pro as pricing shifts
 articleZ.ai details GLM-5.3's leap in exploit analysis and staged release
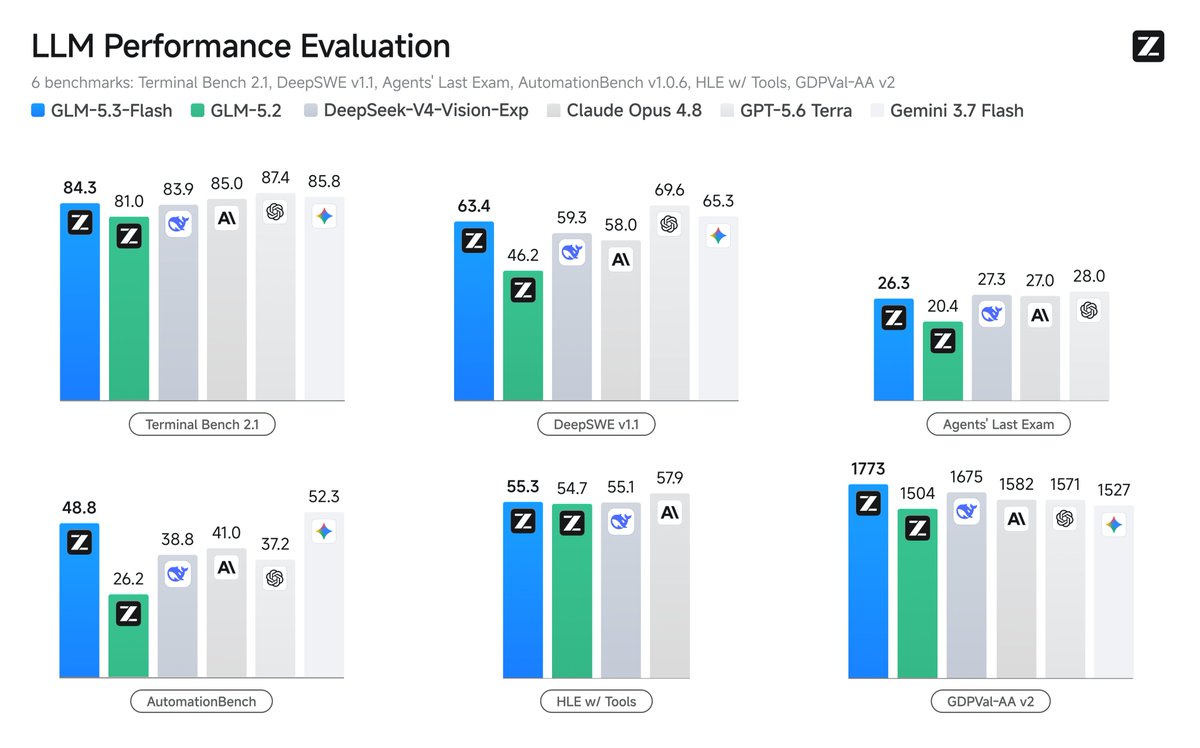 postGLM-5.3-Flash lands under MIT at $0.15 per million input tokens
Checking sign-in…
Loading comments…