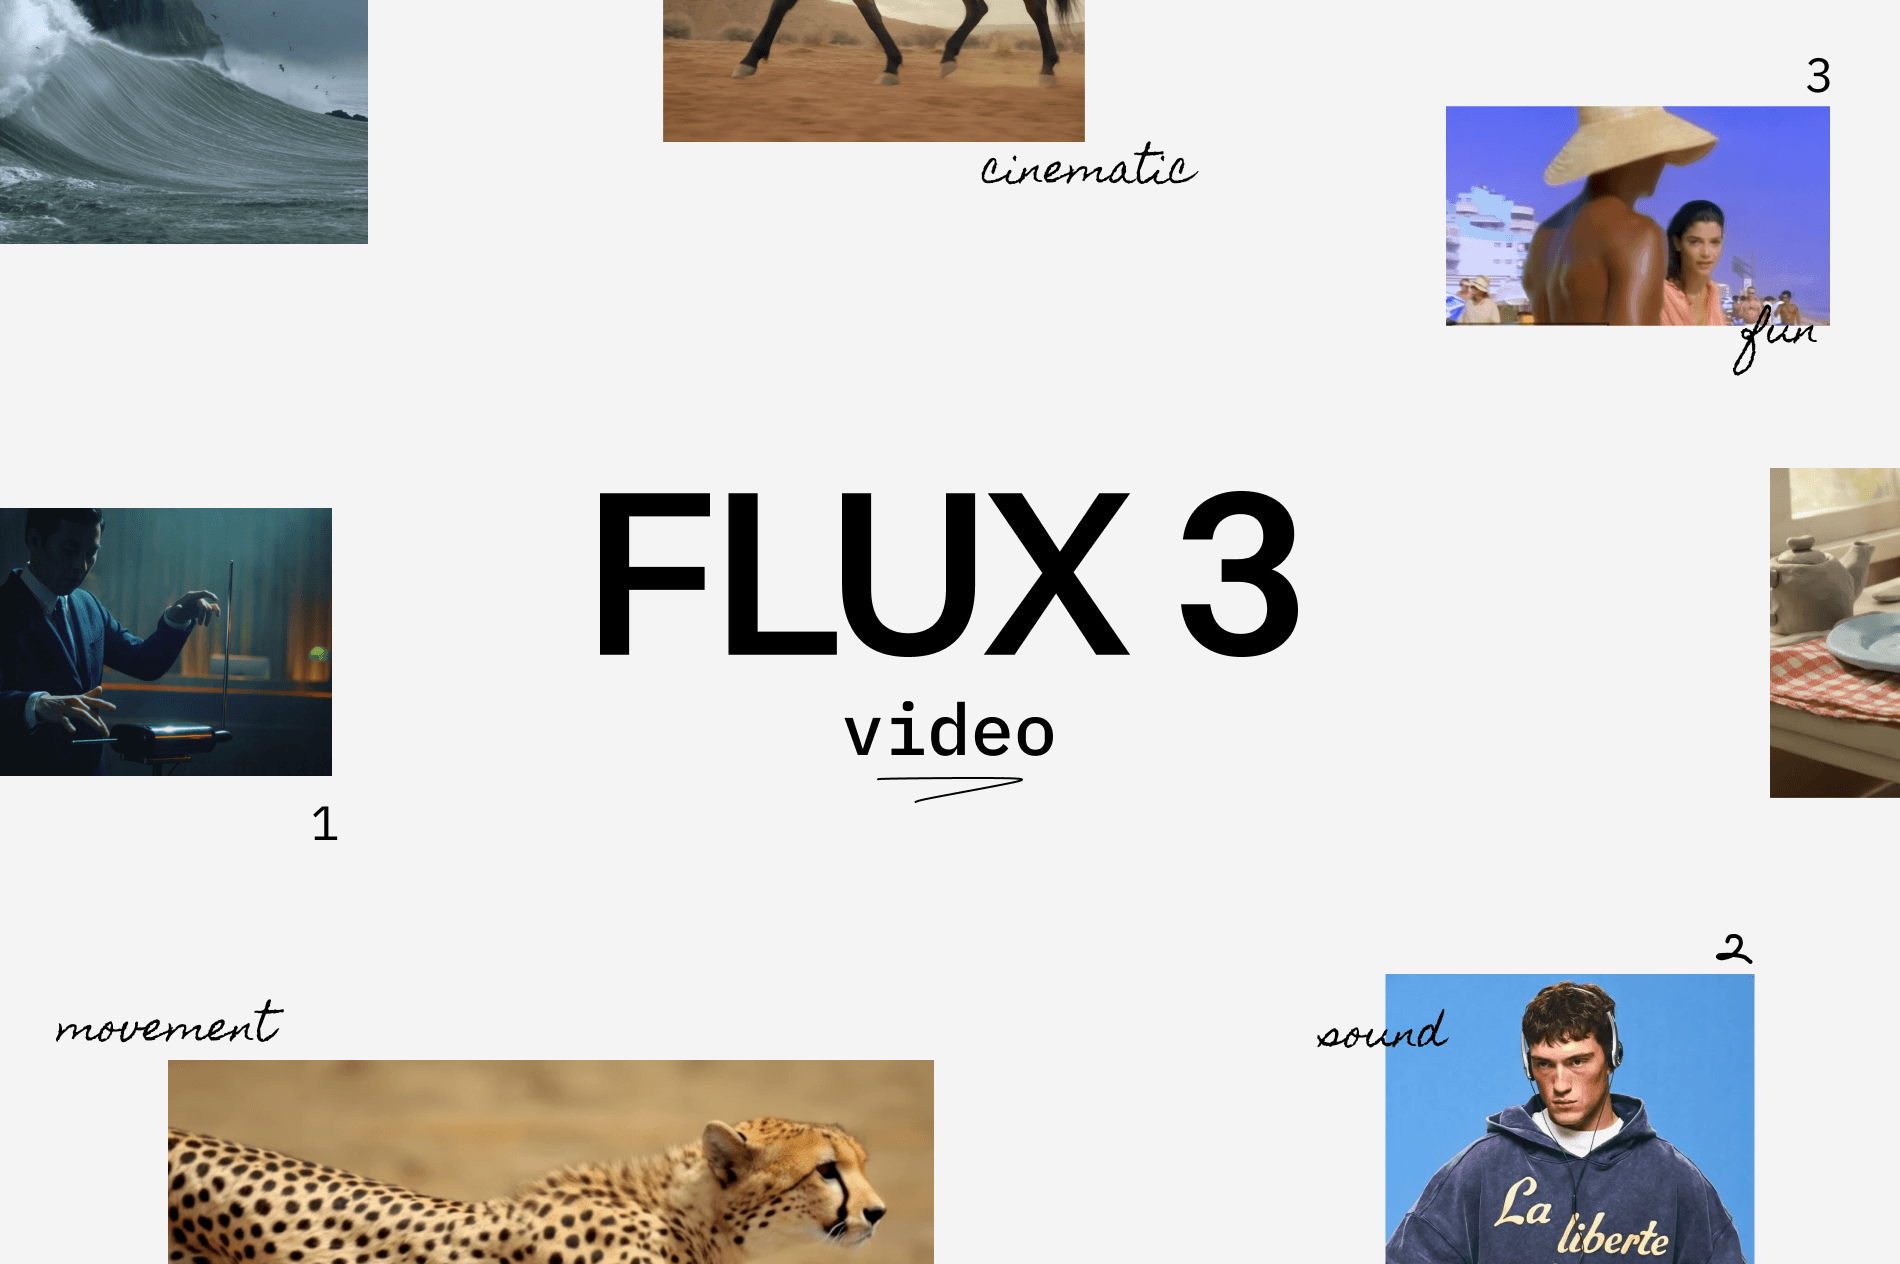
Black Forest Labs introduced FLUX 3 as a shared model for images, video, and audio. Its early-access announcement describes training those media together so the model can learn relationships between appearance, movement, and sound. The stated video capability includes generating clips with accompanying audio up to 20 seconds long from text or visual references.
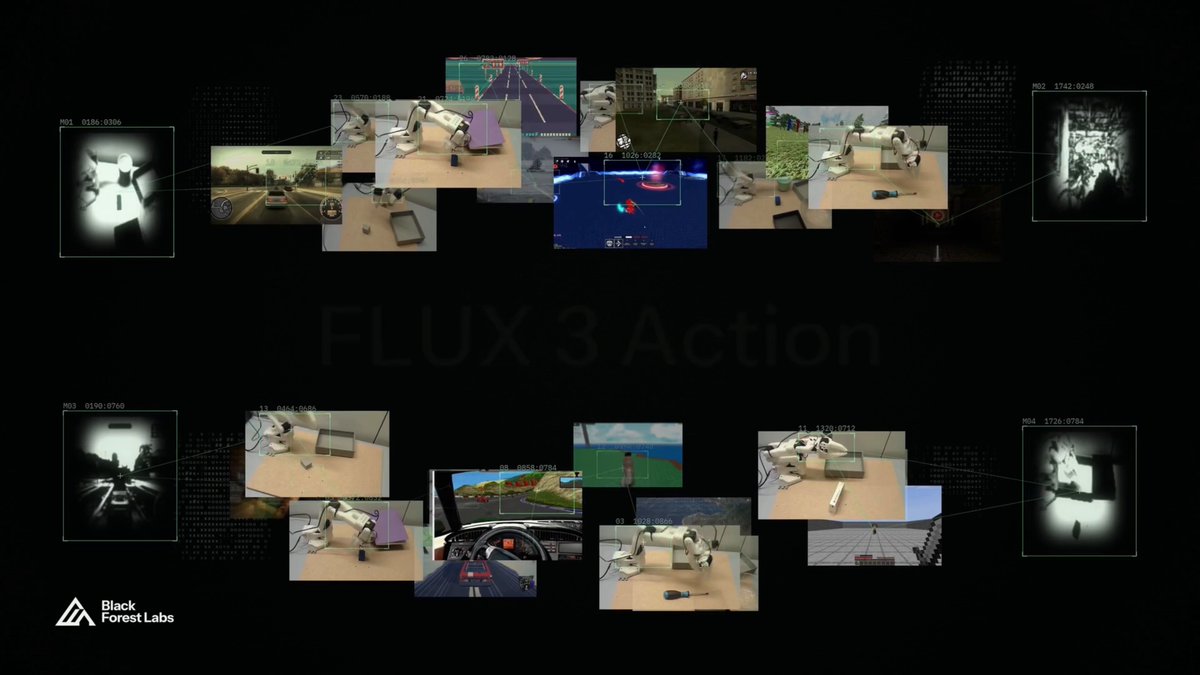
The release separates that initial video access from a broader rollout plan. Image access, action-prediction capabilities, and an open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition → backbone have their own planned stages. The announcement supports a move toward coordinated media generation; those planned releases should not be read as capabilities already available to every user.
Terms in this piece · Glossary
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.