Eval notes: doom loops and harness fixes from a live puzzle benchmark
- Source
- x.com
- Date

hope you liked sokobanteg livestream and it was entertaining to watch the models trying to solve puzzles in their head. we hit some huge variance and some unfortunate doom loops this time. it also gave me some very useful observations of where the harness should intervene. for example, i added an early return when 16 inputs result in no screen change. since there is no give up function, some models burn inputs instead of trying harder. interestingly, in this run, terra survived for a long time and beat 51 level before i manually stopped the eval. this proves smaller models could do well if they believe in themselves. the next plan is to finish a unified harness based on pi, fix the python repl we give the models, and test newly released gemini carbon, muse models, and some chinese models. im also trying to prove the lower bounds of perfect solutions, so we have things to compare on when this eval gets more crowded. there may or may not be another livestream, i haven't decided yet.
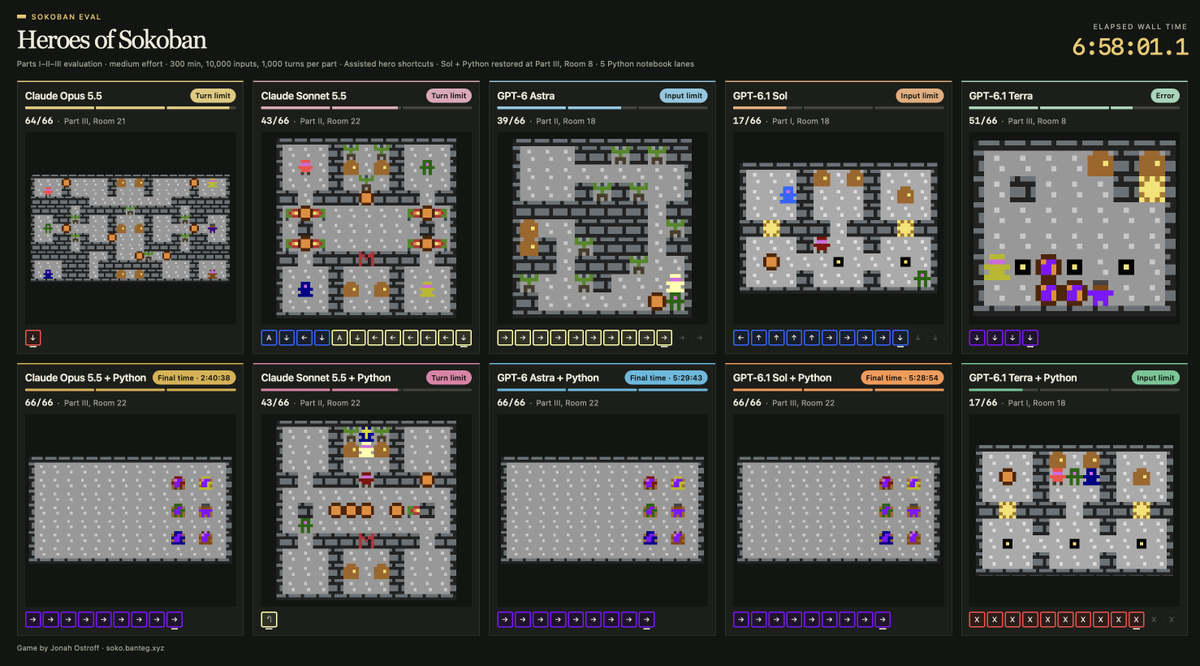
Shows a concrete fix for agents that burn actions without progress (stop after 16 inputs with no screen change), and that small models can run long when not derailed.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…