Every's early review: Astra 6.2 stops early on real coding builds
- Source
- x.com
- Date

BREAKING: OpenAI just launched Astra 6.2 and Sol 6.2!! We've been testing them for the last few weeks @every and, unfortunately, these models aren't great. Overall a disappointing release compared to Fable 5.2. - Writing. We found Astra 6.2 to be a step back from Astra 6 on writing. 6.2 appears to have been trained to very extremely concise and actionable—so much so that its writing is hard to understand, and it gives short answers when long answers would be appropriate. - Coding. We found performance to be similar to Astra 6 on most of our benchmarks. However, in real coding tasks Astra 6.2 seemed to stop too early frequently, which made it quite frustating to use on end-to-end builds. - Design. Astra 6.2 has good default design instincts. But it struggles to vary its designs, resulting in output that has a noticeable "house style". Full vibe check coming soon on @every!
Context
Dan Shipper reports that after testing them for the last few weeks at Every, the publication where his team tests new models before writing full reviews, he finds OpenAI's GPT-6.2 Astra and Sol disappointing next to Anthropic's Claude Fable 5.2. His post, quoting OpenAI's launch announcement, gives early findings for Astra in writing, coding and design.
Two of those findings describe a model that does too little. On writing, Every rates Astra 6.2 a step back from GPT-6 Astra: it appears to have been trained to be extremely concise and actionable, so its writing becomes hard to understand and its answers are short where a long one would fit. On coding, Astra 6.2 performed similarly to GPT-6 Astra on most of Every's benchmarks, but in real coding tasks it often seemed to stop too early, which made it frustrating to use for end-to-end builds. OpenAI's launch video says both models deliver better results on demanding tasks with fewer output tokens. Every's reports suggest that brevity can cost something on tasks that need a full explanation or sustained effort, though Every names training only as an apparent cause and does not tie it to OpenAI's efficiency goal.
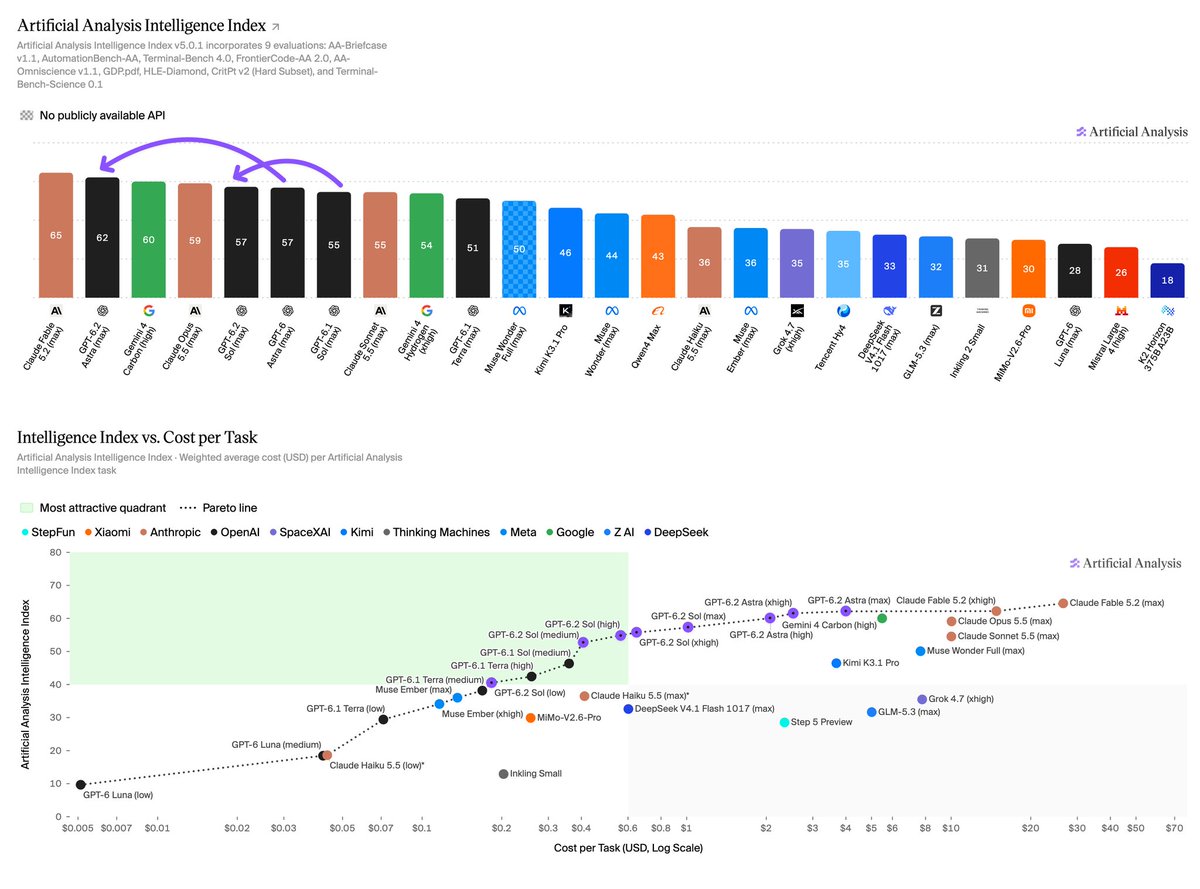
results released the same day fit the coding observation. Artificial Analysis found GPT-6.2 Astra no better than GPT-6 Astra on its Coding Index, and GPT-6.2 Sol more likely than its predecessor to leave key facts out of answers. On design, Every credits Astra with good default instincts but says it struggles to vary its designs, so its output has a noticeable house style. The post is a first impression and gives no scores, and Every's promised full review was not available for this explanation.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…