Ling 3.0 Flash Fin Scores 54.9% on Finance Agent v2 at $0.045 per Task
- Source
- x.com
- Date

Ant Group’s Ling 3.0 Flash Fin is a finance-specialized open-weight model that delivers strong financial analysis at budget-model pricing. On Finance Agent v2, it scores 54.9% at just $0.045 per task.

Context
Vals AI's result is a value claim rather than a leaderboard win. Vals AI reports that Ling 3.0 Flash Fin, a finance-specialized model from Ant Group, scored 54.9% on its Finance v2 at $0.045 per task, and it describes this as strong financial analysis at budget-model pricing. Open-weight means the trained model files are published, so a bank or developer can run the model on its own hardware instead of renting it only through Ant. An FP8 build of this model is also published on Hugging Face under the inclusionAI account.
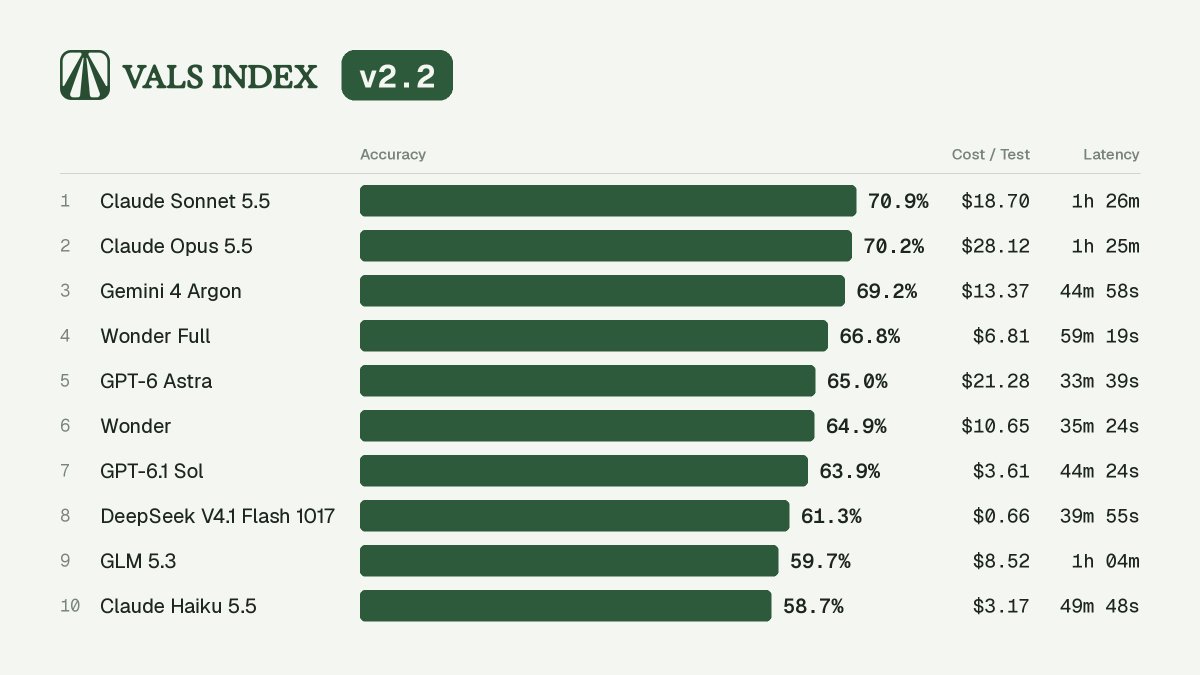
The post's text names no competing models, so it does not establish how far ahead of other cheap models Ling 3.0 Flash Fin sits, or how it compares with expensive general models. The version number also matters. Finance Agent is one of the benchmarks in Vals's own index, and Vals later shipped a minor revision, Finance Agent v2.1, as one of four benchmark updates in Vals Index v2.2. The 54.9% belongs to v2 and may not line up directly with scores reported on the revised test.
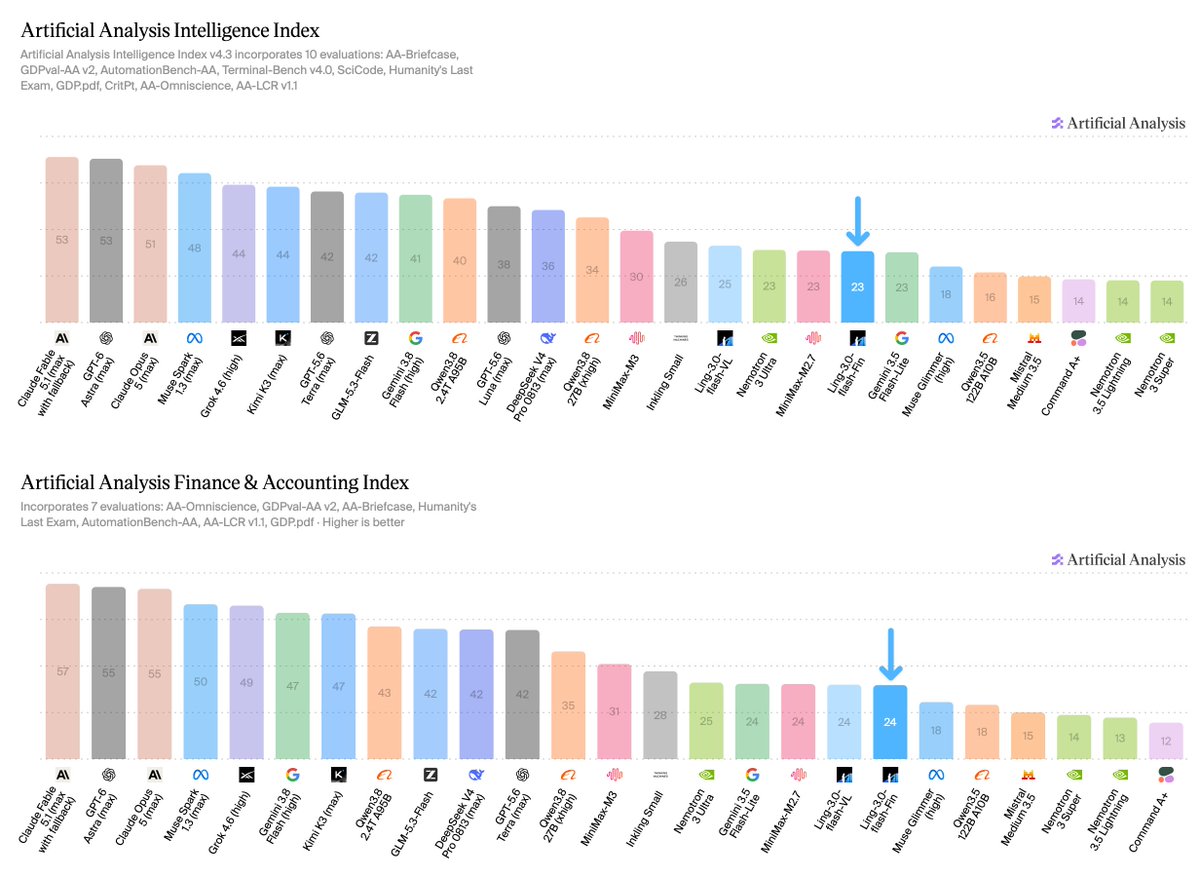
The model was already public before this score. Ant open-sourced Ling-3.0-flash-Fin in early September together with FinFIRST, a benchmark for financial search agents that Ant says experts built, and Artificial Analysis benchmarked the same model on its own finance and accounting index. Vals's number is a second outside measurement, on a different test, which helps a reader judge the model from more than its maker's own claims.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…