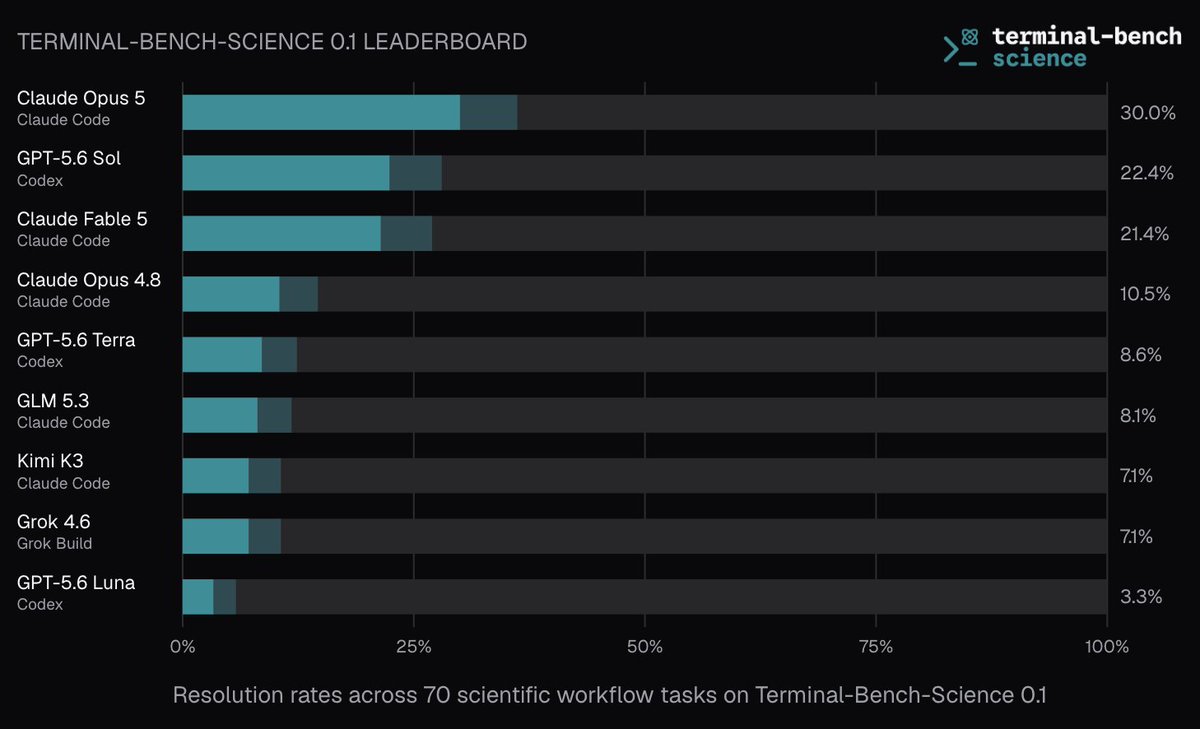
Terminal-Bench 2.0: the most impt coding agent benchmark of 2025 gets a v2! Launch + Q&A w/ founders
Source
youtube.com
Author
Latent Space
Date
Why it matters
Terminal-Bench 2.0 is a standard for measuring coding agents, and Harbor packages the tooling to evaluate and optimize your own agents against it.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 videoWhy Every Agent needs Open Source Cloud Sandboxes
 video[State of Post-Training] From GPT-4.1 to 5.1: RLVR, Agent & Token Efficiency — Josh McGrath, OpenAI
 video⚡️ Reverse Engineering OpenAI's Training Data — Pratyush Maini, Datology
 videoThe Agent-Native Cloud: 3M Users, 100K Signups/Wk, Data Centers, & Death PRs — Jake Cooper, Railway