Benchmarking Multilingual Conversational ASR
- Source
- research.withdavid.ai
- Author
- EliasLittle
- Date
Context
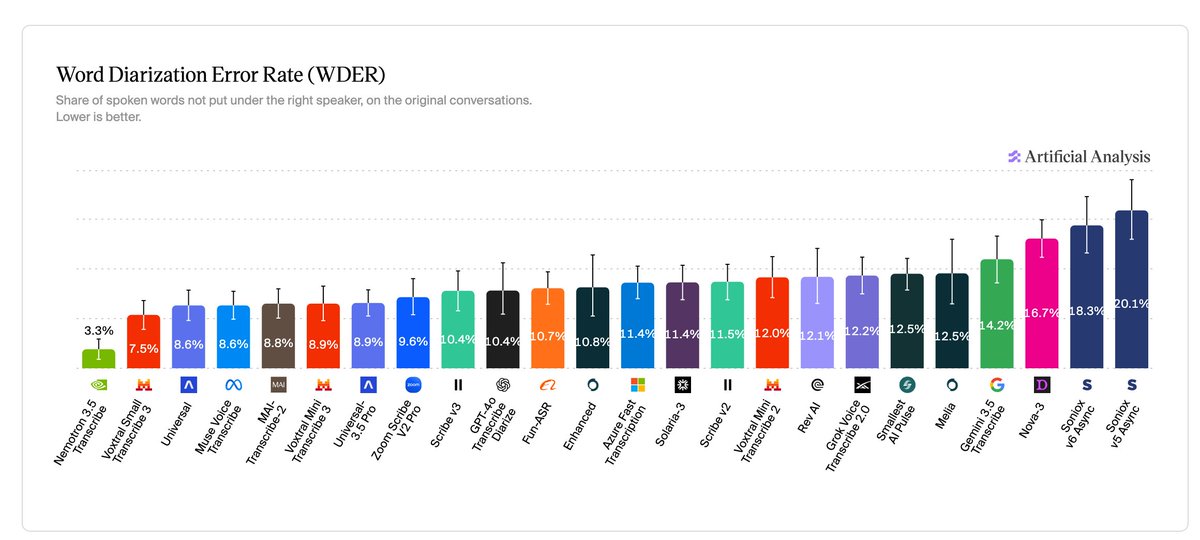
English transcription results can conceal much larger differences in other languages. The DAI-ASR-I18N benchmark evaluates unscripted conversational speech: 147 hours across 21 languages. Microsoft's MAI-Transcribe-2 had the lowest error rate in 18 of the 21 languages on the public set, while ElevenLabs' Scribe v2 led in the other three, including English.
How much systems differ depends on the language. In English, Korean, Mandarin, Spanish and Russian they cluster closely, with an average standard deviation across systems of 3.7 points. In Bengali, Hindi, Marathi, Tamil and Telugu the average spread is about 25 points. Overlapping speech was the hardest condition for every system, and the covers two-speaker conversations recorded on separate microphones, so it does not represent every recording setup. A multilingual product therefore needs results for its own languages and conditions rather than an English ranking.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…