Artificial Analysis launches Diarization Index for speaker attribution
- Source
- x.com
- Date

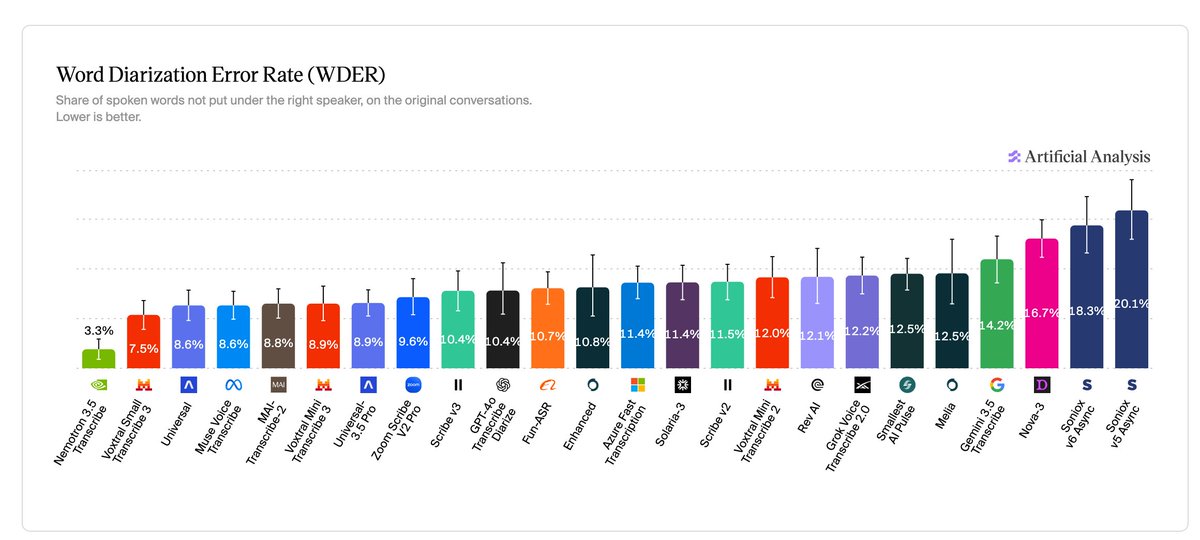
Announcing the Artificial Analysis Diarization Index, our new benchmark for who said what in speech to text The Diarization Index scores APIs on Word Diarization Error Rate (WDER): the share of words given to the wrong speaker or to no speaker, across 97 conversations of two to eight people, with equal weight on each group size. Nemotron 3.5 Transcribe from @NVIDIAAI leads at 3.3%, ahead of Voxtral Small Transcribe 3 at 7.5%. Thread below 🧵
Context
Artificial Analysis, which runs independent leaderboards for AI models, has started scoring transcription services on a question that word accuracy leaves out: whether each word is credited to the person who said it. Working out who is speaking when is called diarization. The new Diarization Index scores speech-to-text APIs on Word Diarization Error Rate, or WDER, which Artificial Analysis defines as the share of words given to the wrong speaker or to no speaker at all, so lower is better. The test set is 97 conversations with two to eight people in each, and every group size counts equally toward the final score.
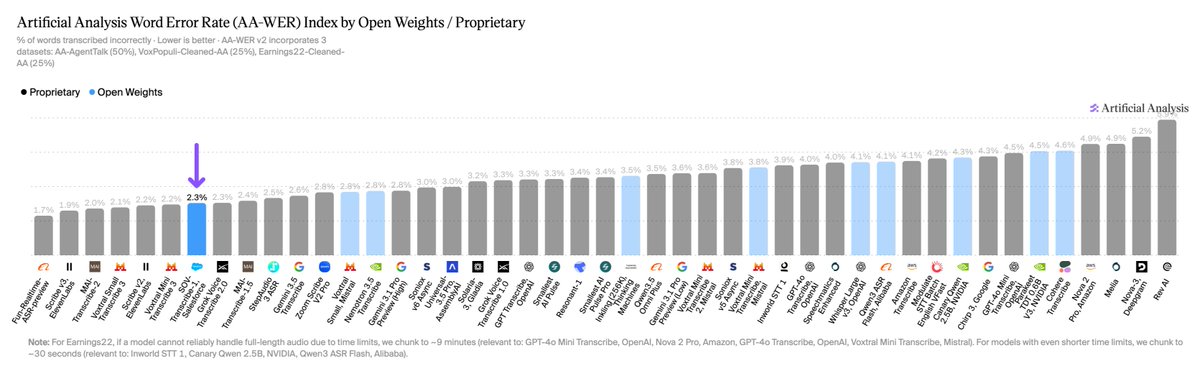
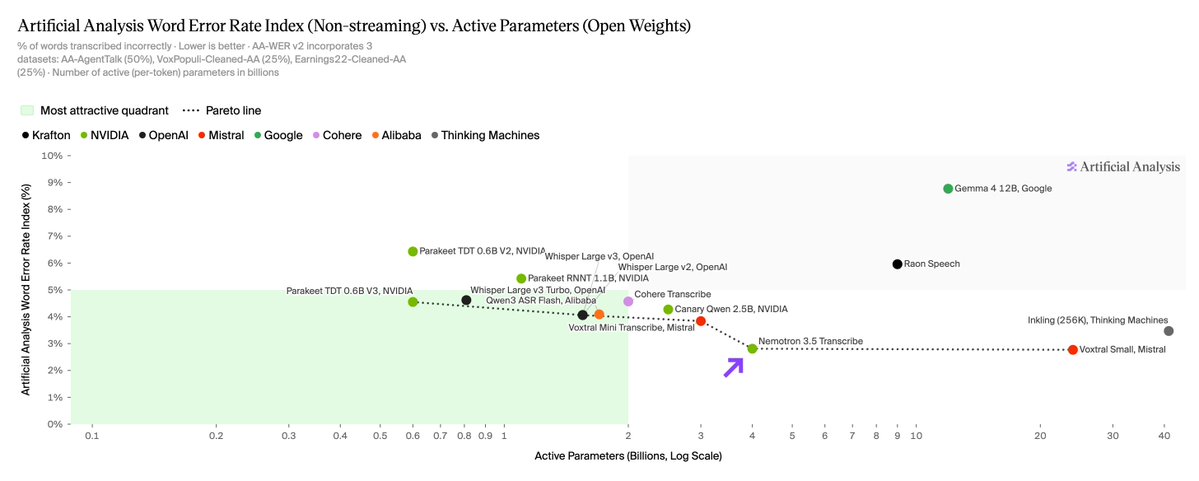
In the first results, NVIDIA's Nemotron 3.5 Transcribe leads with a WDER of 3.3%, meaning 3.3 words in every 100 went to the wrong speaker or to none, ahead of Mistral AI's Voxtral Small Transcribe 3 at 7.5%. NVIDIA describes Nemotron 3.5 Transcribe as able to produce a transcript that labels who is speaking for recordings with up to eight speakers, and Artificial Analysis had already placed it level with the best open-weight models on word accuracy. This adds speaker attribution to that record, as Artificial Analysis measures it. Only the opening post of the announcement thread was collected. The rest of the thread, its chart and any methodology page were not read, so the full ranking, where the conversations come from and how scores change with the number of speakers are not covered here.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…