Hugging Face Journal Club: Kimi K3
- Source
- youtube.com
- Author
- Hugging Face
- Date
Context
Moonshot AI's Kimi K3 incorporates lower-precision computation into training. The official repository says -aware training begins during supervised , using MXFP4 weights and MXFP8 activations. These are compact numerical formats for the model's stored parameters and intermediate calculations.
The journal-club discussion describes the motivation as memory savings from quantizing the weights and activations of the layers. Because the model is trained with the lower-precision formats from the fine-tuning stage onward, the format it is meant to run in is part of how it learns, not only a later compression step. The repository documents this design choice without a standalone measurement of its contribution to overall performance.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.


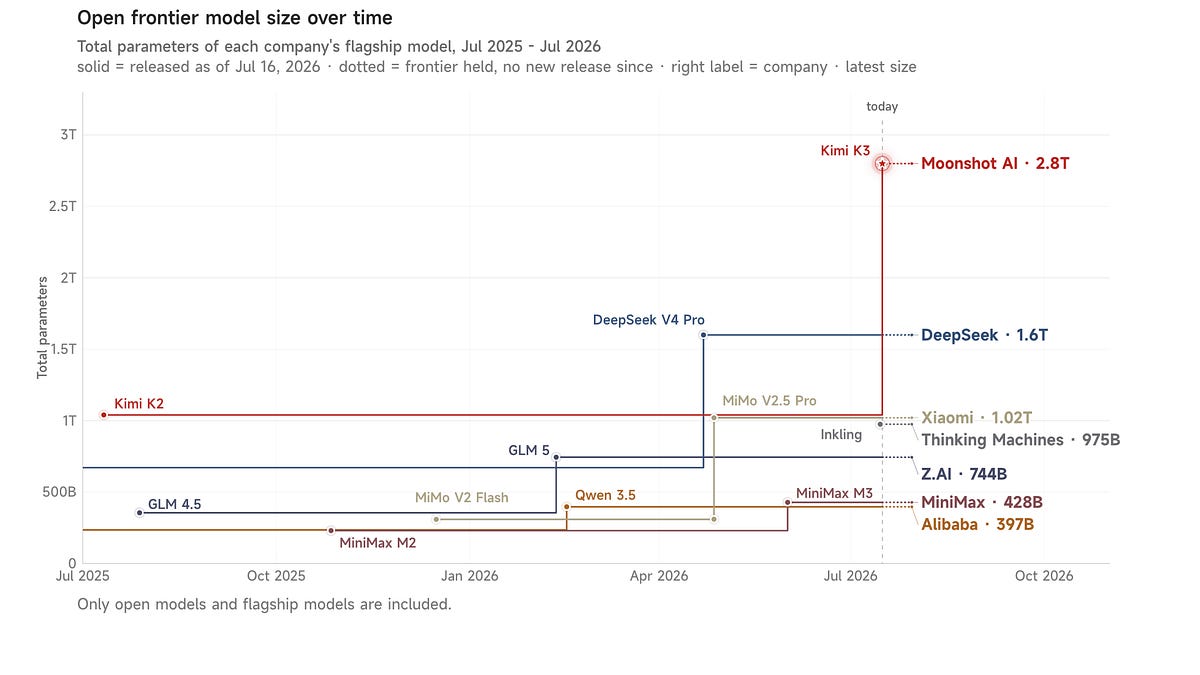 articleKimi K3 2.8T-A50B: the largest open model ever released; Opus 4.8-class at Sonnet 5 pricingLatent Space
 articleWhy Kimi K3's Architecture Is a Masterclass in AI EfficiencyAlphaSignalAI
 article[AINews] Kimi 3.1 Pro 104BA-2.8T: Fable-5.1-Class Open Weights narrows Closed-AI lead to 1 month... and Pro Highspeed API with 2-3× speedswyx .ai
Checking sign-in…
Loading comments…