Qwen4 Max is callable now with 1M tokens of Context and context windowContext is the information available for a generation; the context window is the capacity available to hold it.Full definition → at stated prices. Requests must stream and thinking tokens bill as output, which affects cost planning for whole-repo coding tasks.
Key takeaways · AI-distilled
Together AI sent Qwen4 Max all 344 files of the Tornado repository (652,519 tokens) and a symptom-only bug report, with no tools or RetrievalSelecting evidence relevant to the current request.Full definition →. In 72 seconds it returned a patch that passed both regression tests the maintainers wrote for that bug. Together calls it one example.
Qwen4 Max traced the bug to WebSocketProtocol13.write_message, which wraps each write in a task whose failure nobody has to collect. Its fix marks that exception as retrieved, the same approach BaseIOStream.write takes in tornado/iostream.py, a file the bug report never named.
In Together's test, repeating a roughly 630,000-token request came back almost entirely cached: the first token arrived in 8 seconds instead of 54, and input cost about 3 cents instead of 66. Together says caching is best effort, so not every repeat is cached.
On Together AI, Qwen4 Max accepts streamingSending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.Full definition → requests only (a non-streaming call returns a 400 streaming_required error). Thinking is on by default and thinking tokens are billed as output; reasoning={"enabled": False} turns it off.
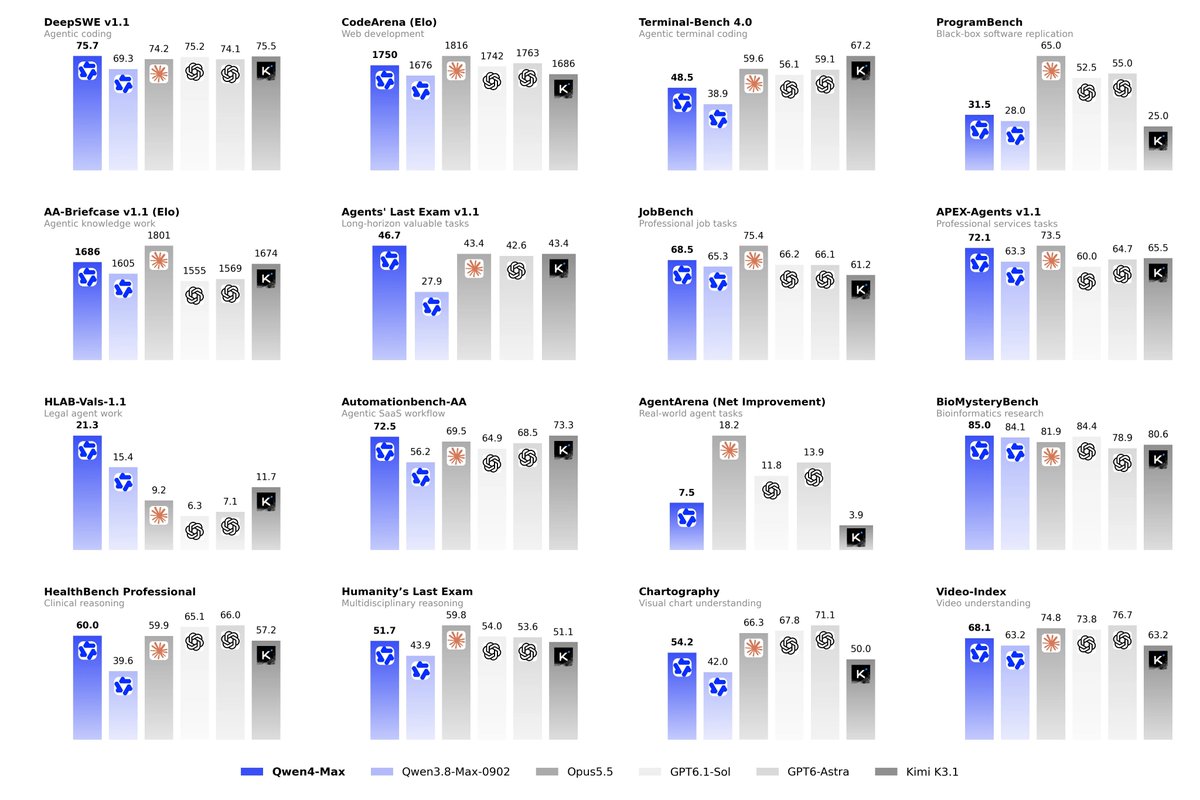
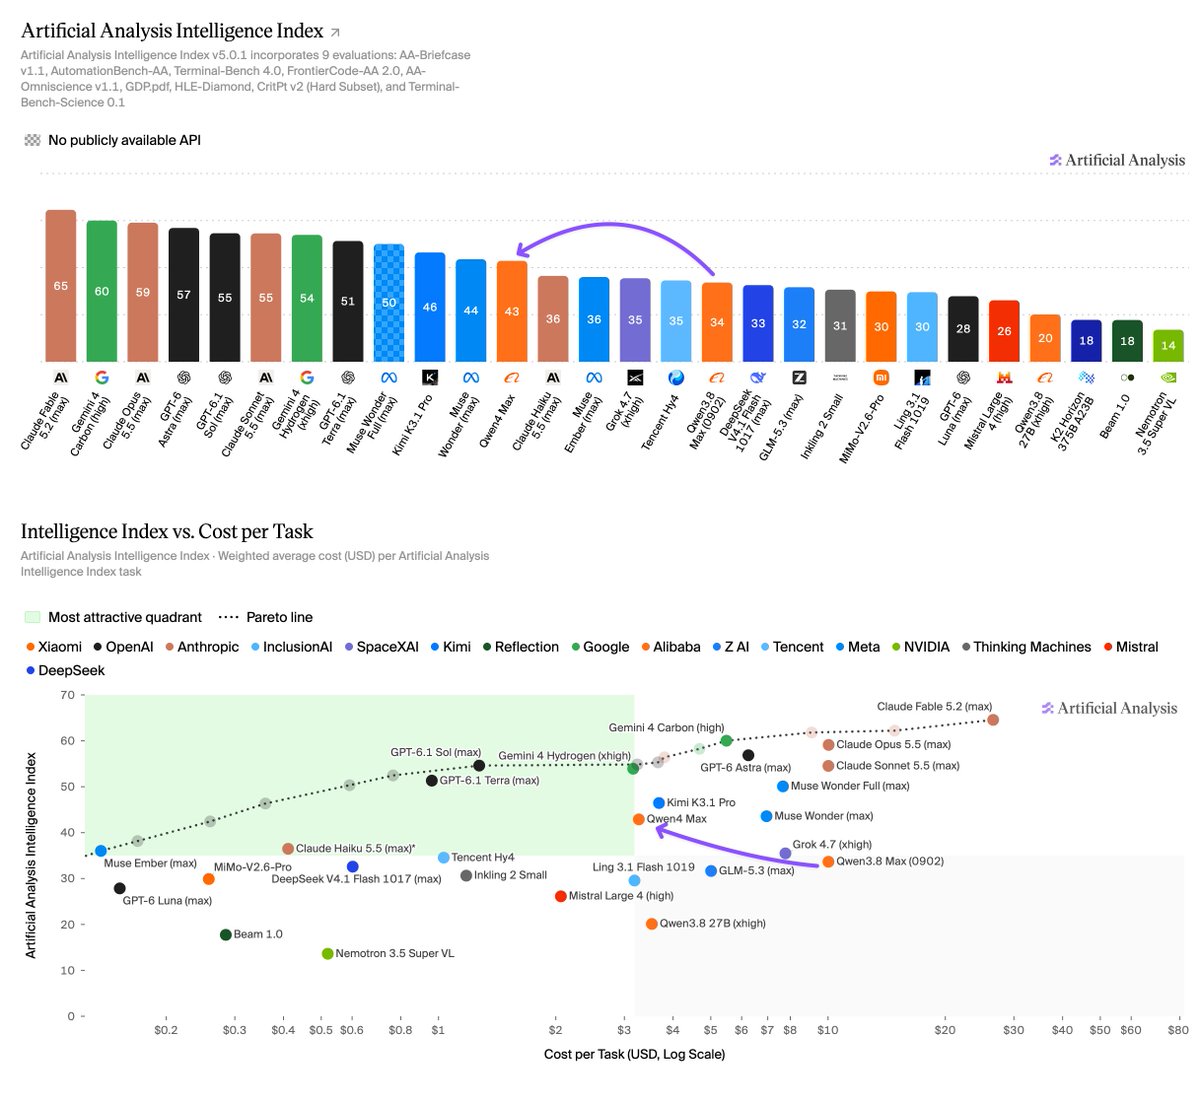
Alibaba describes Qwen4 Max as a sparse mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → model with 2.4T total and 71B active parameters. On its own Work360 benchmark, Alibaba reports it beats Qwen3.8 Max overall while using 35% fewer tokens at high effort and costing about 60% less per task.
Terms in this piece · Glossary
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
Context and context window — Context is the information available for a generation; the context window is the capacity available to hold it.
Retrieval — Selecting evidence relevant to the current request.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.