vLLM on Rubin NVL72 reports 6.5x perf per TCO over GB300
- Source
- x.com
- Date

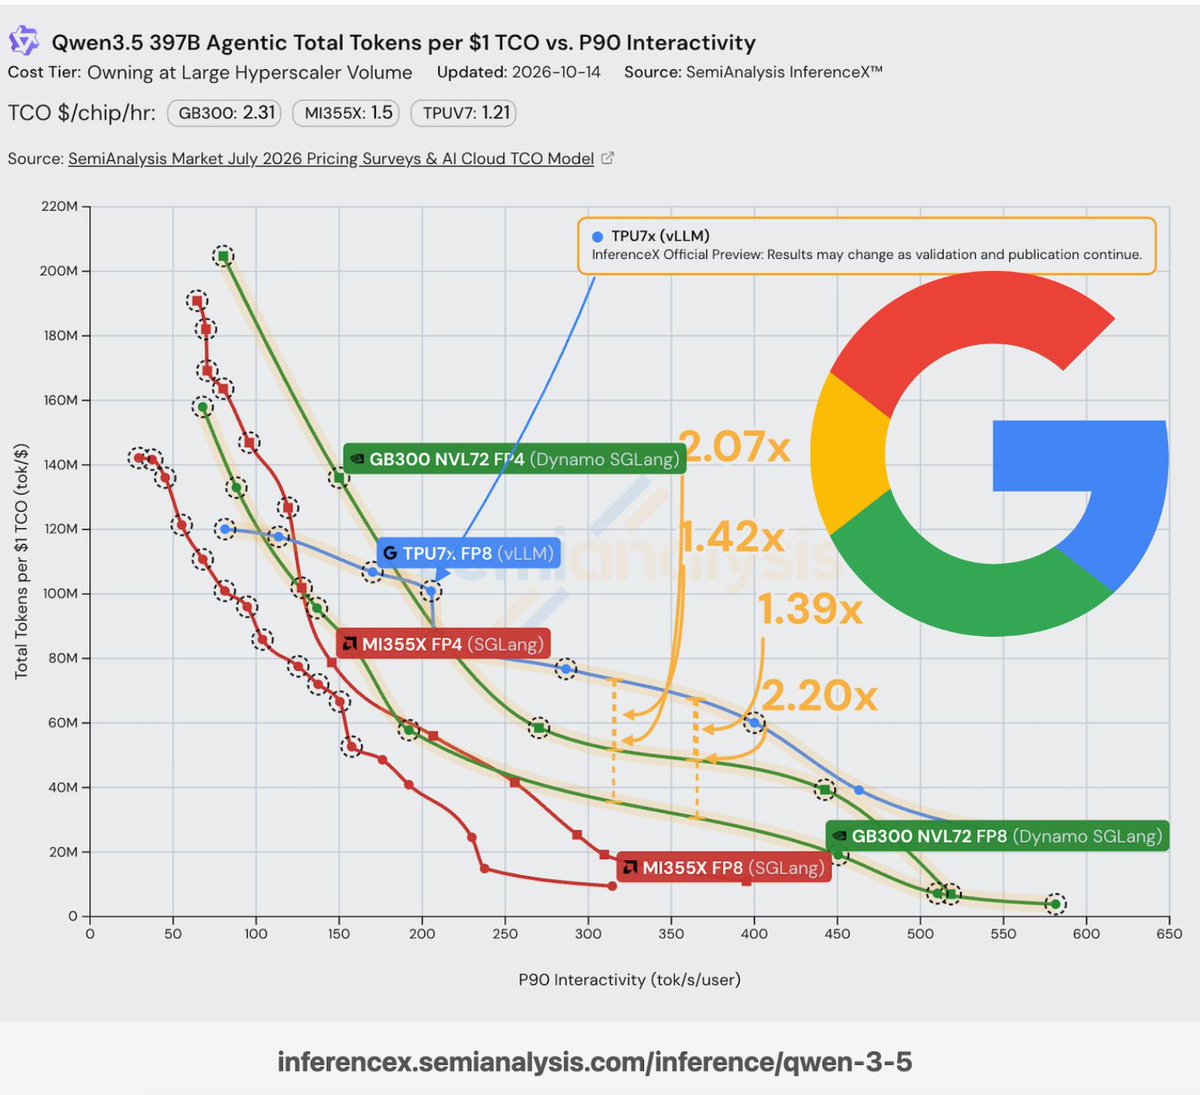
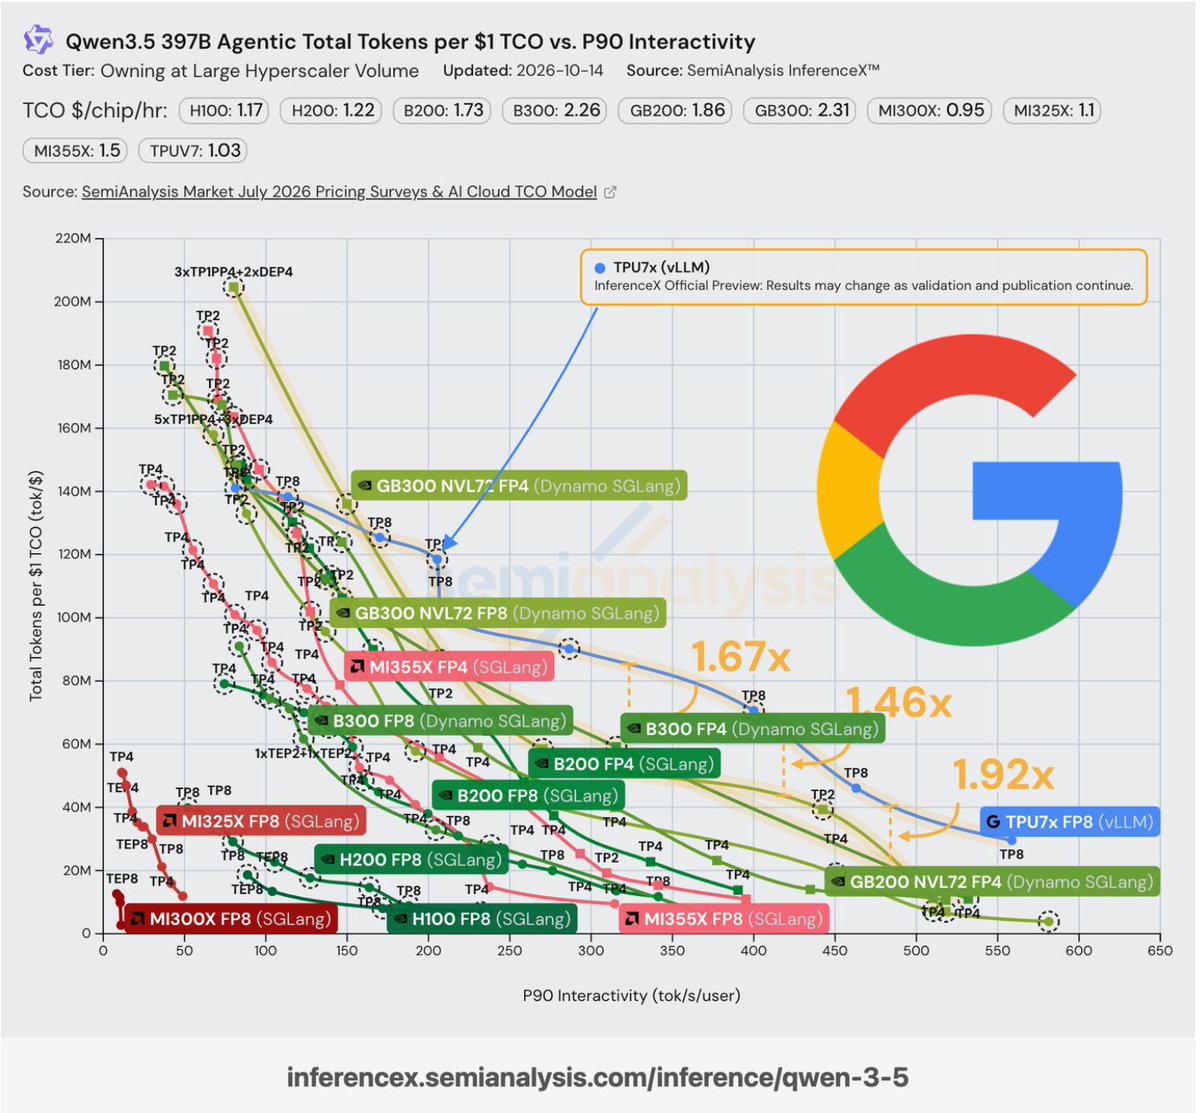
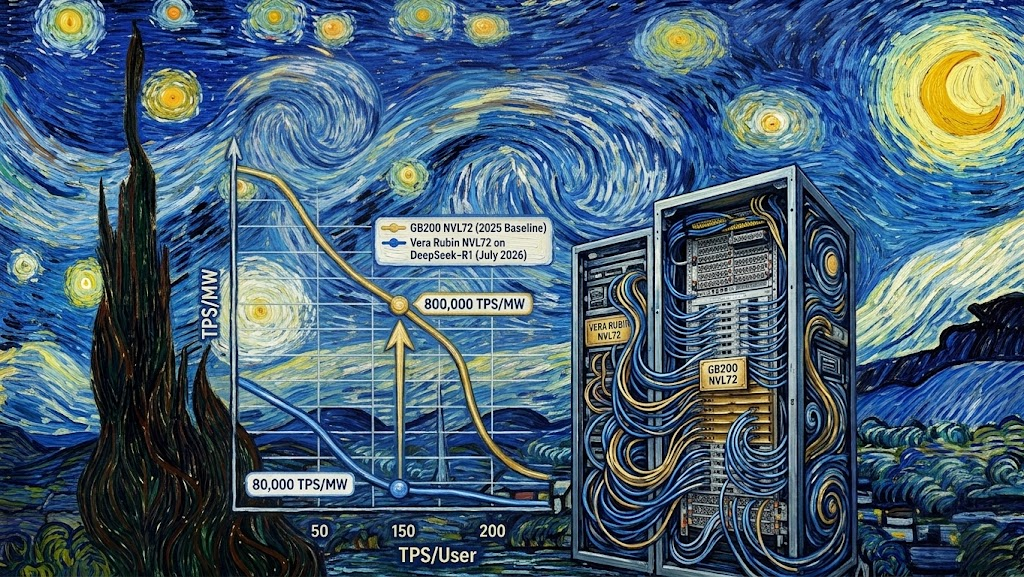
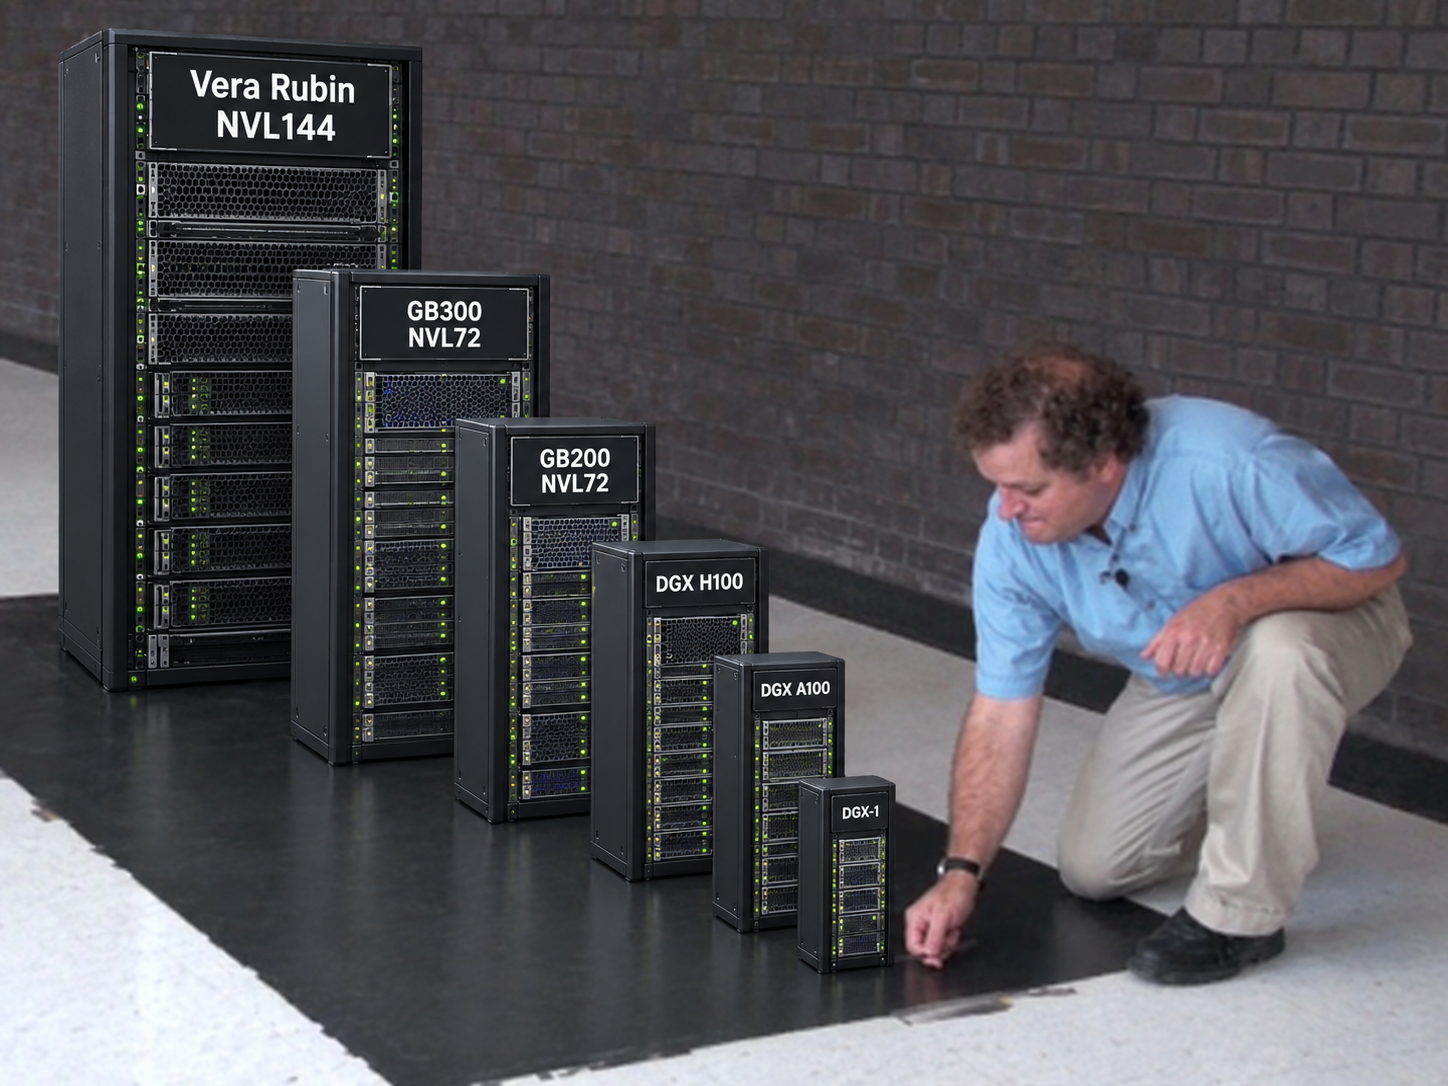
BREAKING NEWS: Less than 3 weeks since the MiniMax M3.1 Flash launch, NVIDIA and @Inferact have already submitted an initial vLLM Rubin NVL72 submission that is state-of-the-art and delivers 6.5x better perf per TCO than GB300 NVL72. Great to see that Rubin is already becoming more and more mature and integrated in partnership with @vllm_project! This Rubin submission uses the new locality-aware MoE feature in CUDA 13.4, which reduces latency and increases realized HBM bandwidth by ~1.2x.

cost on next-generation hardware may drop sharply: a reported 6.5x perf per TCO gain for Rubin NVL72 over GB300 on a model with vLLM. It affects future pricing and availability, but the submission details were not read.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…