Qwen Ships Audio 3.1 Stack With Cheaper ASR, TTS, and Realtime Models
- Source
- Qwen
- Date

⚡ Meet Qwen-Audio-3.1! ASR, TTS & Realtime are fully upgraded, joined by two new models: TTS-Next for audio creation and ASR-Next for audio understanding. Five models, one complete audio stack: understanding, generation, interaction & creation. Plus big price cuts across the lineup: TTS ~70% off, Realtime ~85% off, and ASR up to 95% off. Highlights: 🥳 - ASR: stronger multilingual & dialect recognition, plus native polishing that auto-removes fillers & repetitions for cleaner, more logical transcripts. - ASR-Next: supports multi-speaker ASR with speaker labels, timestamps & aligned transcripts, and understands emotions, ambient & machine sounds for sound captioning, event localization, audio QA & reasoning. - TTS: multilingual & dialect synthesis with natural cross-lingual voice transfer; control emotion, speed & style via simple instructions. - TTS-Next: unified LM + diffusion framework generating voice, sound effects & background audio in one pass for audiobooks, podcasts, games & ads. - Realtime: speak & listen at once with anytime interruption, just like a real call; it even slows down and responds empathetically when it senses a low mood. Unlock the full potential of…
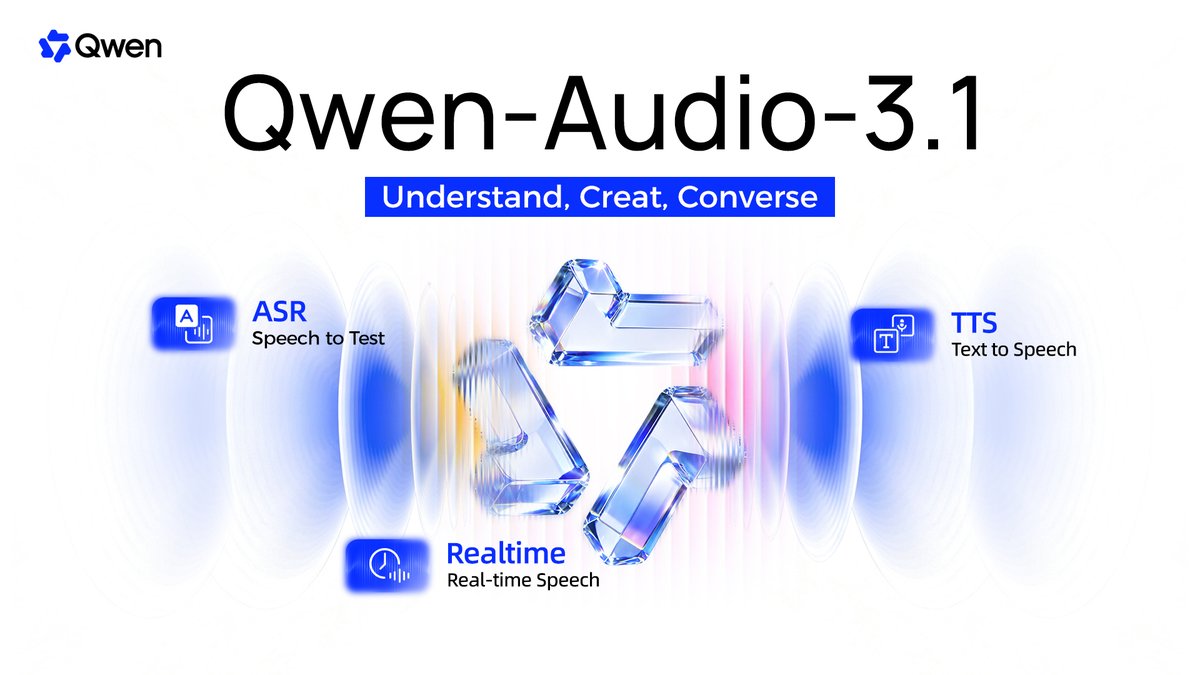
- Qwen-Audio-3.1 is a five-model stack: upgraded ASR, TTS and Realtime, plus new ASR-Next for audio understanding and TTS-Next for audio creation, with price cuts Qwen puts at about 70% for TTS, 85% for Realtime and up to 95% for ASR.
- ASR-Next adds multi-speaker transcription with speaker labels, timestamps and aligned transcripts, and handles emotion, ambient and machine sounds for sound captioning, event localization and audio QA; standard ASR can strip fillers and repetitions.
- TTS-Next uses a unified plus diffusion framework to generate voice, sound effects and background audio in one pass; standard TTS supports cross-lingual voice transfer and instruction control of emotion, speed and style.
- Qwen says the Realtime model can speak and listen at once with interruption at any time, and slows down and responds empathetically when it senses a low mood.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
Cuts the cost of building voice agents and audio pipelines significantly while adding speaker-labeled transcription and single-pass voice-plus-sound-effects generation.
Checking sign-in…
Loading comments…