Zhipu's SAO training method beats GRPO on SWE-Bench and IMO tasks
- Source
- x.com
- Date

Our Single-rollout Asynchronous Optimization (SAO), is able to train stably for one thousand steps and consistently outperform GRPO and its variants on agentic coding and reasoning benchmarks, such as SWE-Bench Verified, BeyondAIME, and IMOAnswerBench. https://t.co/oca1DvDvdB
Context
Zhipu researcher Jie Tang says a new reinforcement learning method called Single-rollout Asynchronous Optimization, or SAO, trains more stably and scores higher than GRPO, the group-based method most reasoning models use during post-training. GRPO samples several attempts at a task and compares them against each other to decide what to reinforce; in asynchronous training setups that comparison breaks down once parallel workers drift out of sync, and GRPO can collapse after only a few hundred steps. A paper describing SAO removes the group comparison entirely, updating on a single rollout per task instead, which the authors say lets training run stably past a thousand steps.
On the coding , the paper reports SAO reaching 29.8 percent accuracy against 27.0 percent for GRPO and 23.0 percent for the untrained base model, with a similar pattern on the BeyondAIME and IMOAnswerBench reasoning tests that Tang's post mentions. Those are measured results from Zhipu's own paper rather than independent replication, and the margin over GRPO, while consistent, is modest rather than a wholesale leap. Tang cofounded Z.ai (formerly Zhipu AI), and outside reporting ties SAO to the reinforcement-learning infrastructure the company later used for GLM-5.2.
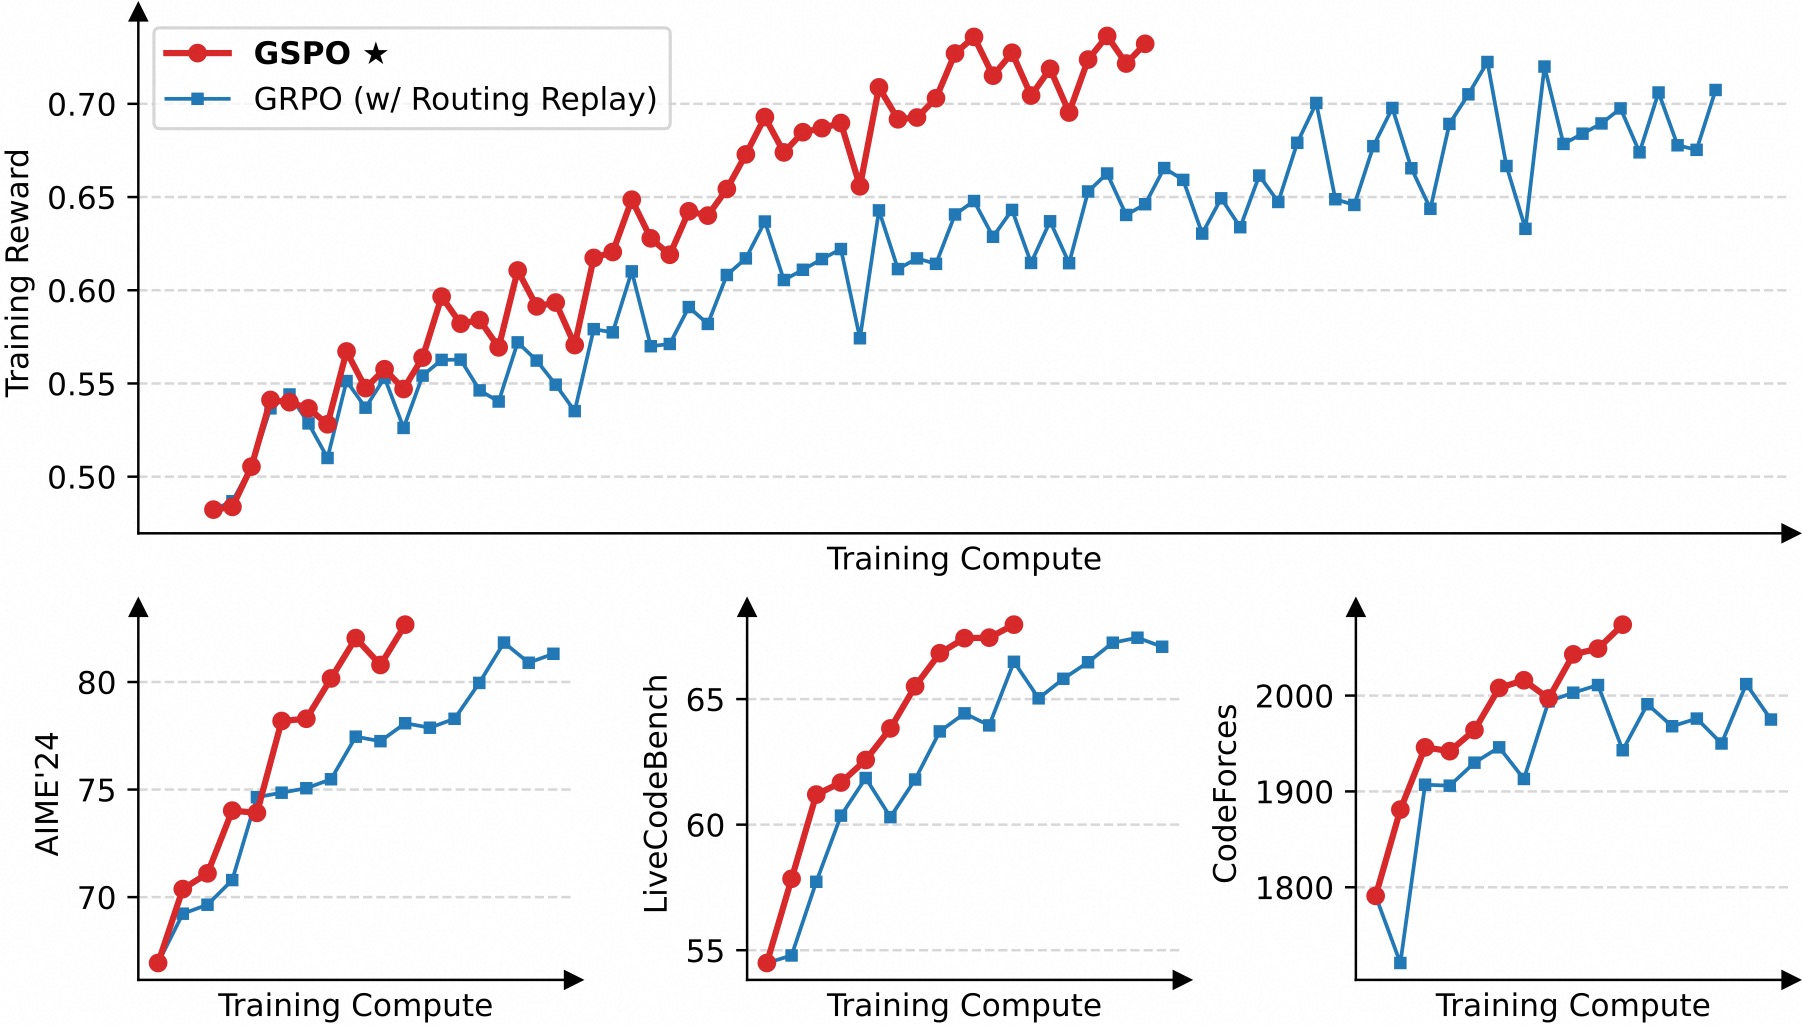 articleGSPO: Towards Scalable Reinforcement Learning for Language ModelsQwen Team
- postSDPO Trains Models With Natural-Language Feedback Instead of Scalar RewardsStanford AI Lab
 articleSPROUT: Scaling Agentic Reinforcement Learning for Long-Horizon Software EngineeringMengyang Liu, Weiming Wang, Haixin Nan, Yu Wu, Peize Li, Shihong Huang, Xuning He, Xue Jiang, Yihong Dong
Checking sign-in…
Loading comments…