inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Why it matters
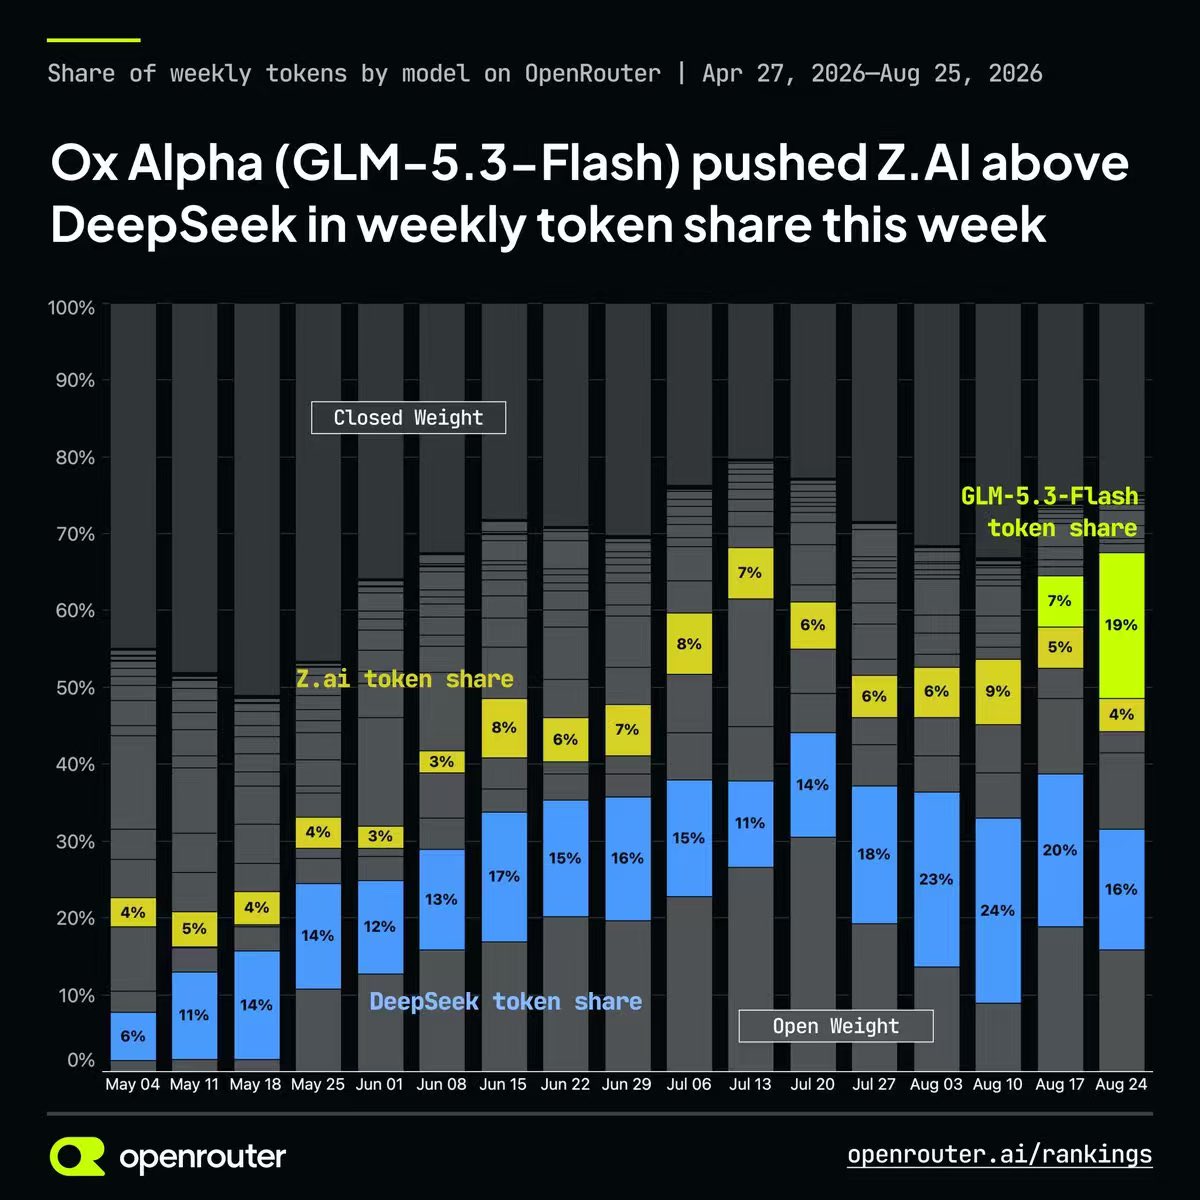
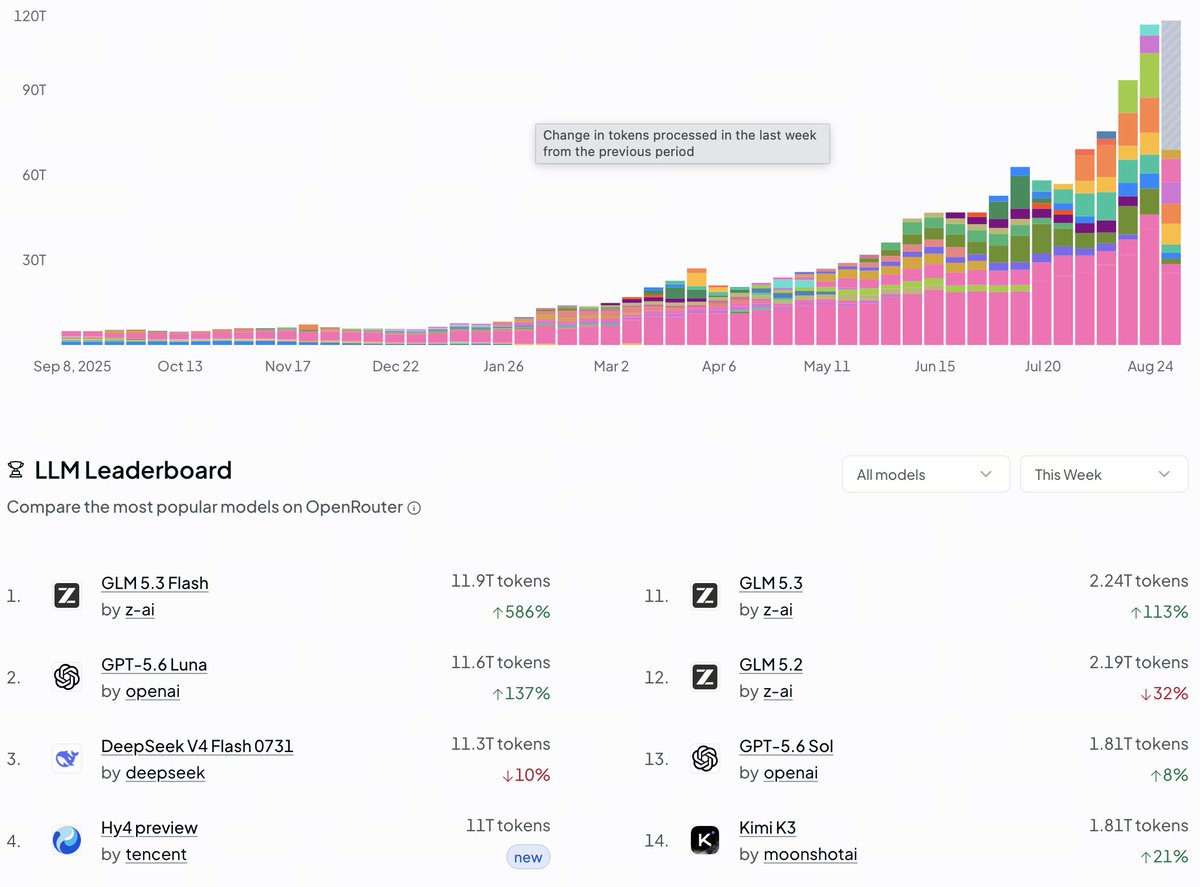
GLM-5.2 inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → speed climbed from 280 to 318 and reportedly 392 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per second as providers compete on serving optimization, showing real throughput headroom for engineers choosing a provider.