Step 5 Preview ties Kimi K3 at 2.8x lower cost, lags on agentic evals
- Source
- x.com
- Date

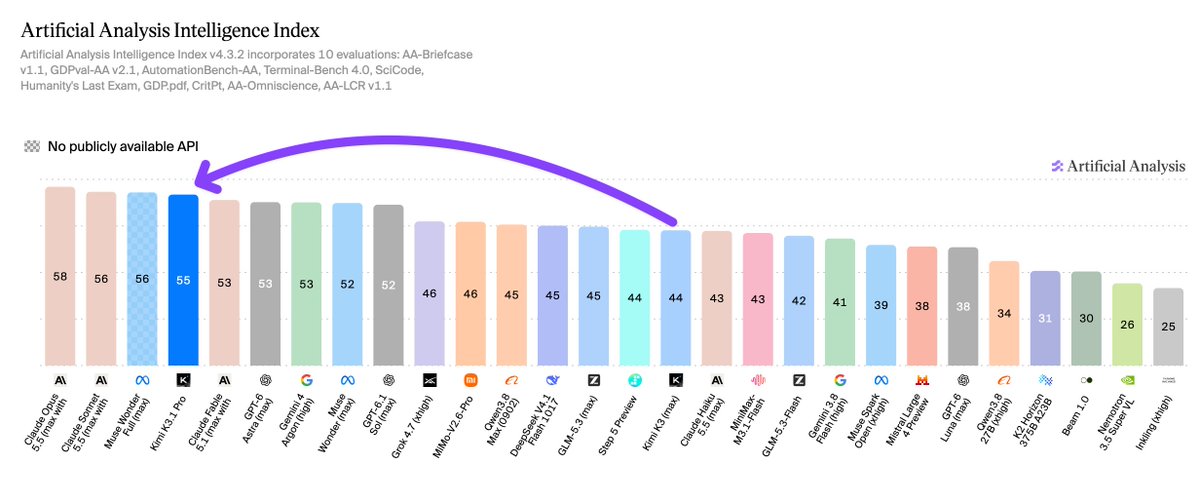
StepFun's Step 5 Preview scores 44 on the Artificial Analysis Intelligence Index, matching Kimi K3 (max) at ~2.8x lower cost per task, but trails peers on agentic evaluations Step 5 Preview is @StepFun_ai's new flagship model, with 600B total and 27B active parameters, succeeding Step 3.7 Flash (released May 2026). It scores 44 on the Intelligence Index, level with Kimi K3 (max) and just behind GLM-5.3 (max, 45) and Qwen3.8 Max (45) Key takeaways: ➤ Step 5 Preview costs ~2.8x less per Intelligence Index task than models at the same score. It costs ~$0.72 per task, against ~$2.00 for Kimi K3 (max) at the same score of 44 and ~$2.01 for GLM-5.3 (max) at 45. This is driven by pricing: at $1/$2.70 per 1M input/output tokens, it is priced below both on input and output. MiMo-V2.6-Pro is the one model that scores higher (46) at a lower cost per task ($0.13) ➤ Frontier reasoning is the standout strength, and where the jump from Step 3.7 Flash is largest. Step 5 Preview scores 46% on Humanity's Last Exam, in line with Kimi K3 (max, 47%), and 21% on CritPt, between Kimi K3 (23%) and GLM-5.3 (max, 19%). Both are up sharply from Step 3.7 Flash: +25 points on HLE and +19 points on CritPt…

Context
StepFun's new flagship, Step 5 Preview, scores 44 on Artificial Analysis's Intelligence Index, the same as Moonshot AI's Kimi K3 at its max setting and one point behind Z.ai's GLM-5.3 and Qwen3.8 Max, according to the firm's evaluation. It reaches that score for about $0.72 per index task, against about $2.00 for Kimi K3 and $2.01 for GLM-5.3, which is where the figure of roughly 2.8 times cheaper comes from. Artificial Analysis attributes the gap to pricing: at $1 per million input and $2.70 per million output tokens, Step 5 Preview is priced below both models on input and on output.
The tied score covers two different profiles. Step 5 Preview's strength is hard reasoning questions. It scored 46% on Humanity's Last Exam, close to Kimi K3's 47%, and 21% on CritPt, between Kimi K3 at 23% and GLM-5.3 at 19%, gains of 25 and 19 points over its predecessor, Step 3.7 Flash. On agentic evaluations, where a model carries out multi-step work on its own, it trails models with similar overall scores. Its 1,566 Elo on GDPval-AA, which Artificial Analysis calls its primary of agentic performance, sits behind Qwen3.8 Max at 1,668 and GLM-5.3 at 1,646, and it is also behind both on Terminal-Bench 4.0 (33% against 39% and 42%), AA-Briefcase and AutomationBench-AA.
The lower cost per task is real on Artificial Analysis's index, but it buys a model that is stronger at reasoning than at work, so the agentic gaps matter more than the price for anyone building agents. Nor is it the cheapest model at this level: Artificial Analysis notes that Xiaomi's MiMo-V2.6-Pro scores higher, 46, at $0.13 per task, a result covered separately. Step 5 Preview has 600 billion parameters, 27 billion of them active for each token, a 1 million token , and accepts text, image and video input. At the time of the evaluation it was available only through StepFun's own API with closed weights, with an open-weights release planned for October 15.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…