Nemotron 3.5 Lightning was released with native support for MTP, DFlash and DSpa
- Source
- x.com
- Date

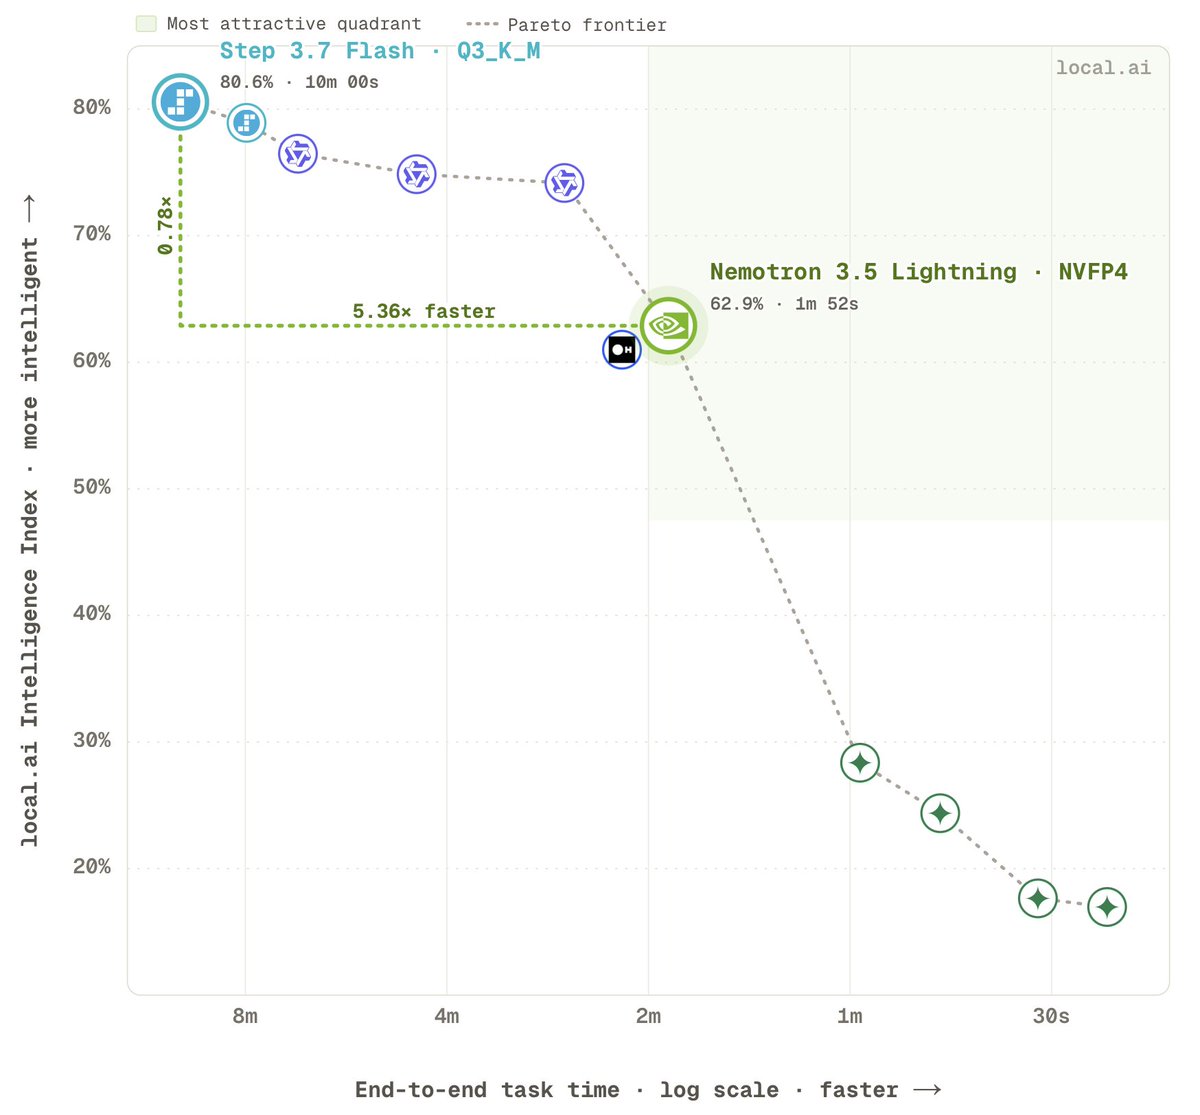
We worked with @nvidia to understand how Nemotron 3.5 Lightning performs locally on the DGX Spark. We ran the same set of 884 agent tasks on 100 unique models and compared them on Intelligence and Speed. Here's what we found 👇 (Full results on https://t.co/b6s9nCUDko) https://t.co/RD0jmQJR8C

Nemotron 3.5 Lightning was released with native support for MTP, DFlash and DSpark. We recommend DSpark on DGX Spark. Here is the full vLLM configuration for DGX Spark with DSpark so you can run it yourself: vllm serve \ nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 \ --served-model-name nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 \ --trust-remote-code \ --moe-backend marlin \ --kv-cache-dtype fp8 \ --max-model-len 262144 \ --max-num-batched-tokens 16384 \ --quantization modelopt_fp4 \ --mamba-backend flashinfer \ --mamba-ssm-cache-dtype float16 \ --enable-mamba-cache-stochastic-rounding \ --mamba-cache-philox-rounds 5 \ --enable-prefix-caching \ --mamba-cache-mode align \ --speculative-config '{ "model": "nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4-DSpark", "method": "dspark", "num_speculative_tokens": 7 }' vllm image: vllm/vllm-openai:nightly-7794b1e08bf505ff28664515ffaaeeec955ab796
Context
A later post in Alex Cheema's DGX Spark thread turns his benchmark into a recipe: the full command for serving NVIDIA's Nemotron 3.5 Lightning on the machine with vLLM, an open-source model-serving engine (post). Cheema says Lightning was released with native support for MTP, DFlash and DSpark, and recommends DSpark on the DGX Spark. In the command, DSpark is set up as : a separate checkpoint, NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4-DSpark, runs alongside the main model and is set to propose seven tokens at a time. NVIDIA's later explainer describes speculative decoding as a small draft model proposing several tokens that the larger model verifies in parallel, which cuts the number of decoding steps while preserving output accuracy, and it compares MTP, DFlash and DSpark among the ways of producing those drafts.
The rest of the command fixes the details someone would need to reproduce the setup. Both checkpoints are NVFP4 builds, a 4-bit format, loaded with the modelopt_fp4 setting; the cache of earlier tokens is stored in fp8; the limit is 262,144 tokens; and prefix caching is on. The command names a specific nightly build of the vLLM container rather than a release, so following the recipe means using that build.
The post gives no separate speed figures for DSpark, MTP or DFlash, and the thread does not say outright that its timed runs used this exact configuration. Its speed results are in the comparison with Step 3.7 Flash and the comparison with Qwen 3.6 35B A3B.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…