Will We Run Out Of Data Limits Of Llm Scaling Based On Human Generated Data
Source
epoch.ai
Author
Epoch AI publications
Date
Why it matters
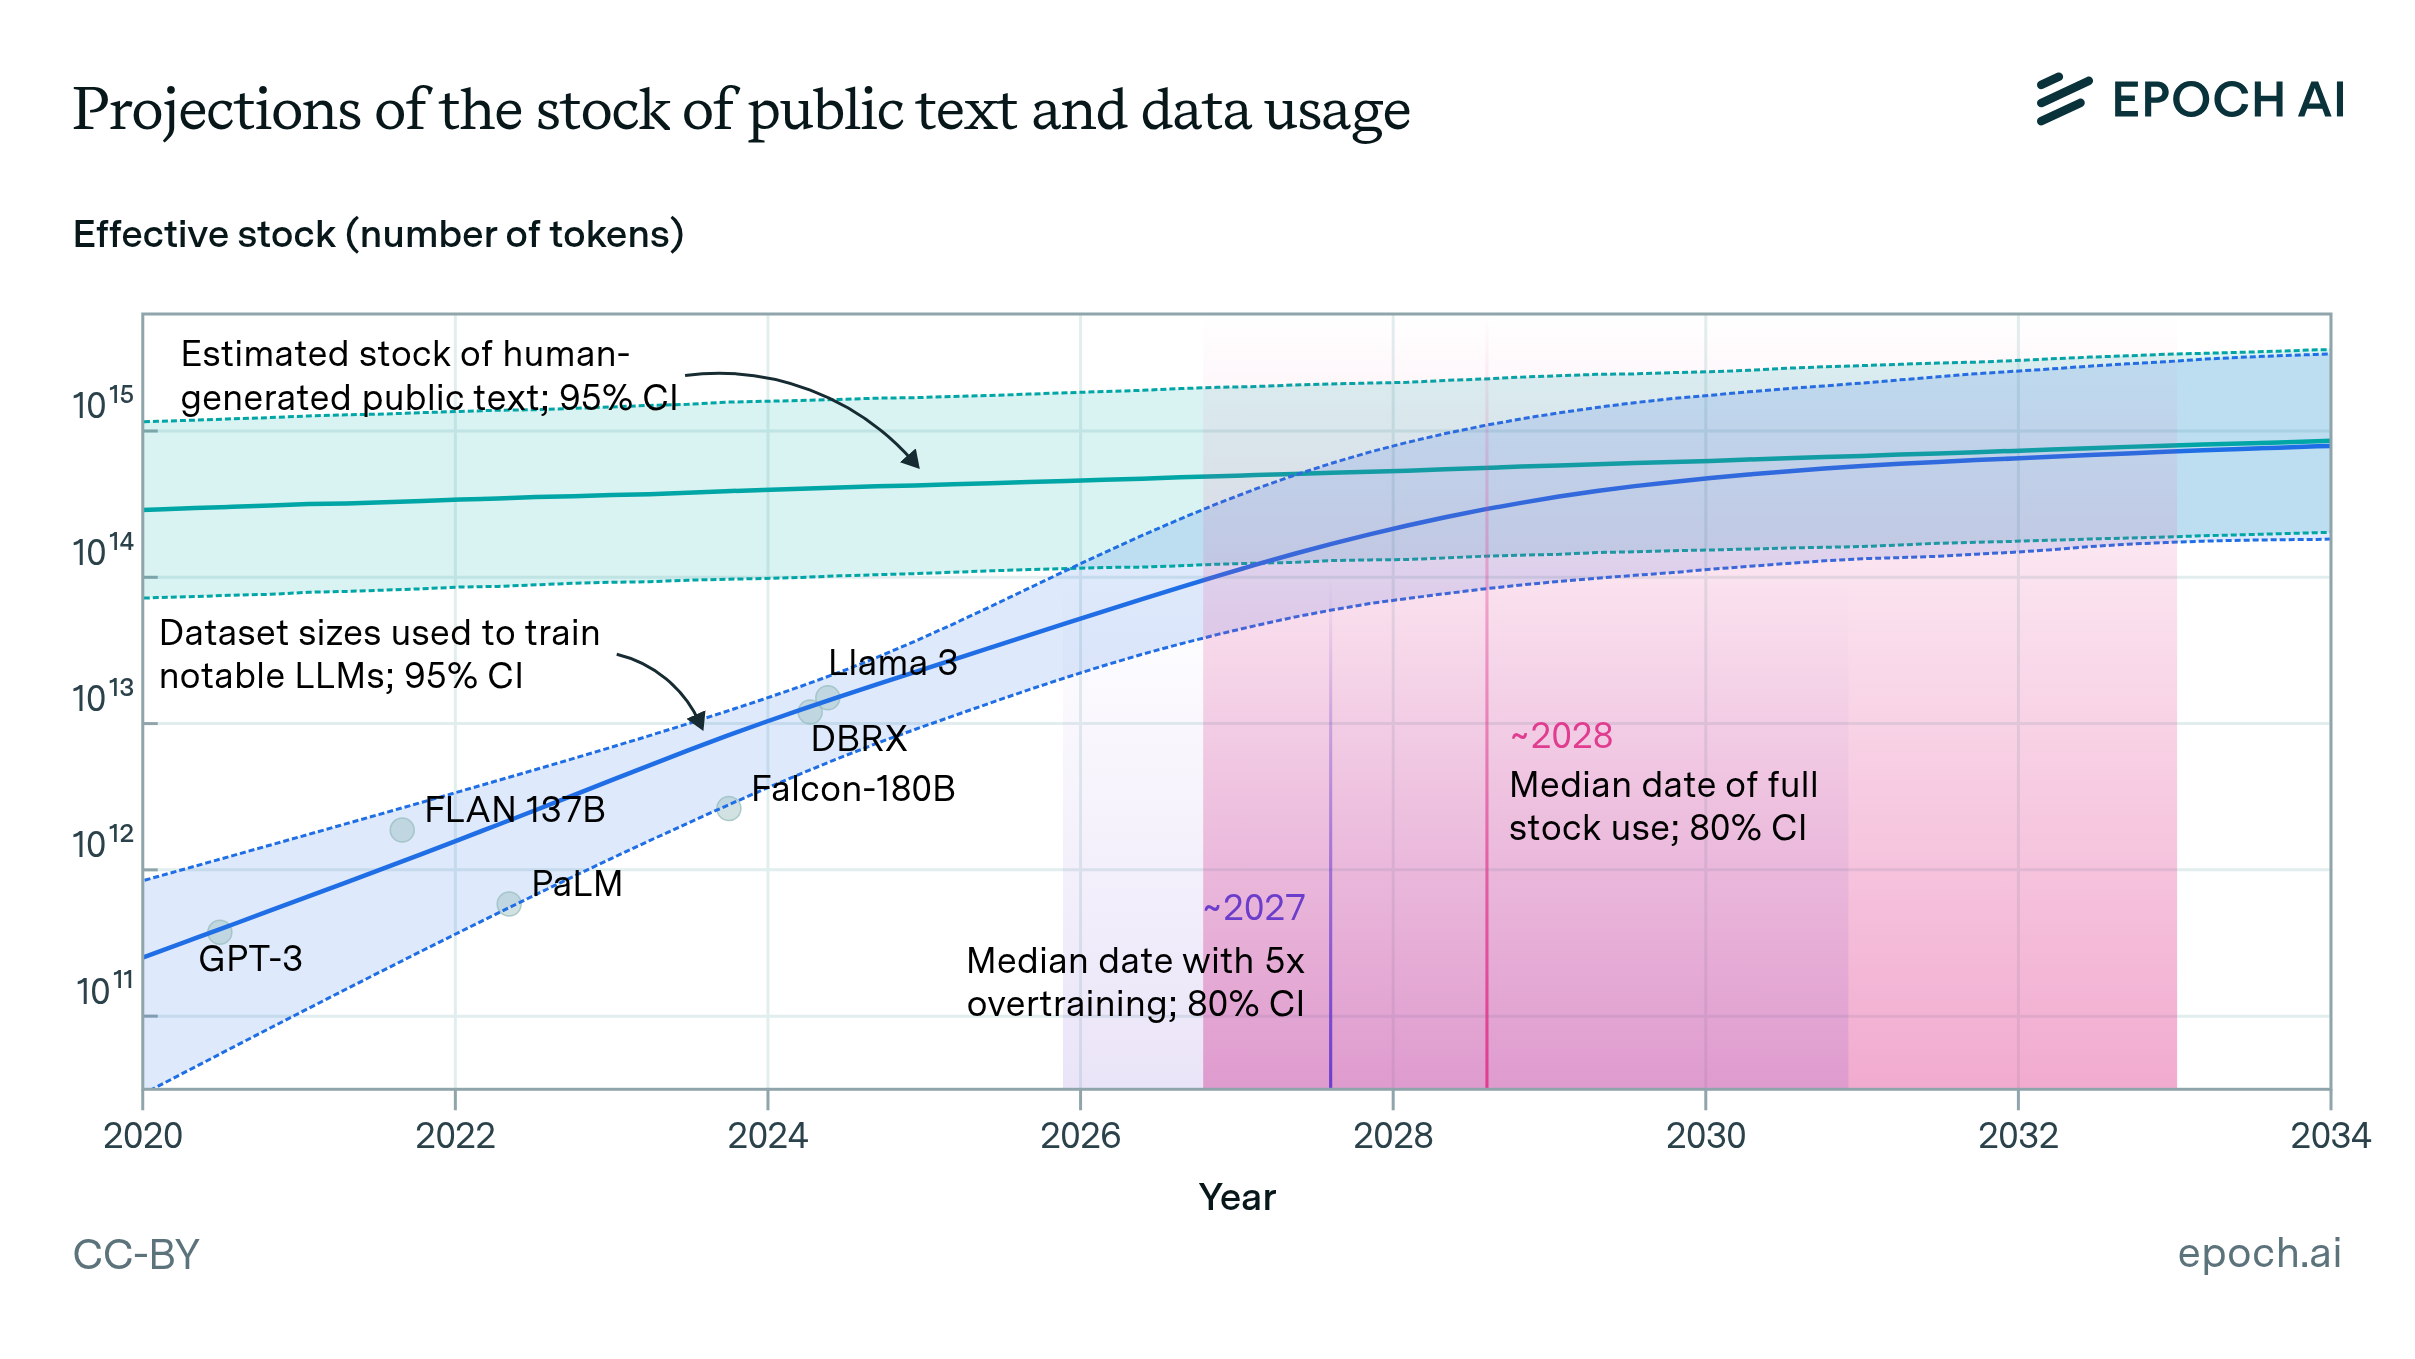
Puts a number on the human text supply (about 300T tokens) and a window for its exhaustion, explaining why synthetic data and data efficiency matter for future model capability.
Key takeaways · AI-distilled
If models are trained compute-optimally, about 20 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per parameter, Epoch finds enough public human text for a training run of about 5e28 FLOP, a scale it expects to be reached in 2028.
Overtraining pulls that date forward. Epoch's profit model finds labs may overtrain models up to 100x for cheaper inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition →: at 5x overtraining the data stock runs out by 2027, at 100x by 2025. Llama 3-70B was overtrained about 10x.
The estimate grew from about 10T tokens in Epoch's 2022 paper because carefully filtered web data proved able to outperform curated corpora (a 5x increase) and multi-epoch training added another 2-5x, moving the projected exhaustion from 2024 to around 2028.
Exhausting public text need not halt progress: models can grow parameters on a fixed dataset (undertraining), worth up to two orders of magnitude of compute-optimal scaling before a plateau. Epoch names synthetic data, other modalities and data efficiency as the bets beyond 2030.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.