Knowing the Form, Not the Function: Automatically Auditing Answer–Authority Decoupling in Legal Benchmarks
Source
Hsien-Jyh Liao
Author
Hsien-Jyh Liao
Date
Key takeaways · AI-distilled
On 238 Taiwan bar-exam items with verified governing provisions, answer correctness and authority groundingTying a model's answers to checkable sources — retrieved documents, live data, tool results — instead of letting it answer from memory alone.Full definition → dissociate both ways: 24-42% of criminal-law responses were correct but missed the gold statute, while 15-22% were wrong yet cited it.
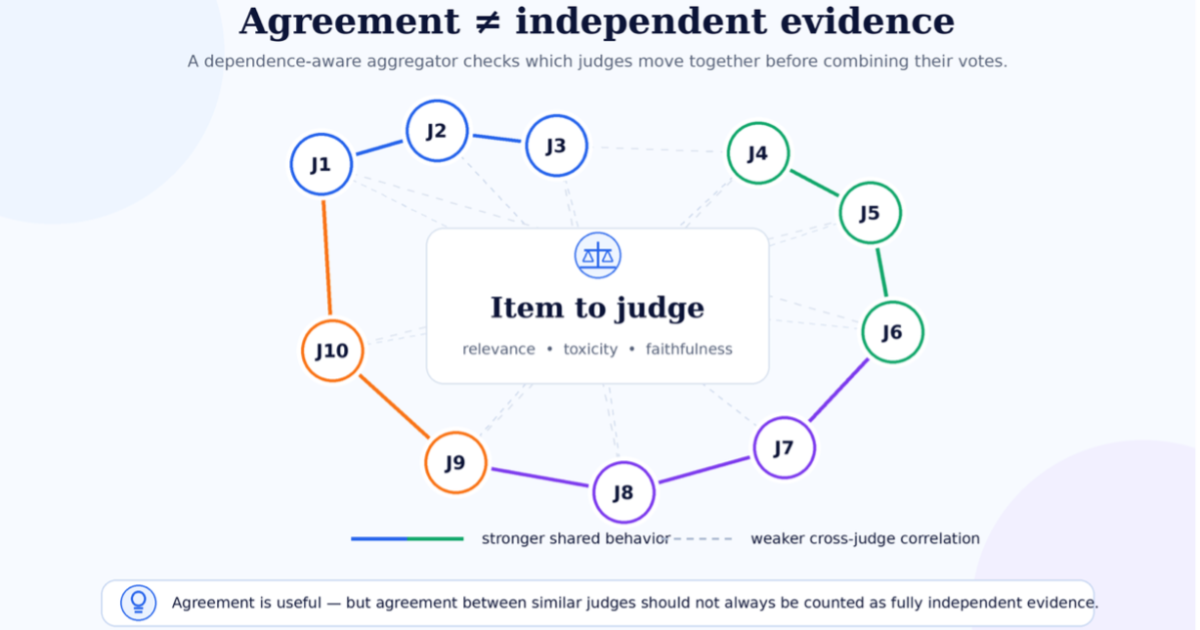
Models spontaneously emit authority markers under ordinary prompts that never requested citations - which is what makes the mismatch automatically auditable at scale.
Answer-only scoring counts naturally occurring authority misses as full benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → successes; the authors propose joint answer-authority evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → for statute-grounded legal benchmarks.
Terms in this piece · Glossary
grounding — Tying a model's answers to checkable sources — retrieved documents, live data, tool results — instead of letting it answer from memory alone.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
RAG — Retrieval-augmented generation — fetching relevant documents first and pasting them into the model's context so it answers from your data instead of memory.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
The paper shows answer-only scoring on legal benchmarks masks a real failure mode — correct outputs with fabricated or missing statutory grounding — and proposes a joint answer-and-authority evaluation method that's applicable to any domain where citation grounding matters (RAGRetrieval-augmented generation — fetching relevant documents first and pasting them into the model's context so it answers from your data instead of memory.Full definition →, legal AI, compliance).
Key quotes
“Legal benchmarks typically score final answers even when models also state legal authority.”
“The two dimensions dissociate in both directions.”
“We therefore propose joint answer--authority evaluation for statute-grounded legal benchmarks.”