Intel
Page 23
Crusoe CEO Chase Lochmiller: Turning Stranded Energy Into Intelligence
Crusoe CEO Chase Lochmiller explains why the company builds its own power plants and electrical equipment rather than buying capacity like a typical cloud provider.
Why it mattersCrusoe's vertically integrated model (power generation plus data centers plus AI cloud) is a specific bet on how AI compute capacity gets built, relevant to anyone tracking where GPU capacity and training power will come from.
open-webui v0.12.5
Open WebUI 0.12.5 adds an admin analytics Sessions tab showing per-chat tokens, errors, and tool-call timing.

How Revolut Cut AI Coding Costs 90% With Self-Hosted Open Models - David Abitbol, Revolut
Revolut's David Abitbol shares data across 2,000 engineers showing self-hosted open GLM models cut AI coding costs about 90% versus frontier APIs while delivering 60-70% faster lead times.
Why it mattersRevolut's self-hosted open GLM models delivered 60-70% faster coding throughput at about a tenth of frontier-API cost across 2,000 engineers, a concrete data point on when self-hosting beats paying frontier labs.

We Trust AI Agents That Break Every Day - Shy Ruparel, Temporal
Temporal's Shy Ruparel breaks down survey gaps between agent usage and production reliance, then demos durable execution keeping a financial payout workflow intact after workers are killed mid-task.
Why it mattersMost teams use agents daily but few run them in production; Temporal's demo shows durable execution keeping a payout workflow consistent through mid-flight worker kills, without repeating tool calls or re-spending tokens.
Zero click, silent, remote Android DoS
Writeup of a zero-click, zero-interaction Android telephony vulnerability: a malformed WAP Push SMS crashes com.android.phone via an unchecked integer cast, dropping active calls.
Why it mattersA single crafted SMS can silently kill telephony on an unpatched Android phone and drop active calls, including emergency calls.

Why a One-Line Change Can Break Your Whole Stack - Cole Gannaway, Qodo
Qodo's Cole Gannaway walks through how a one-line data-model change can pass every test yet quietly break downstream web, mobile, CLI and MCP clients.
Why it mattersShows how to surface the hidden blast radius of a seemingly safe code change across every client that depends on it, and argues review context belongs before code is written, not just at PR time.
js-genai v2.32.0
Google's js-genai 2.32.0 adds continuation_token and requires_continuation status, automatic_continuation in interactions.create, a video upscale task parameter.
Why it mattersThe Gemini JS SDK gains automatic continuation for interactions and video understanding support. Node and web developers on the Gemini API get the same long-running call handling as the Python SDK.
python-genai v2.34.0
Google's python-genai 2.34.0 adds continuation_token handling, automatic_continuation in interactions.create, a video upscale parameter.
Why it mattersThe Gemini Python SDK now supports automatic continuation for interactions and video understanding, and drops Python 3.10. Pin your runtime and check long-running calls before upgrading.

Ryo Lu draws on Engelbart, Licklider and Smalltalk to argue AI building tools should deepen user understanding, with comprehensible, reshapeable and reversible systems, rather than only maximizing automated output.
Why it mattersArgues that AI software tools should let users ask why something works, change one part, undo it and learn to make the next change themselves. This gives builders a design criterion beyond output volume.
opencode v2.2.1
opencode v2.2.1 adds /goal for objective-driven sessions with reviewer confirmation, an experimental image_generate tool, live background-shell inspection and a redesigned model picker.
Why it mattersThe /goal command lets sessions keep working until a reviewer confirms the objective is met. Direct importers of the AI package must also handle the removed image providers.
Claude Code regularly sends each background agent’s transcript to its model
A third-party gist reports Claude Code re-sends each background agent's transcript about every 30 seconds to fill a status line.
Why it mattersIf the claim holds, background agents carry hidden recurring token cost from status summaries. The gist explains the mechanism and an unofficial preload to disable it, which affects cost control for multi-agent sessions.
Sakana opens enterprise API platform early access
Sakana AI opens early access to its enterprise API Platform with OpenAI-compatible endpoints, workspace and role-based access control, audit logs and budget limits.
Why it mattersFugu, an orchestration model that composes multiple frontier models, becomes callable through an OpenAI-compatible endpoint, so existing clients only need a new base URL.
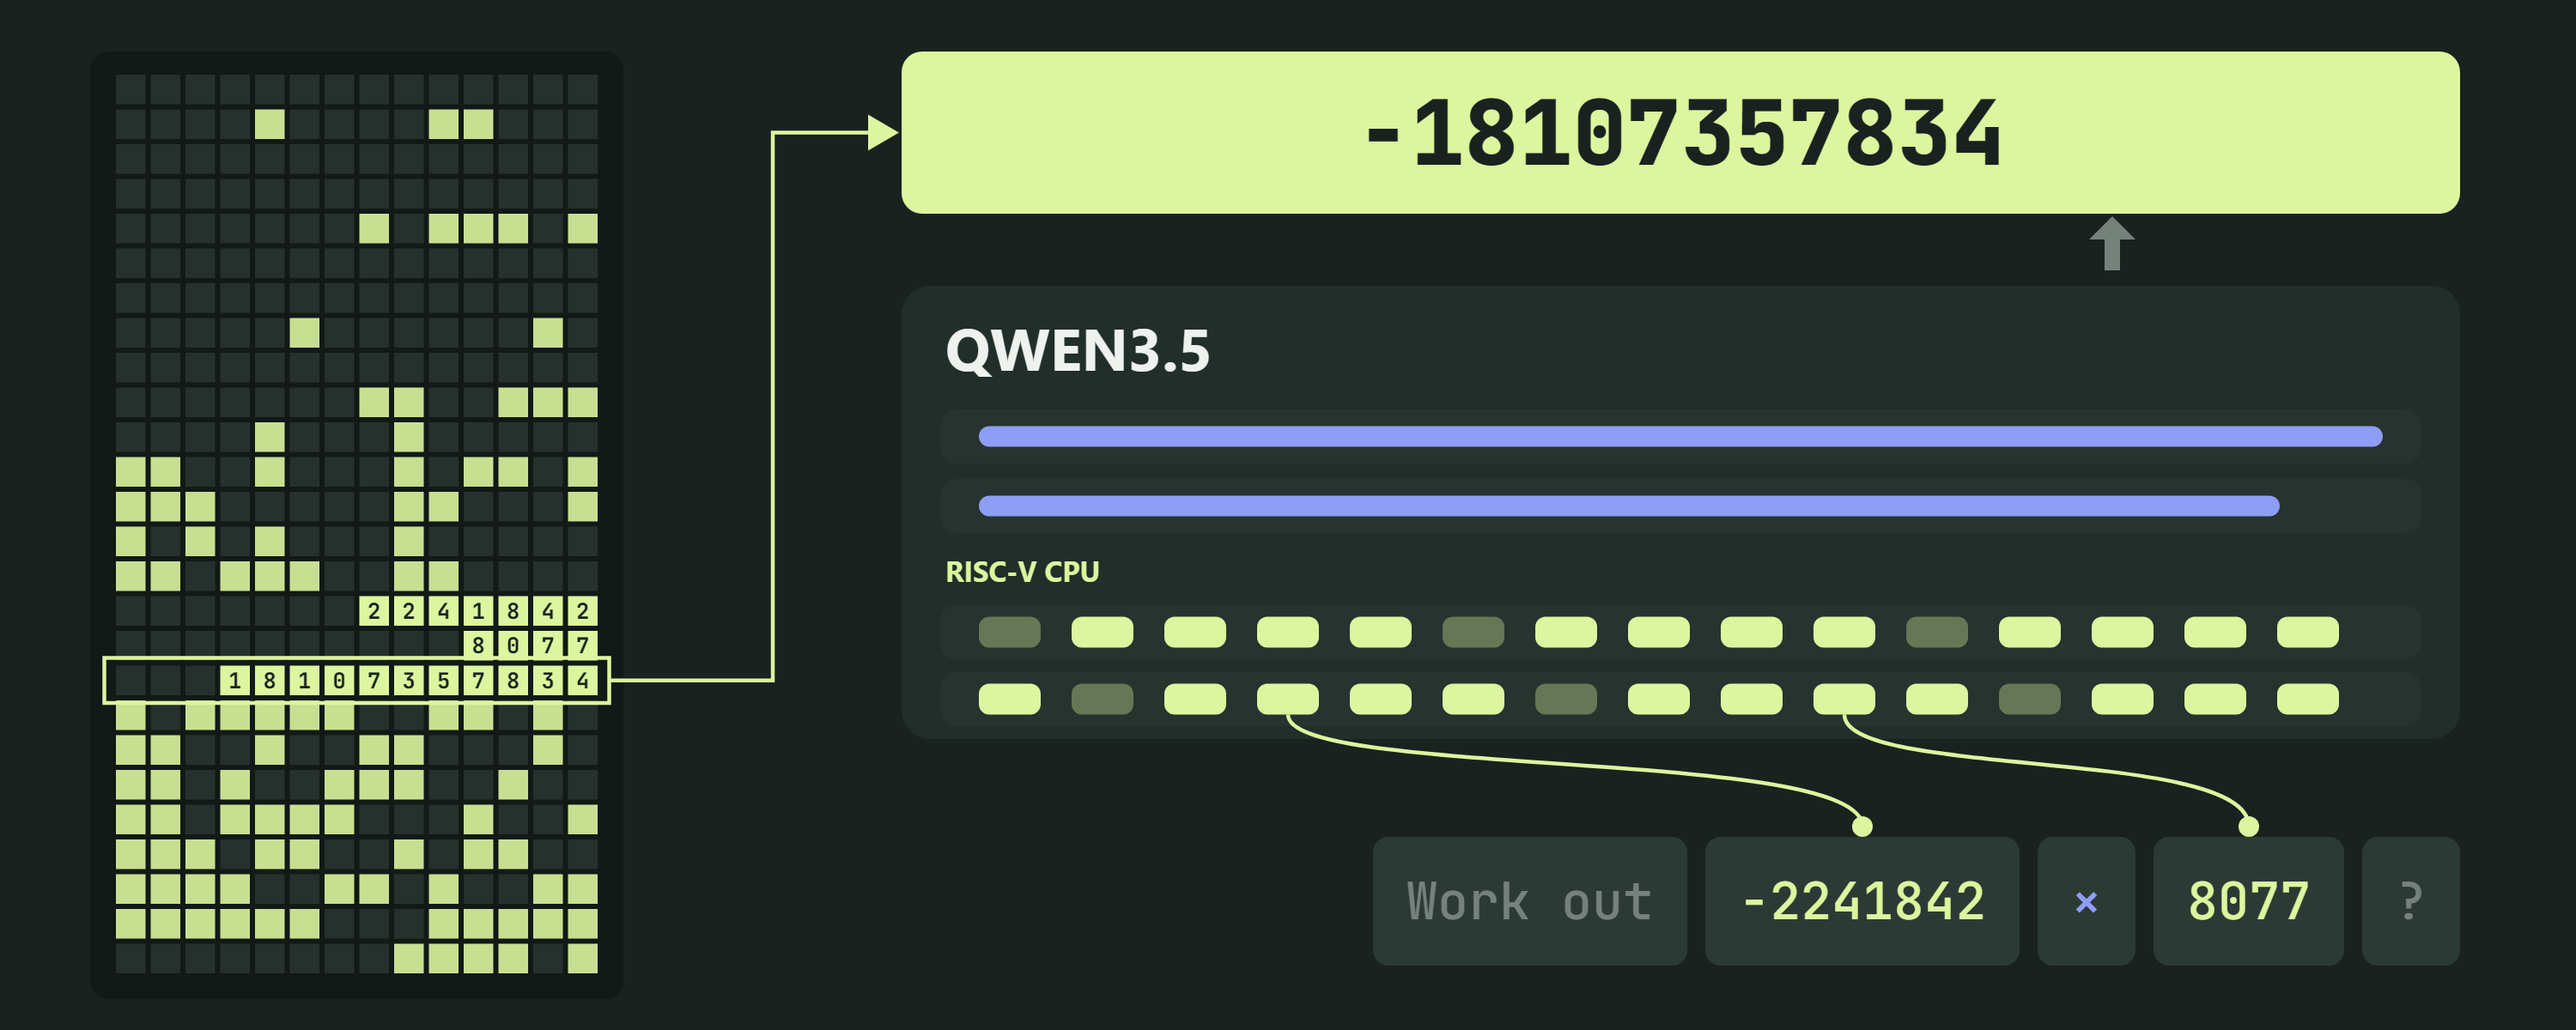
Qwenputer: A functioning, deterministic RISC-V CPU inside Qwen3.5
A RISC-V CPU compiled into Qwen3.5-4B's weights uses Gated DeltaNet layers as exact RAM and runs C and MicroPython inside forward passes.
Why it mattersIt shows hybrid-model recurrent state can act as exact, deterministic memory, giving a model internal computation without external tools. It also raises implications for hidden reasoning and monitoring that agent builders should understand.
Prevent Prompt Injection
OpenRouter tests layered prompt injection defenses against four models: data labeling, key guardrails, and tool-call checking.
Why it mattersTool-call checking against rules the model cannot change stopped all 73 attack emails in testing, while labeling documents as data alone only reduced them. Shows which layers to prioritize for agents that read untrusted content.
Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms
Hugging Face announces AnySpeechRecognizer, which runs Parakeet and Qwen3-ASR locally on Core ML with diarization, and AnyDecisionModel.
Why it mattersApple-platform developers can run speech-to-text and typed yes/no or multiple-choice decisions on-device through Swift APIs. This avoids routing both jobs through a generative LLM.
Control AI crawlers and assistants separately in Vercel Firewall
Vercel Firewall's AI Bots managed ruleset now separates AI crawlers from AI assistants.
Why it mattersSite owners can now allow AI assistants to answer user questions from their content while still blocking AI crawlers that scrape for training, a distinction that matters for anyone building on or against AI traffic.
Detect when your AI agent copies a self-replicating prompt injection
Datadog reproduces two self-replicating prompt injection attacks from OpenAI's report against a test agent and shows how evaluating tool outputs and tool calls catches the planted instruction and its copying into replies or skill files.
Why it mattersSelf-replicating injections can copy themselves into emails or skill files and spread across agents. Checking tool outputs and tool calls, not just final replies, is where this behavior becomes detectable.
Extract Tables From Pdf Llm
Walkthrough for extracting typed table rows from PDFs with a JSON schema.
Why it mattersPDF table extraction can fail without an error: a scan through the free parser returns zero rows, and long tables truncate at the token limit. Rejecting empty results and finish_reason length catches both.
Announcing Project ProtoStar: Making Publicly Funded Science AI-Ready
Hugging Face, CMU, Purdue, Georgia Tech, ASU and GWU launch Project ProtoStar to push publicly funded research toward AI-ready, machine-actionable datasets, models and code, opening with a CMU-run climate-risk intelligence challenge.
Why it mattersProject ProtoStar aims to get the roughly $190B/year of US-funded research released in AI-ready formats on open infrastructure, starting with a CMU climate-risk challenge.

Why Sam Altman is against a single superintelligence
A conversation on why AI-driven vulnerability discovery is accelerating, why most internet code hasn't been scanned by capable models yet.
Why it mattersModels are finding serious vulnerabilities across code nobody has scanned with them yet. Engineers should expect more disclosures and weigh architectural hardening over patching individual bugs.
Default to serverless for AI agents, then let production data decide what moves
Datadog argues agent workloads should start on serverless, since sessions spend most of their time idle between steps.
Why it mattersIf agents idle most of their lifetime, always-on sandboxes waste money. Scale-to-zero compute is a cheaper first choice before moving heavy workloads to dedicated capacity.
Mistral Large 4 updated weights and lower pricing on AI Gateway
Mistral Large 4's weights were updated on Vercel's AI Gateway with improved agentic coding, spreadsheet handling, web research and prompt-injection resistance.
Why it mattersThe same model ID now points to better agentic-coding performance and stronger prompt-injection resistance at a lower price, with no code changes needed for existing integrations.
Claimable sandboxes: Frictionless Stripe accounts for agents
Stripe introduces claimable sandboxes: working test API keys issued with no registration, claimable afterward.
Why it mattersAgents can obtain working Stripe test keys without a human signup step and defer account claiming until the integration works. This pattern lets other API providers let agents explore a product without losing flow.
Vercel Plugin is now available in Antigravity
Vercel's plugin is now in the Google Antigravity marketplace, giving agents skills and guidance for Vercel APIs including AI SDK, Functions and Workflow.
Why it mattersAntigravity users can now install Vercel's plugin from the marketplace, giving their agent Vercel-specific skills for AI SDK, Functions and Workflow instead of relying on generic knowledge.
Droid 1.0: Building a Frontier Harness
Factory releases Droid 1.0, its model-independent agent harness, adding a programmatic tool-calling engine that lets models run hundreds of tool calls per request.
Why it mattersDroid 1.0 lets models run hundreds of tool calls in a single request via programmatic tool calling, and claims up to 20% better efficiency than native model harnesses. Useful for anyone choosing or building an agent harness.

Welcome Le Chonk: Mistral Large 4 on Hugging Face
Hugging Face's rundown of Mistral Large 4 ("Le Chonk").
Why it mattersMistral Large 4 ships as a ~1T-parameter MoE (49B active) with a 1M-token context window, released in FP8 and NVFP4 variants under an open-weight license, and is positioned as particularly strong for cybersecurity and coding agents.

API credits, now in ChatGPT Pro and Business plans
OpenAI is rolling monthly API credits (up to $500, tiered by plan) into ChatGPT Pro and Business subscriptions so subscribers can build apps and agents on the API without a separate bill.
Why it mattersChatGPT Pro and Business subscribers can now claim up to $500/month in API credits toward building apps and agents, with specific tiered amounts by plan, lowering the cost of experimenting with OpenAI's API for existing subscribers.
Quoting Ted Sanders
An OpenAI engineer explains the lineup ordering Luna < Terra < Sol < Astra, why model size explains most performance variation.
Why it mattersTells you how to read OpenAI's model names: tiers map mostly to model size, which tracks cost, reliability, and factual recall, and version numbers signal release order and relatedness rather than big leaps.

OpenAI is adding monthly API credits to ChatGPT Pro (up to $500 by tier) and Business (pooled up to $500 per workspace) subscriptions. Credits are claimed in ChatGPT billing and used through the OpenAI Developers plugin in Codex, which can also provision a project API key.
Why it mattersChatGPT Pro and Business subscribers now get monthly API credits (up to $500) usable across the OpenAI platform, so prototyping agents and apps no longer requires a separate API budget.
How Anthropic Merges 30,000 Code Changes a Day - Manish Kapur, Sonar & Addy Osmani, Anthropic
Sonar's Manish Kapur and Anthropic's Addy Osmani detail how Anthropic scaled merged code changes from roughly 2,500 to 30,000 a day, using Claude for first-pass, evidence-backed review and multi-layered verification across a 'software factory.'
Why it mattersAnthropic's internal merge rate jumped from ~2,500 to 30,000 changes/day by having Claude do first-pass review backed by real verification evidence rather than human eyeballing alone, a concrete data point on what review has to become as agents scale code output.
openai-python v3.41.0
openai-python 3.41.0 adds typed references for Realtime response inputs, response tool usage models and metadata filtering of agent sessions.
Why it mattersIf you build on the OpenAI Python SDK, this adds typed references for Realtime inputs, tool-usage models on responses, and agent-session filtering by metadata. WebSocket reconnects now recover queued binary frames.
servers v2.2.0
The MCP reference servers v2.2.0 release maps the eMudhra CA compromise onto each server.
Why it mattersIf you run the reference MCP servers, this says which ones verify HTTPS through Node.js or certifi and what to update after the eMudhra intermediate CA key exposure.

AssemblyAI's first text-to-speech model, aimed at voice agents, is now routable via OpenRouter. It offers 4,000+ voices with US or EU serving, and Cekura's benchmark reportedly rates it well on speed, accuracy and naturalness at $15 per million characters or less.
Why it mattersVoice-agent builders can call AssemblyAI-TTS-1 through OpenRouter's single API, with 4,000+ voices and US or EU serving. Cekura's benchmark claims strong naturalness at or under $15 per million characters, which is unverified here.
ollama v0.40.13
Ollama v0.40.13 brings Liquid AI's LFM3 models, including lfm3-audio text-to-speech and lfm3-omni, to Linux and Windows, previously limited to Apple silicon.
Why it mattersLocal LFM3 text-to-speech and omni models were limited to Apple silicon. They now run through Ollama on Linux and Windows, widening where you can deploy them.

Why Agents Love Supabase
Latent Space talks with Supabase's founders about why frontier coding models consistently pick Supabase for app backends.
Why it mattersAgents choose backends by default, and the discussion explains which Supabase features (local runtime without Docker, Git-held schema, co-located compute) make a backend easier for coding agents to operate.

A benchmark researcher notes that Gemini 4 Carbon trails Opus 5.5 on Artificial Analysis v4.3.2 (57 vs 58) but leads on v5 (59 vs 58). The thread argues tiny gaps plus index version timing can decide who is ranked first.
Why it mattersLeaderboard ranks between frontier models can flip with an index revision when gaps are one or two points. Treat a #1 claim as within noise and evaluate on your own tasks before switching models.

Why Agents Love Supabase — with Paul Copplestone and Ant Wilson
Supabase co-founders Paul Copplestone and Ant Wilson explain why AI agents increasingly default to Supabase as a backend.
Why it mattersSupabase's founders explain the specific architectural choices, compute beside the database, declarative schemas, and OrioleDB/Multigres scaling, that make Postgres a default backend for agent-built applications.
ElevenLabs Cue: single-pass forced alignment across 29 languages
ElevenLabs details Cue, a forced alignment model that times every character in one pass over recordings of any length.
Why it mattersCue aligns transcripts to audio in a single pass for any recording length, removing the chunking that accumulates timing error. It is available through the Forced Alignment API for subtitle, dubbing and voice agent pipelines.

AI That Hunts Logic Bugs Before Attackers Do - Taylor Luttrell-Williams, Sonar
A Sonar talk on hunting business-logic and access-control bugs with agents: map the repo, run three specialist agents, and adversarially validate findings.
Why it mattersPattern-based SAST misses valid code with flawed intent. The talk shows an agent architecture (repo map, specialist agents, adversarial validation of each finding) that surfaced admin escalation and MFA bypass in a demo app.

Runway released a Codex plugin that packages the context Codex needs to wire Runway's generation API into an app. Developers describe the desired output and Codex builds the integration. The post does not detail plugin contents.
Why it mattersA single Codex plugin install lets the agent write Runway API integrations from a plain description of what the app should generate. It cuts the manual docs-reading step for builders adding video generation.
Box Mount now runs in Vercel Sandbox
Box Mount, in private preview, syncs a Box folder into a Vercel Sandbox directory so agents use ordinary filesystem calls.
Why it mattersAgents in a sandbox can read and write Box files as a normal directory, and results persist after the sandbox is deleted. Box credentials stay under a separate sandbox user from the agent.

GitHub's Universe release thread covers Copilot Fusion multi-model orchestration, Projects, a Security canvas, session-derived 'dreaming' that opens PRs for memory and skill changes, and shareable Automations with access and spending limits. The linked blog body was unreadable.
Why it mattersCopilot now orchestrates multiple models, runs scheduled automations with access and spend limits, and proposes memory and skill updates as reviewable pull requests. Teams running coding agents get new routing, governance and cost controls.

Artificial Analysis benchmarks Gemini 4 Carbon: first on Intelligence Index v5, second on its Coding Agent Index, with lower cost per task than Claude Opus 5.5. Hallucination rate rises to 11% versus Argon. Pricing is $4/$20 per 1M tokens, 1M context, with rollout limited to selected users.
Why it mattersGemini 4 Carbon trails only Claude Opus 5.5 on coding agent benchmarks while using 29% fewer output tokens per task. Accuracy gains come with a hallucination rise from 4% to 11%, and access is limited to selected users for now.
AutomationBench grades agents on end state, exposing false-success failures
Zapier's AutomationBench joins Fireworks' Specialized Intelligence Index.
Why it mattersAutomationBench grades what changed in 47 simulated apps instead of what the agent claims, and the top model completes only about half of tasks.

Google announces Gemini 4 Carbon, claiming state-of-the-art cybersecurity and long-horizon capability, with strong autonomous coding and cyber defense. Access starts with trusted defenders in the Fairwind program, with wider availability promised but undated. The post gives no benchmark numbers.
Why it mattersGemini 4 Carbon is not generally available. It goes first to vetted cyber defenders, so most engineers cannot build on it yet. Google claims state-of-the-art cybersecurity and long-horizon coding, but publishes no figures in the post.

Vals AI benchmarks Gemini 4 Carbon: #2 on the Vals Index v2.2 and #1 on Finance Index and Legal Research. The thread details its tradeoffs against Argon, including 2.3x reasoning tokens, slower agentic tasks, and lower cost than Sonnet 5.5 and Opus 5.5, with a 1M context window.
Why it mattersGemini 4 Carbon tops Finance and Legal Research benchmarks but takes over 50 minutes per legal task and uses 2.3x Argon's reasoning tokens.
Gemini 4 Carbon: our next frontier model
Google announces Gemini 4 Carbon, ranking first on the Artificial Analysis Intelligence Index v5.0 at 59.
Why it mattersGoogle's new frontier model reports leading scores for finding, exploiting, and patching vulnerabilities, plus gains in coding and agentic tasks. Engineers choosing models for agents and security work get new numbers to evaluate.
AssemblyAI launched its first text-to-speech model. Artificial Analysis ranks it #12 in its Provider Voice Arena and #10 in Controlled Voice, scores 81.7% on pronunciation robustness, and measures 162 characters per second at $15 per 1M characters.
Why it mattersAssemblyAI-TTS-1 gives voice agent builders a mid-priced option at $15 per 1M characters that ranks near the top 12 in blind arenas.
Potential conversation partners in Bluesky using agentic search
An experiment in matching conversation seekers on Bluesky: an agent builds a seed cohort, then generates and refines search queries against a Postgres index of a week of posts.
Why it mattersShows an agentic retrieve-review-iterate loop finding matches for 79% of sampled seeds, a reference point for engineers building agent search over their own corpora.
Copilot Fusion: model routing and critique patterns explained
GitHub's docs describe Copilot Fusion as a runtime model router using single, cascade or critique execution, with Standard, High and Max effort tiers and optional local models.
Why it mattersCopilot Fusion routes each prompt between single-model, cascade and critique patterns, so costs vary by effort tier. GitHub claims near Claude Code quality at about half the cost, in a vendor-funded evaluation.
An index of the vibe-coding frontier. Corrections welcome.