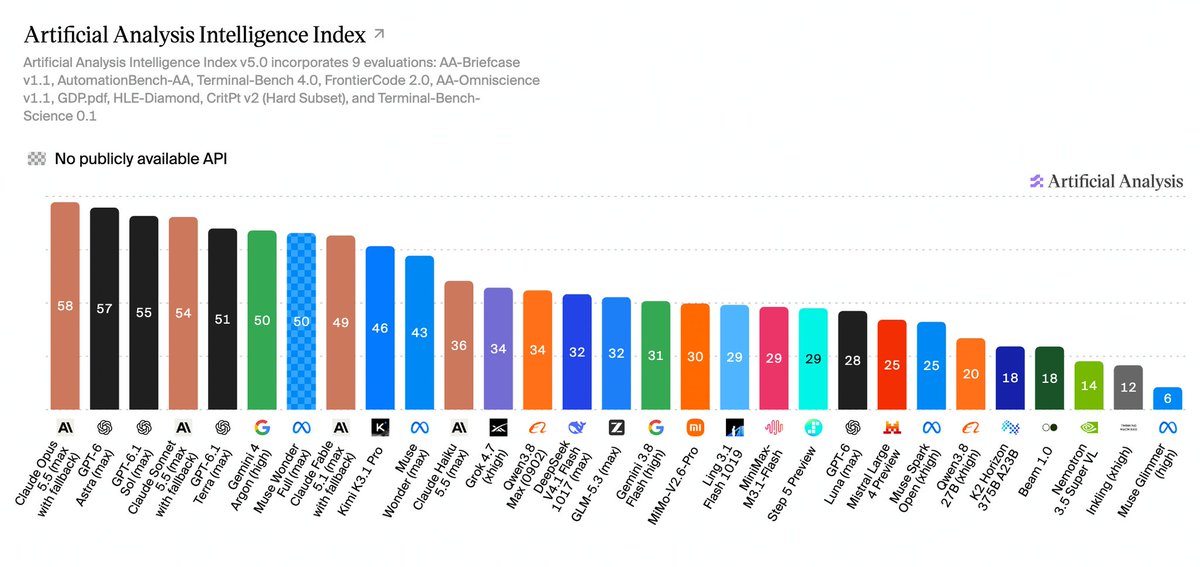
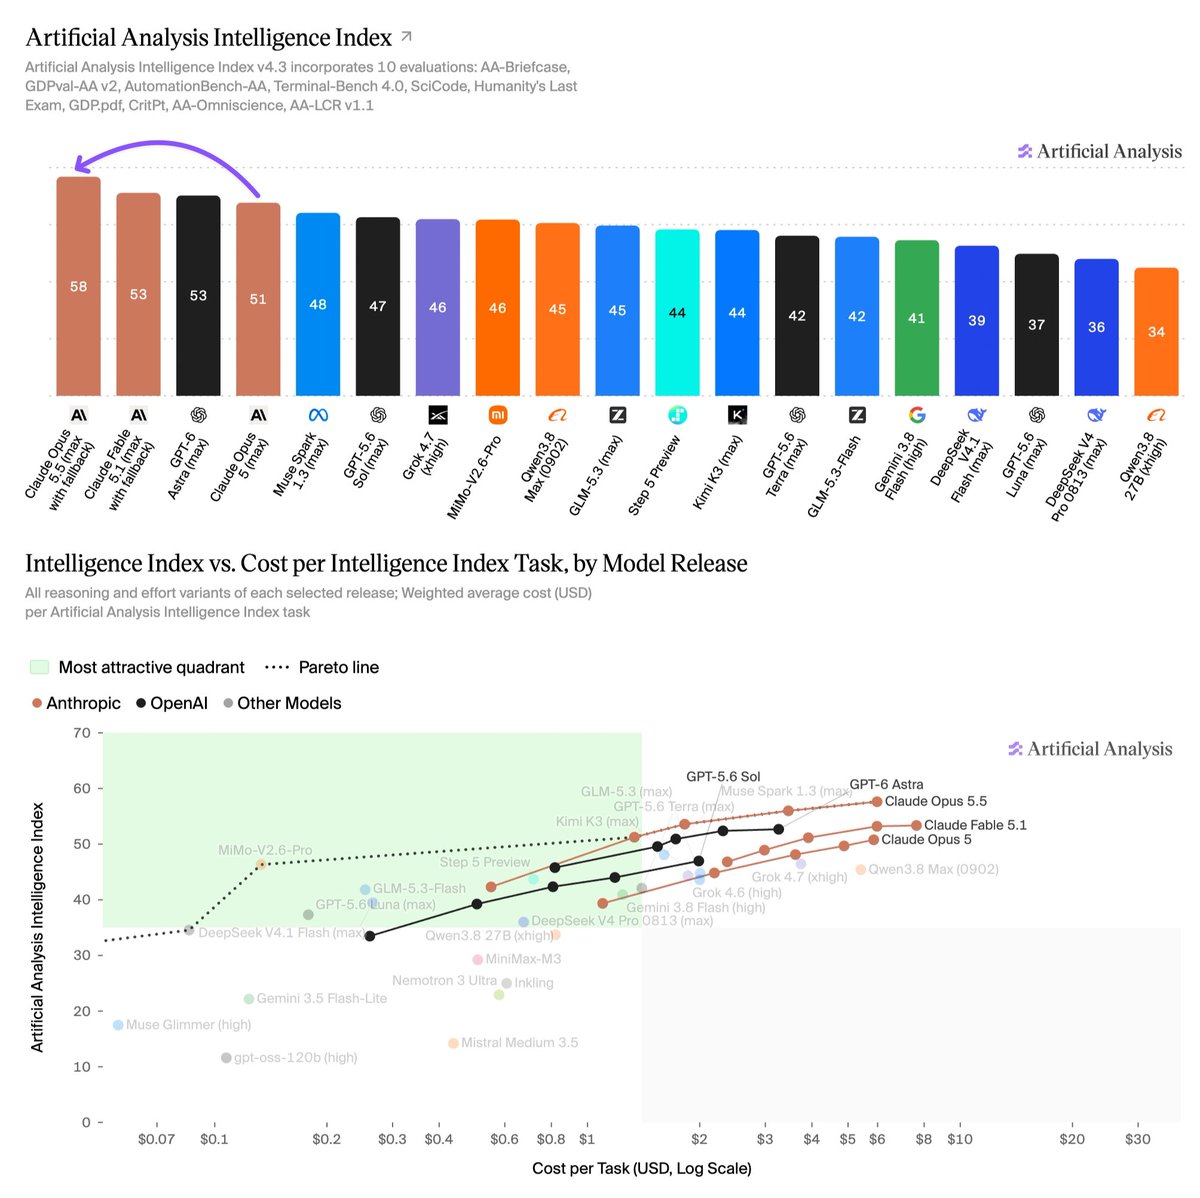
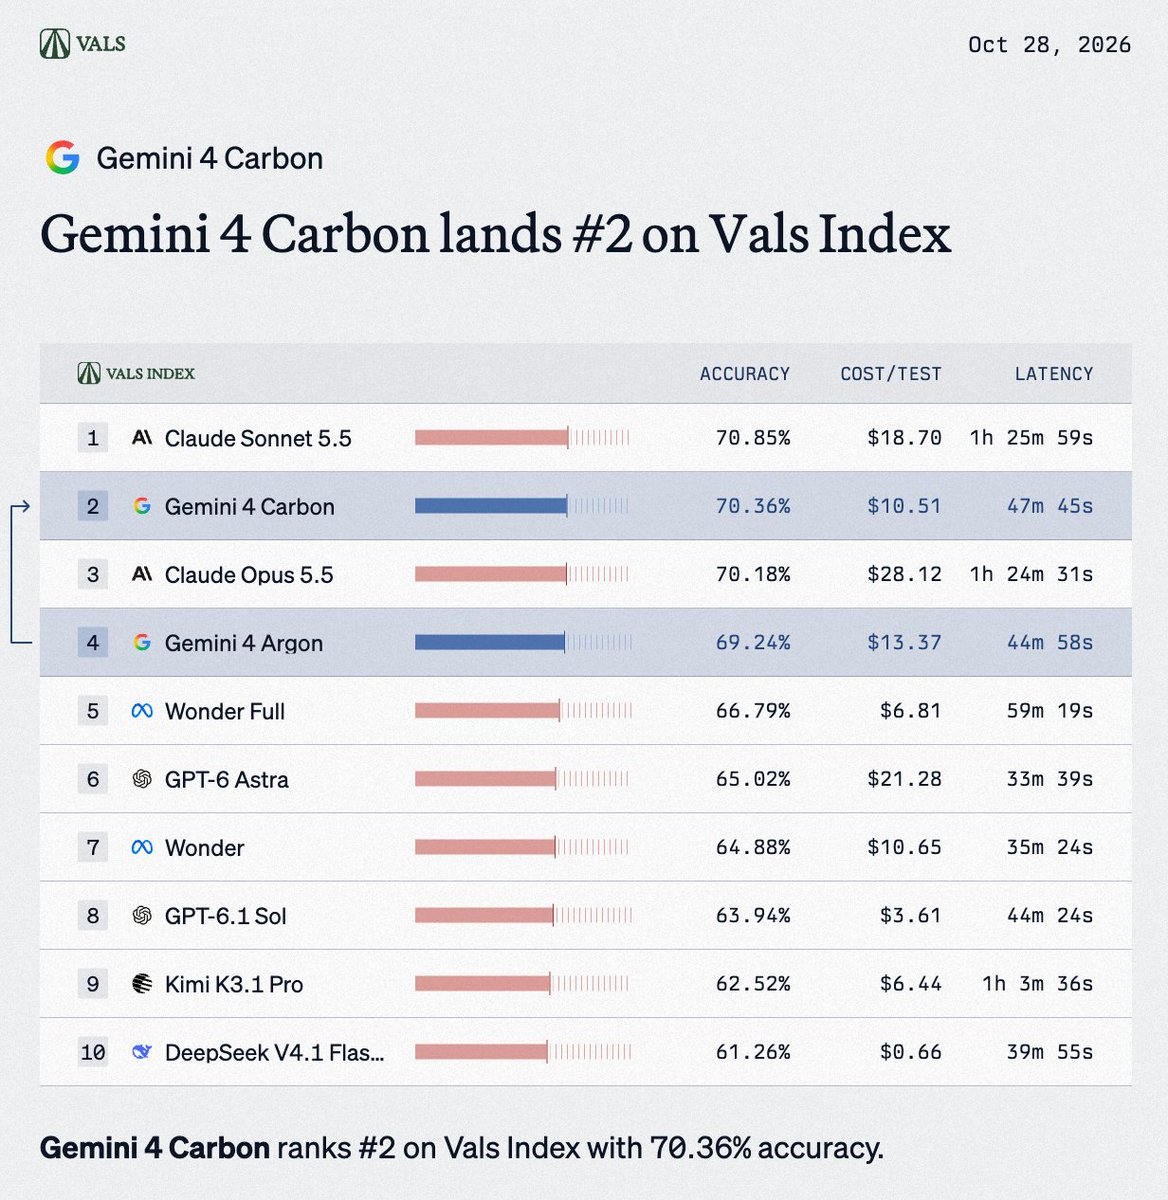
Fun fact: if Gemini 4 Carbon would have been released yesterday, it would not have been #1 on Artificial Analysis.
On AA v4.3.2, it scores 57 against Opus 5.5 58. On v5, it scores 59 compared to Opus 5.5 58.
Conspicuous timing? :)
Leaderboard ranks between frontier models can flip with an index revision when gaps are one or two points. Treat a #1 claim as within noise and evaluate on your own tasks before switching models.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.