Aidan Gomez is Cohere’s co-founder and CEO and a co-author of “Attention Is All You Need,” the paper introducing the Transformer. His research also includes reversible neural networks, while Cohere develops AI models and software for enterprise use.[2][6][7]
Start with Attention Is All You Need →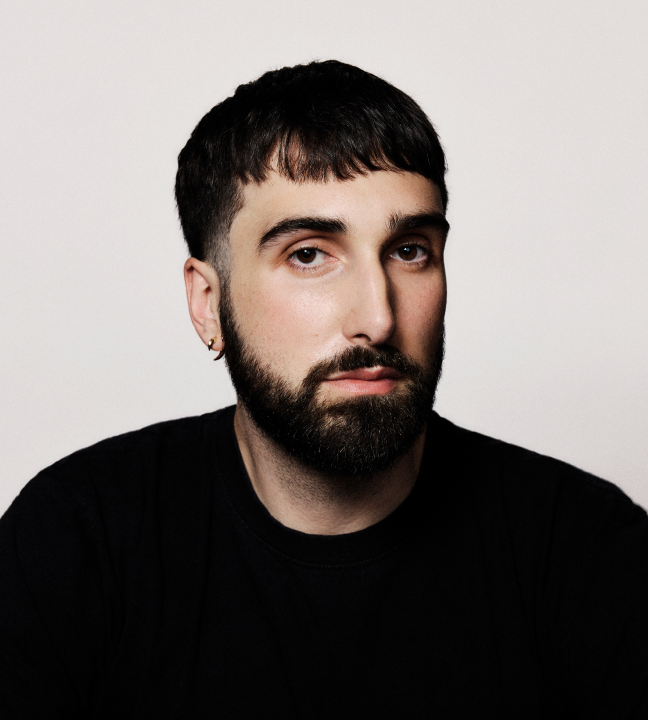
 GitHub
 X
Background
Gomez graduated from the University of Toronto in computer science in 2018. His CV describes an honours bachelor’s degree with distinction and research with Roger Grosse. It records Google Brain internships in 2017 and 2018, followed by a student-researcher role. His personal site identifies Yarin Gal and Yee Whye Teh as his Oxford advisers. Oxford’s research archive records a DPhil thesis, and OATML gives a 2018–2023 study period.[3][1][4][5][8][9]
Career
Cohere’s current company page lists Gomez as co-founder and CEO alongside co-founders Nick Frosst and Ivan Zhang. The company builds enterprise AI models and products, including North, a platform intended to help workers retrieve information and automate tasks using organizational data. Gomez’s role establishes responsibility for the company’s direction. It does not make him the individual author of every model or feature Cohere releases. His personal account also records earlier leadership of FOR.ai, a research collaboration group.[2][1]
Contributions
The Transformer paper
Gomez is one of eight authors of the 2017 paper “Attention Is All You Need.” It proposes the Transformer, a neural-network architecture that uses attention to model relationships within sequences instead of relying on recurrent or convolutional layers. The paper evaluates this design on machine translation and reports that it supports more parallel computation during training. For a newcomer, its central contribution is a different way to process context; its authorship is shared across the team, not a sole-inventor claim.[6]
Training with less activation memory
Gomez is the first-listed author of “The Reversible Residual Network,” written with Mengye Ren, Raquel Urtasun and Roger Grosse. Training a deep network normally stores intermediate activations so it can calculate how to change its weights. RevNets reconstruct many of those intermediate values from later layers, reducing the need to keep them in memory. The paper compares image-classification accuracy with conventional residual networks. This work gives a second view of his research: changing a model’s structure to make training more practical.[7]
A reading path through his research
Start with the Transformer paper’s introduction and architecture figure, then read RevNet for a separate problem in training efficiency. His Oxford thesis, “Applications and methodologies of machine learning on sequences,” offers a longer academic route through his research.[6][7][5]
Tools, writing & talks
Writing, research & talks
Start here
Attention Is All You Needarxiv.orgThe original Transformer paper. Its translation experiments show what the architecture was designed to solve, making it a useful starting point before reading claims about its later uses.
The clearest primary record of his Transformer contribution; begin with the introduction and figure, then the technical details.
Co-author[6]Cohere releases North Micro Vision, its smallest vision-language model, targeted at enterprise document understanding and published open-weights under Apache 2.0 on Hugging Face. Permissive licensing is the operative detail for anyone building self-hosted document pipelines.
Catalog workOriginal sourceA profile of Cohere's sovereign-AI thesis: enterprise models deployed inside customer infrastructure, Command A sized to run on two GPUs, and Model Vault walling weights off from the vendor. Frosst reframes sovereignty as diversified dependence rather than decoupling, with chips the sole external ti
Catalog workOriginal sourceCohere released Command A+ under Apache 2.0, its strongest model to date, on the same permissive license as Cohere Transcribe. Gomez notes the license was a contested internal call. Early readers flag unusual architecture choices, including parallel MoE and attention computation.
Catalog workOriginal sourceCohere's Command A+ arrives under Apache 2.0: the company's most capable model to date, optimized to run on as little hardware as possible and released with open weights. The lab's first fully permissive frontier-tier release.
Catalog workOriginal sourceCohere Transcribe is the lab's first audio model: Apache 2.0 weights on Hugging Face, multilingual transcription across 14 languages, and a claimed first place on the Open ASR leaderboard. Notable as an open-licensed challenger in a category dominated by hosted speech APIs.
Catalog workOriginal sourceCohere Labs released Tiny Aya, a family of small multilingual models at 3.35B parameters targeting 70+ languages and on-device execution. The pitch is coverage of languages that frontier models underserve, at a size that fits local inference rather than a hosted endpoint.
Catalog workOriginal sourceCohere's Model Vault gives its models a dedicated, fully managed home: isolated VPC, no noisy neighbours, no shared rate limits. It targets the gap between calling a public API and standing up your own inference stack for regulated or throughput-sensitive workloads.
Catalog workOriginal source- The Reversible Residual Networkarxiv.org
Explains how reconstructing intermediate activations can reduce neural-network training memory. Familiarity with residual networks and backpropagation helps with the method and experiments.
First-listed co-author[7] Gomez’s Oxford DPhil thesis offers a longer academic account of machine learning on sequences.
Thesis author[5]