Grok 4.7 Lands on Mercor's APEX Leaderboards
- Source
- x.com
- Date

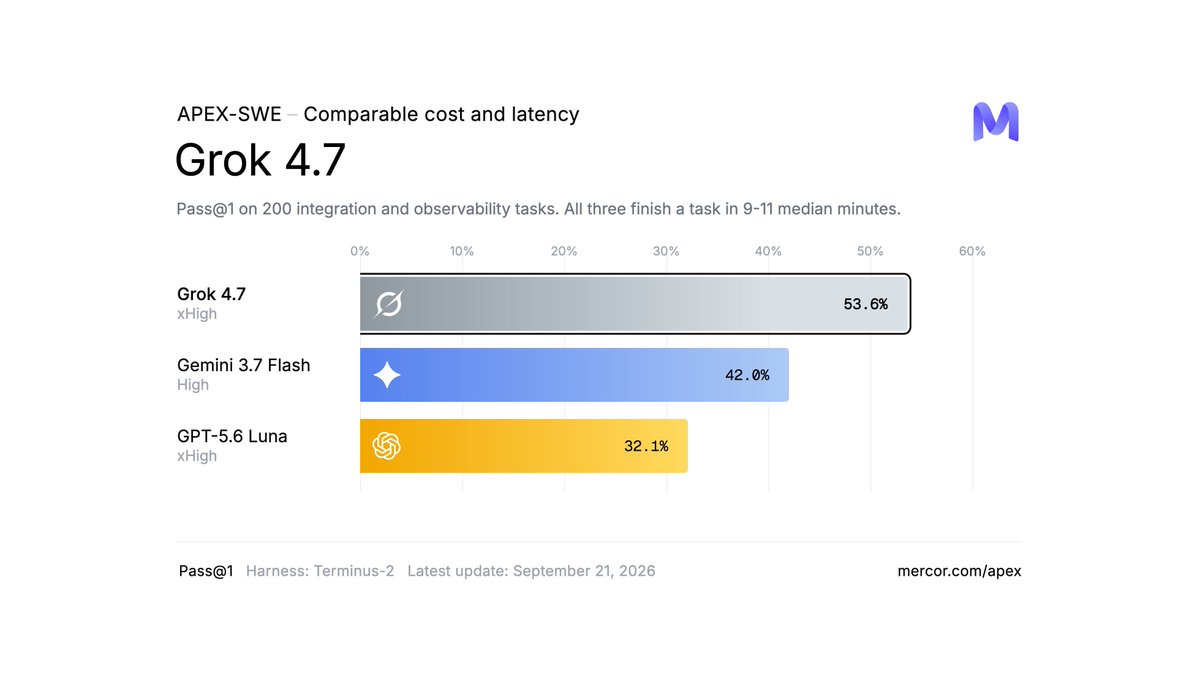
Grok 4.7 just landed on @mercor's APEX leaderboards: > #5 on APEX-SWE at 53.6% > #13 on APEX-Agents at 54.6% The notable part is the bracket, which sits in the same cost and latency tier as Gemini 3.7 Flash and GPT-5.6 Luna while leading on SWE. APEX updates with every major model release, so you can see how the newest models stack up, compare token costs, and explore results from third-party benchmarks like BrowseComp and Terminal-Bench. See the full leaderboard at https://t.co/7sAoPQZDh7 *partnerpost
Context
xAI's Grok 4.7 has been added to Mercor's APEX benchmarks, a set of leaderboards that score AI models on longer, economically valuable tasks like software engineering and multistep work rather than short quiz-style questions. Per AlphaSignal's post covering the results, it placed 5th on APEX-SWE at 53.6% and 13th on APEX-Agents at 54.6%.
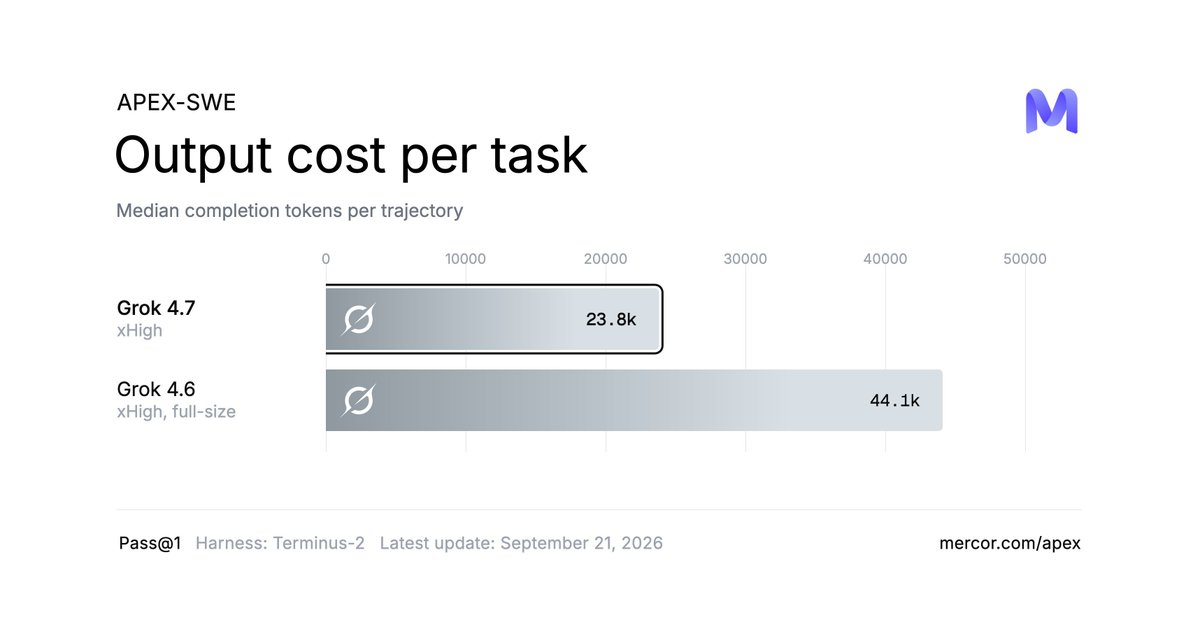
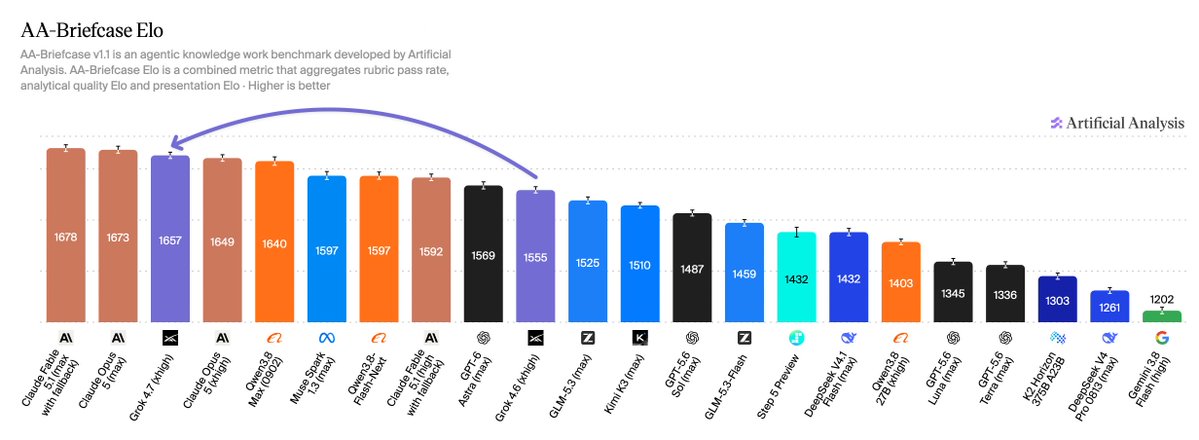
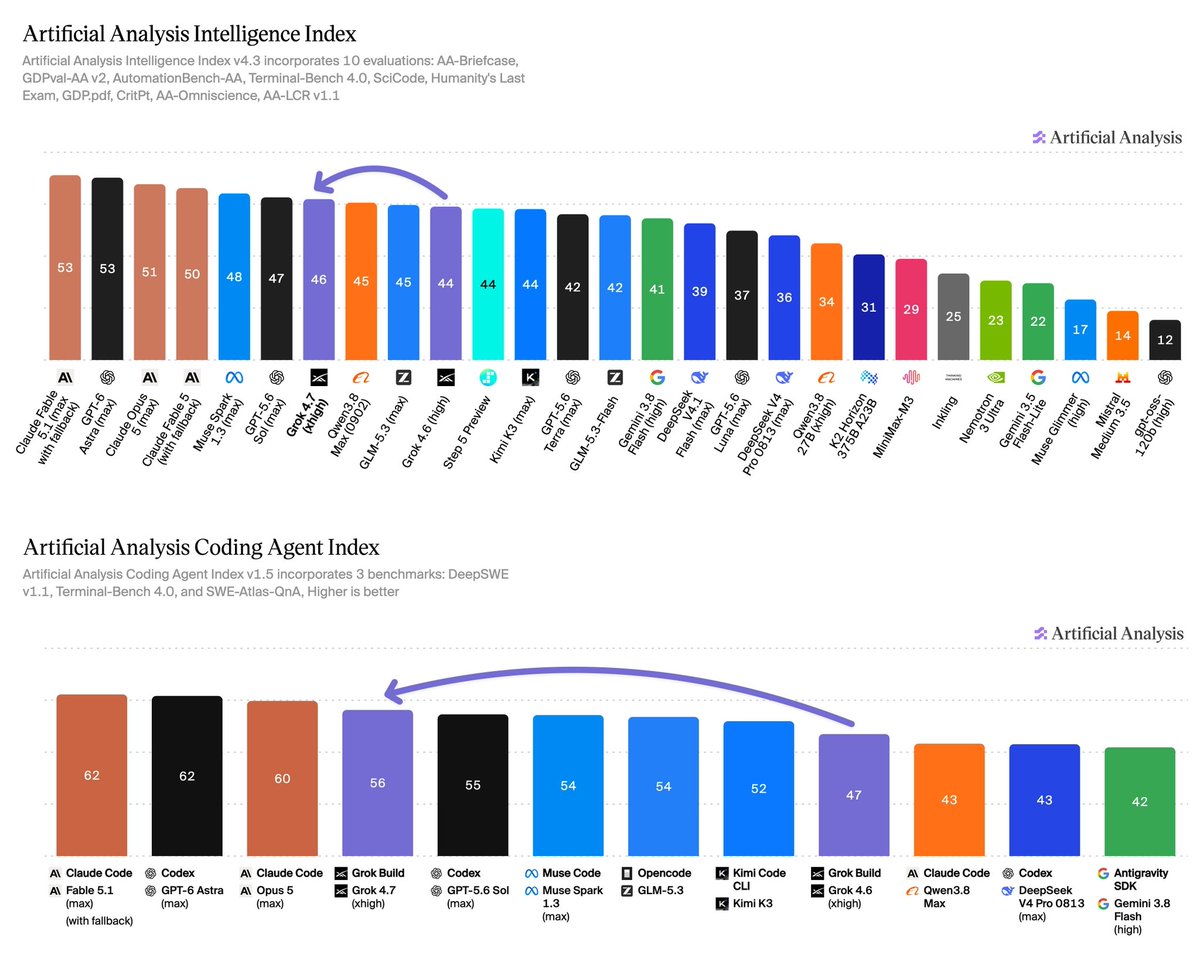
AlphaSignal highlights the price bracket rather than the raw rank: Grok 4.7 sits in the same cost-and-latency tier as Gemini 3.7 Flash and GPT-5.6 Luna, and among that specific group it leads on the SWE . That's consistent with Artificial Analysis's benchmarking of Grok 4.7 from the day before, which found the model gaining ground on agentic coding tasks while using more per task than the top performers, a detail that matters when comparing same-price competitors rather than raw accuracy alone.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…