Grok 4.7 closes in on Anthropic models on AA-Briefcase-Lite
- Source
- x.com
- Date

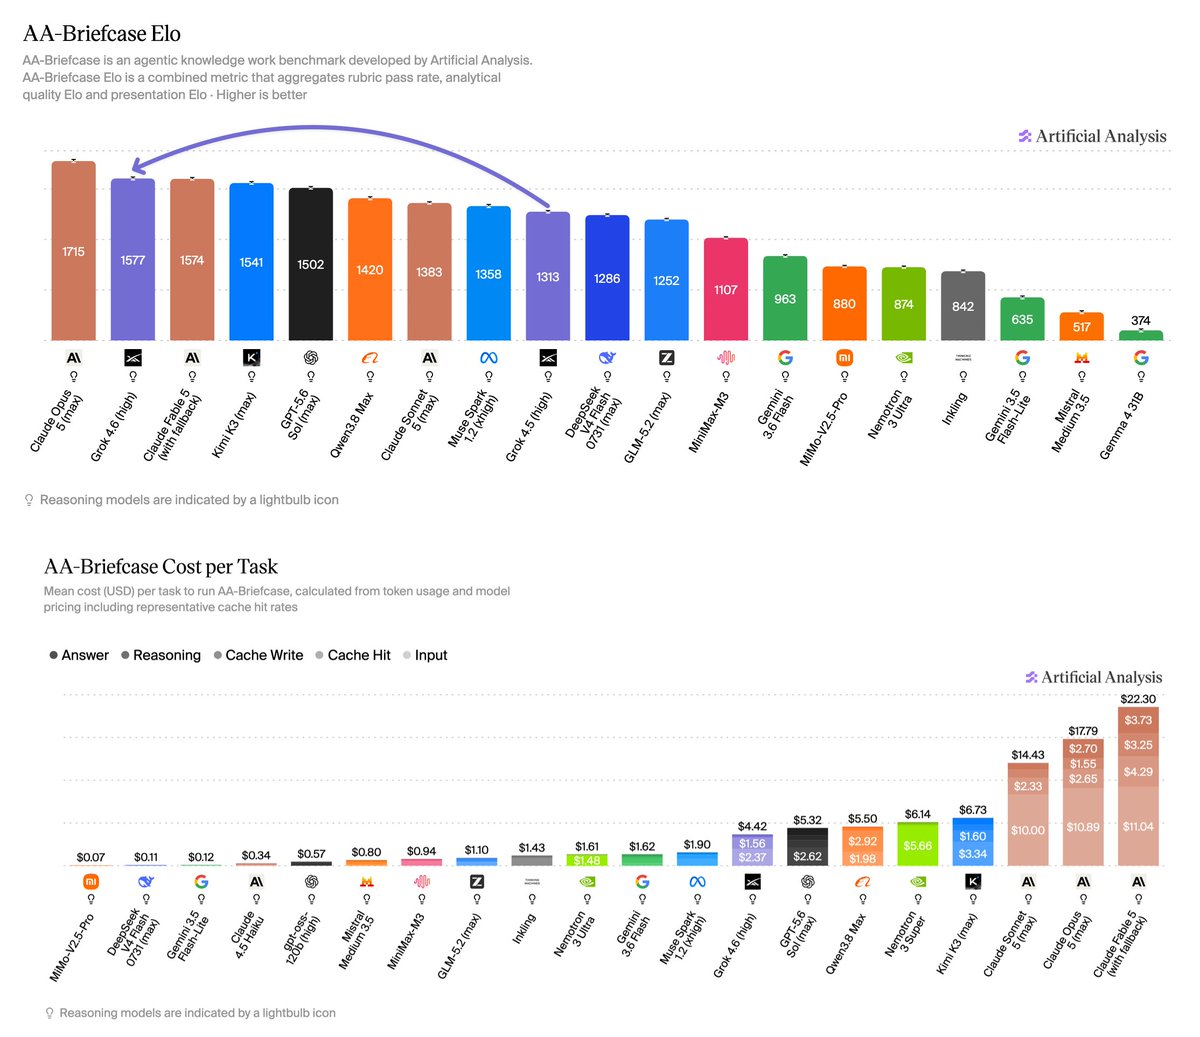
Grok 4.7 is behind only Anthropic models on AA-Briefcase, ranking just behind Opus 5 at ~50% of its Cost per Task Grok 4.7’s improvements over Grok 4.6 are clear in AA-Briefcase-Lite, our public due diligence scenario where models are tasked with building market models and target assessment decks. Grok 4.7 gains significantly in Analytical Quality Elo (1698 → 1994) with a slight regression in Presentation Elo (1531 → 1499). API cost to produce example decks: Grok 4.7 (xhigh) ~$8 vs. Grok 4.6 (xhigh) ~$4.40

Context
Artificial Analysis says SpaceXAI's Grok 4.7 now ranks behind only Anthropic's models on its AA-Briefcase , sitting just behind Claude Opus 5 at about half of Opus 5's cost per task. To show where the improvement over Grok 4.6 comes from, the post turns to AA-Briefcase-Lite, a public scenario in which models do due-diligence work: building market models and decks that assess a target company.
The gain comes from the quality of the analysis. The Lite results are reported as Elo ratings, which rank models against one another. Grok 4.7's Analytical Quality rating rose from 1698 to 1994, while its Presentation rating slipped from 1531 to 1499. The new model's analysis was rated much better, and the presentation of its decks slightly worse.
The improvement also costs more. Producing the example decks through the API cost about $8 with Grok 4.7 at its xhigh reasoning setting, against about $4.40 for Grok 4.6 at the same setting, roughly 1.8 times as much. The post's two cost figures point in different directions and should be kept apart: on AA-Briefcase, Grok 4.7 costs about half as much per task as Opus 5, while the example decks cost nearly twice as much to produce as with its own predecessor. Both come from Artificial Analysis's own runs, so they describe those tasks rather than a general price comparison. Artificial Analysis's broader benchmark post on Grok 4.7 covers its results across the rest of the Intelligence Index.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…