Grok 4.7 benchmarks: agentic coding gains, heavy token use
- Source
- x.com
- Date

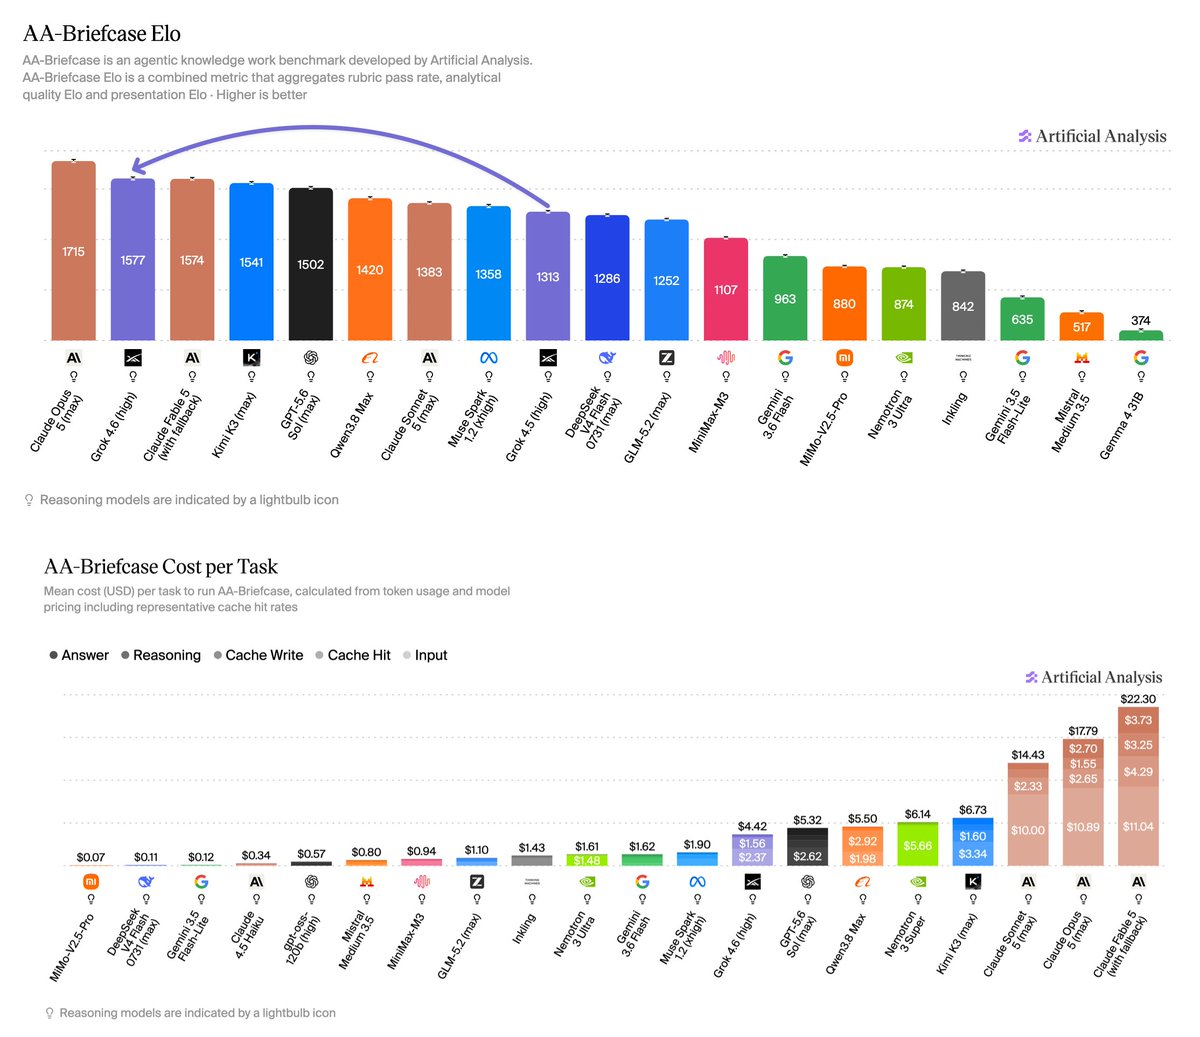
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort. Congratulations to @spacexai and @ElonMusk on the release! Key takeaways: ➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high). ➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5. ➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6…

Context
Artificial Analysis, which runs its own suite on new AI models, scores SpaceXAI's Grok 4.7 at 46 on its Intelligence Index, two points above Grok 4.6, and says that puts SpaceXAI among the top four AI labs on the index. The overall gain is small because the improvement is concentrated. Grok 4.7 got much better at agentic knowledge work, meaning long, multi-step jobs a model carries out on its own, and at coding through SpaceXAI's own tool, Grok Build. On most of the index's other tasks it roughly matches Grok 4.6.
The agentic results are reported as Elo ratings, which rank models against one another rather than counting tasks completed. On AA-Briefcase, Artificial Analysis's private benchmark for long-horizon knowledge work, Grok 4.7 rose 111 points to 1657, which the firm says places it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA it reached 1695, 90 points above Grok 4.6. Paired with Grok Build, it scored 56 on the Coding Agent Index, up 9 points, and ranks fourth among models tested in the coding tool their own maker ships, behind Claude Fable 5.1, GPT-6 Astra and Claude Opus 5. Elsewhere the movement was small in both directions: gains of 4.5 percentage points on Terminal-Bench 4.0 and 3.0 on GDP.pdf, and drops of 3.7 on AA-LCR and 1.1 on AutomationBench-AA.
The price per did not change, but the number of tokens did. Grok 4.7 keeps Grok 4.6's pricing of $2 per million input tokens and $6 per million output tokens, with cached input at $0.50, yet at its highest reasoning setting, xhigh, it produced about 81,000 output tokens per Intelligence Index task. Grok 4.6 used about 36,000 and GPT-6 Astra about 27,000. At the unchanged rate, the output tokens alone come to roughly $0.49 per task against about $0.22 for Grok 4.6. The comparison also mixes settings: Grok 4.7 was tested at xhigh and Grok 4.6 at high, and Grok 4.7's effort can be turned down as far as low, so these results describe the most expensive configuration and say nothing about how the model scores at lower settings. A follow-up from Artificial Analysis breaks down the AA-Briefcase results.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…