Grok 4.7
- Source
- x.ai
- Author
- meetpateltech
- Date
xAI released Grok 4.7 as a larger base model trained for a longer reinforcement learning run, with native training on the same Grok Bot harness the model runs in production rather than a separate training environment. Pricing holds at Grok 4.6's rate, and xAI publishes CursorBench, DeepSWE, and Terminal-Bench scores alongside a rebuilt safety stack aimed at cybersecurity dual use tasks.
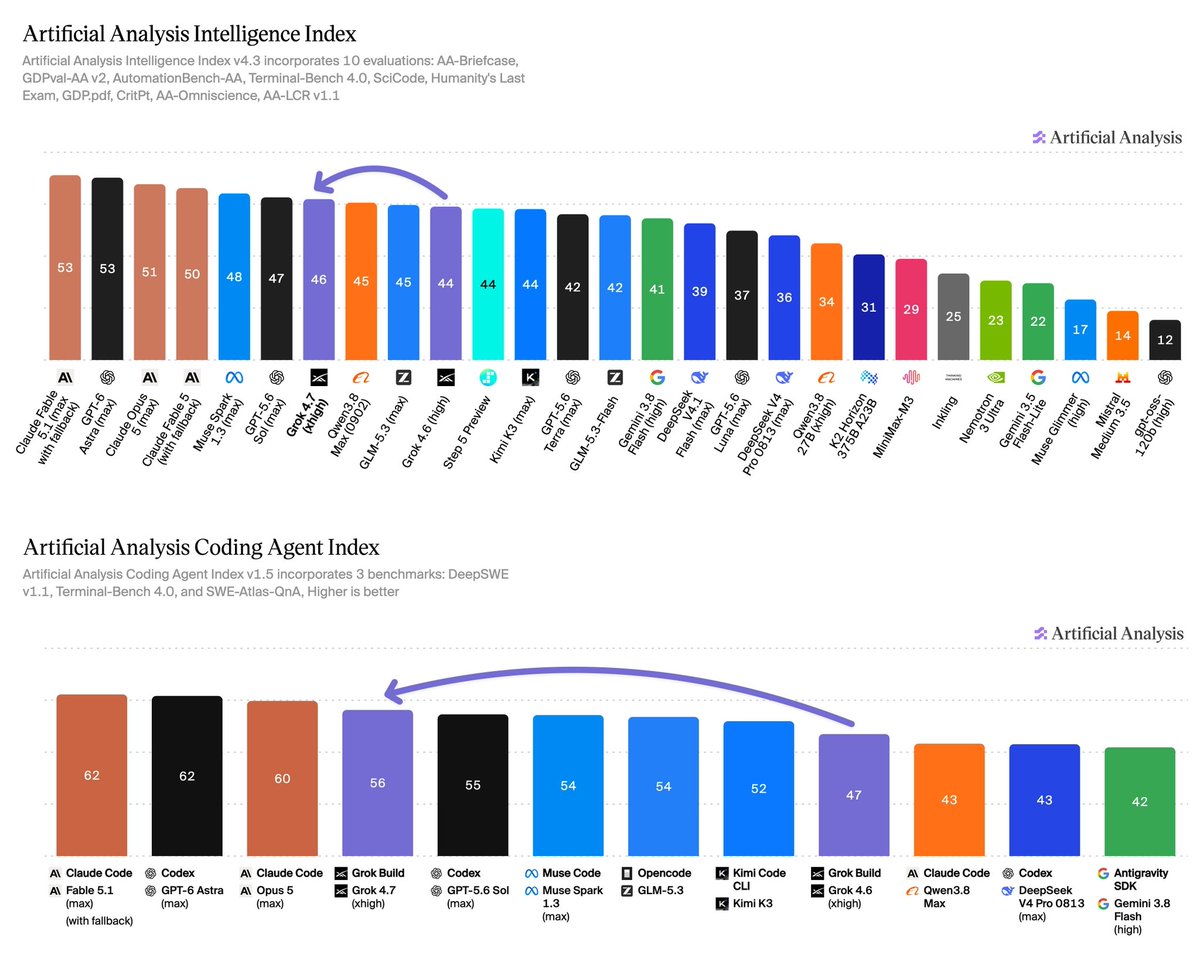
Independent benchmarks back the release up. Artificial Analysis's due diligence benchmark shows Grok 4.7 jumping from 1698 to 1994 in Analytical Quality Elo, trailing only Anthropic's models while costing about half as much per task as Opus 5 on market analysis and deal assessment work. On the Coding Agent Index it gains nine points, landing fourth behind Claude Fable 5.1, GPT 6 Astra, and Claude Opus 5. Cognition added it to Devin and reports 59.4% on FrontierCode 1.1 Extended, calling it strong on hard backend tasks but prone to over scoping compared with Grok 4.6. Vercel's AI Gateway lists a 500K token context window with four reasoning levels, discounted 40% through September 27.
The pattern across sources is consistent. Grok 4.7 buys real capability gains at unchanged pricing, making it a credible cost sensitive option for coding and analytical agent work, even where it still trails the top tier on raw benchmark rank.
Context
Grok 4.7 targets longer coding and knowledge-work tasks. Its developer says it uses a larger base model and a longer reinforcement-learning run weighted toward difficult, multi-hour problems. The intended improvements include checking its work and managing longer , according to the release announcement.
The announcement lists starting API prices of $2 per million input and $6 per million output tokens, matching the listed Grok 4.6 rates. That makes the release a claimed capability improvement at an unchanged base price. A separately priced fast variant trades higher cost for faster output.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…