Ling-3.0-flash gets an open speculative decoding draft model
- Source
- Ant Ling
- Date

Today we are open sourcing Ling-3.0-flash-dspark, a DSpark draft model built specifically for Ling-3.0-flash. On 4 NVIDIA Blackwell GPUs at batch 1, it delivered 1,120 tok/s, 0.78 ms mean TPOT, and an accept length of 9.95 across 1,000 requests. 🧵

Ling-3.0-flash has 42 layers: 35 KDA linear attention layers and 7 MLA full attention layers. Its MoE contains 512 routed experts and one shared expert, with top 8 plus 1 active per token. This hybrid design keeps attention cost low, even at 8K context.
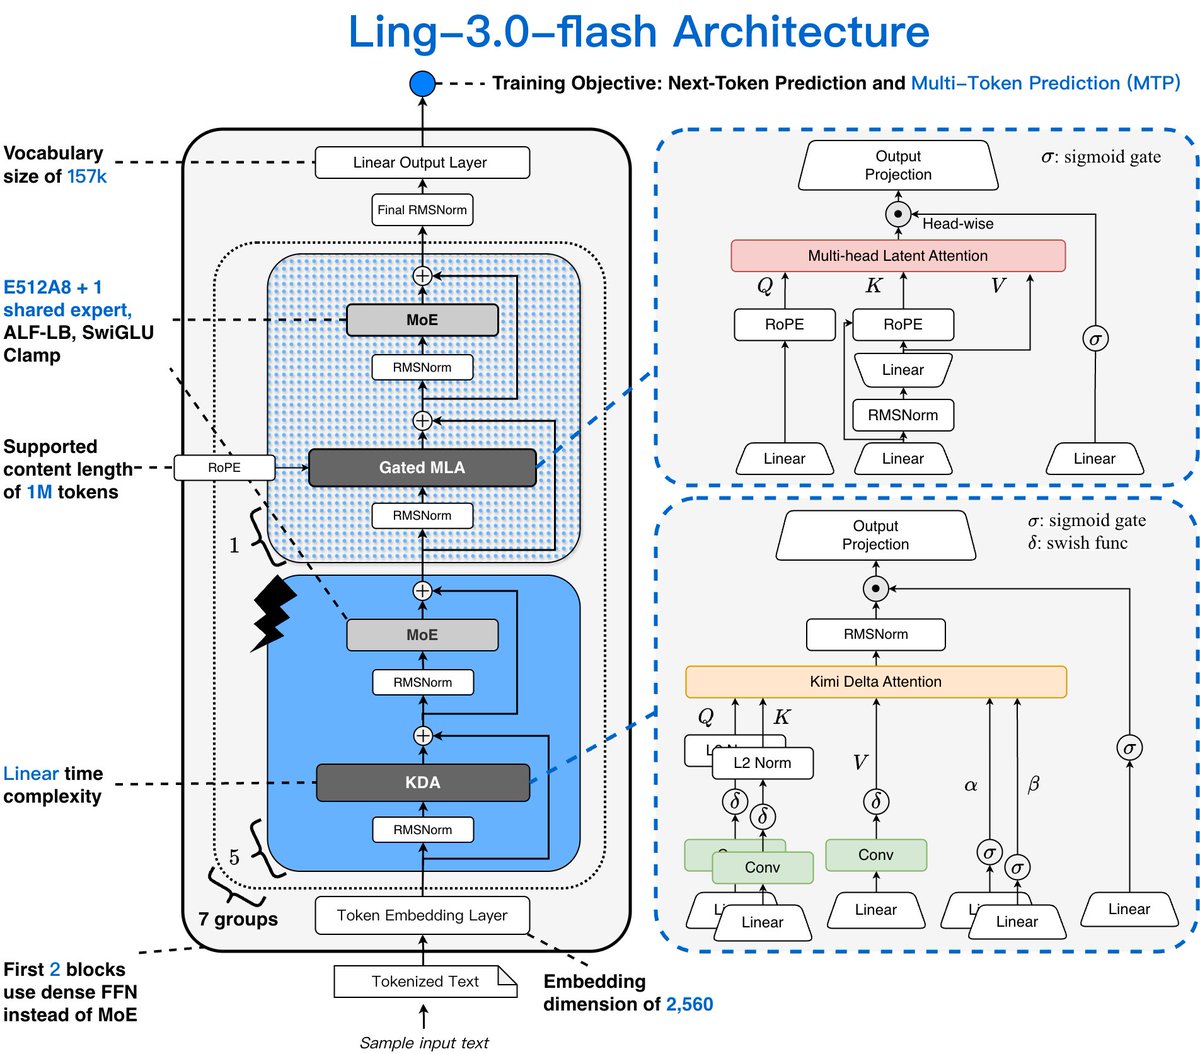
Batch 1 exposes every microsecond. There is no larger batch to absorb launch cost or fill pipeline gaps. On the NEXTN path, our systems work raised mean output throughput from 288 to 606 tok/s and reduced mean TPOT from 3.33 to 1.53 ms.

At batch 1, mean TPOT is roughly step time divided by accept length. We worked on both. SGLang shortened each target step. DSpark uses a parallel draft backbone, a lightweight Markov head for local dependency, and a confidence head for verification scheduling.
Context
speeds up text generation by having a small draft model guess several ahead, which the large target model then checks in one pass. Speed depends on how many guesses in a row are accepted (the accept length) and how long each step takes. Ant Ling open-sourced Ling-3.0-flash-dspark, a DSpark draft model built for Ling-3.0-flash, adapting the public DSpark recipe with distribution-aligned data, architecture ablations, and an acceptance-aware loss.
On 4 NVIDIA Blackwell GPUs at batch size 1 over 1,000 requests, Ant reports its tuned NEXTN method at 606 tokens per second, 1.53 ms mean time per output token, and accept length 3.25, versus 1,120, 0.78 ms, and 9.95 for DSpark. Ant says the 9.95 figure is workload specific: the headline run used static DSpark verification, greedy decoding, 8,192 input tokens, 1,024 output tokens, and synthetic random data. These are Ant's own measurements.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.


Checking sign-in…
Loading comments…